
When converting raw text into numerical features for machine learning models, what is the primary technical distinction between a Bag-of-Words (BoW) model and Word Embeddings?
Select an answer to reveal the explanation.
Short Explanation
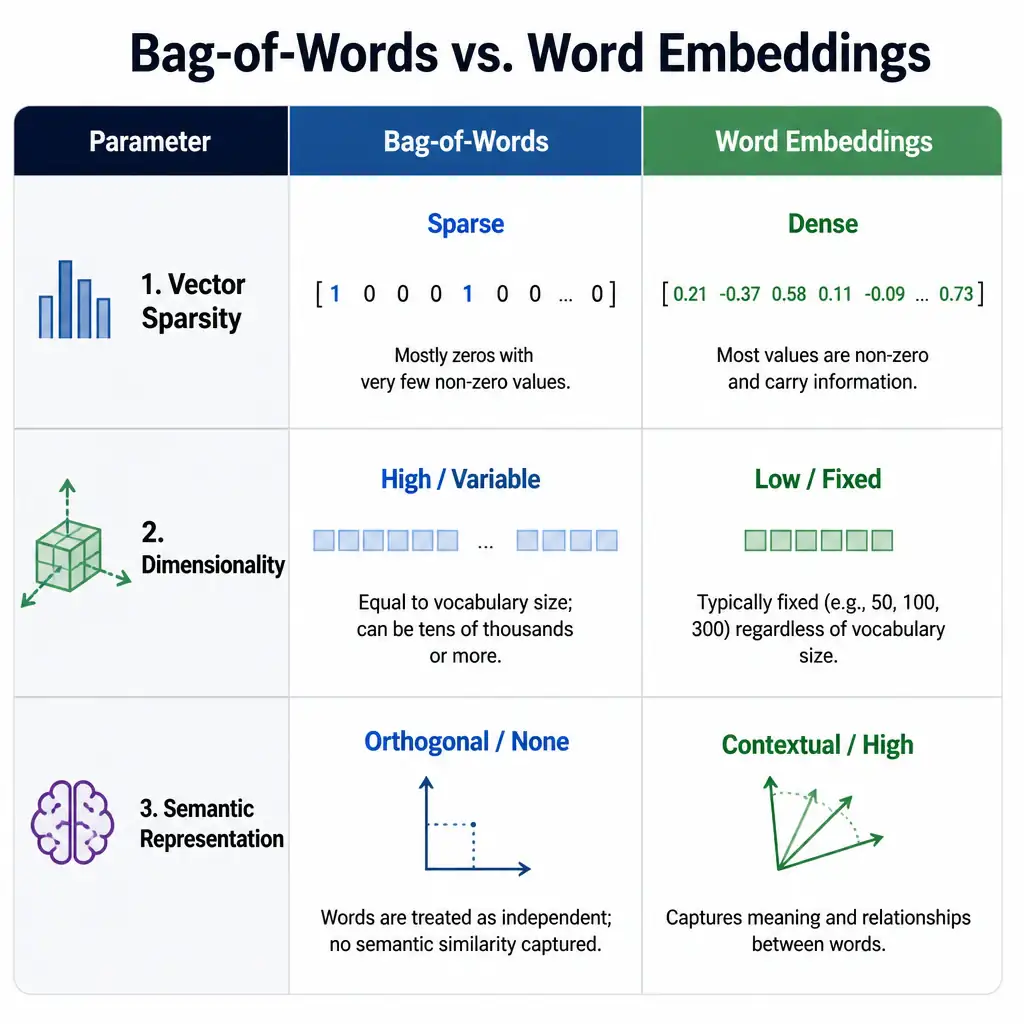
Here's the deal: you can think of Bag-of-Words as a simple inventory check that counts words in a massive, mostly empty vector and ignores relationships between words. Word Embeddings are a completely different animal: they map words to compact, dense vectors where distance captures semantic and syntactic similarity. That's why the high-dimensional sparse frequency versus low-dimensional dense semantic distinction is the right one.
Full Explanation
The choice between Bag-of-Words (BoW) and Word Embeddings represents a shift from sparse, high-dimensional text representations to dense, low-dimensional semantic representations.
1. Bag-of-Words (BoW): - Dimensionality: Equal to the size of the vocabulary, which can range from thousands to millions. - Sparsity: High. Since a single document contains only a small fraction of the total vocabulary, most vector entries are zero. - Semantic Capture: None. BoW treats each word as an independent dimension. The relationship between 'run' and 'running' or 'giant' and 'huge' is lost. - Word Order: Ignored. The sentence 'not good, very bad' and 'not bad, very good' have the exact same representation.
2. Word Embeddings: - Dimensionality: Low and fixed (typically 50 to 300 dimensions). - Sparsity: Dense. Every entry in the vector is a real-valued number representing a projection in a latent semantic space. - Semantic Capture: High. The vectors capture semantic and syntactic relationships based on context, meaning synonyms are close in the vector space.
The correct distinction is that BoW models represent documents as high-dimensional, sparse vectors of word frequencies that ignore word relationships, while Word Embeddings represent words as low-dimensional, dense vectors that capture semantic and syntactic similarity.
The claim that BoW models preserve the sequential order and grammar of words in a sentence, while Word Embeddings treat text as an unordered bag of tokens, is incorrect because standard BoW does not preserve word order, whereas Word Embeddings capture local context during training, though standard embeddings are also combined via averaging/pooling for document-level tasks.
The claim that BoW models require training a deep bidirectional neural network, while Word Embeddings are computed using simple token counting, is incorrect because BoW requires no neural training, it is a count, whereas Word Embeddings are learned via neural models such as Word2Vec or matrix factorization such as GloVe.
The claim that BoW models are designed exclusively for classification tasks, while Word Embeddings can only be used for regression and unsupervised clustering, is incorrect because both representations can be used across various machine learning tasks, including classification, clustering, and regression.