
When training a Transformer-based model like BERT, inputs are padded to ensure all sequences within a training batch have the same length. What is the function of the "attention mask" during the forward pass?
Select an answer to reveal the explanation.
Short Explanation
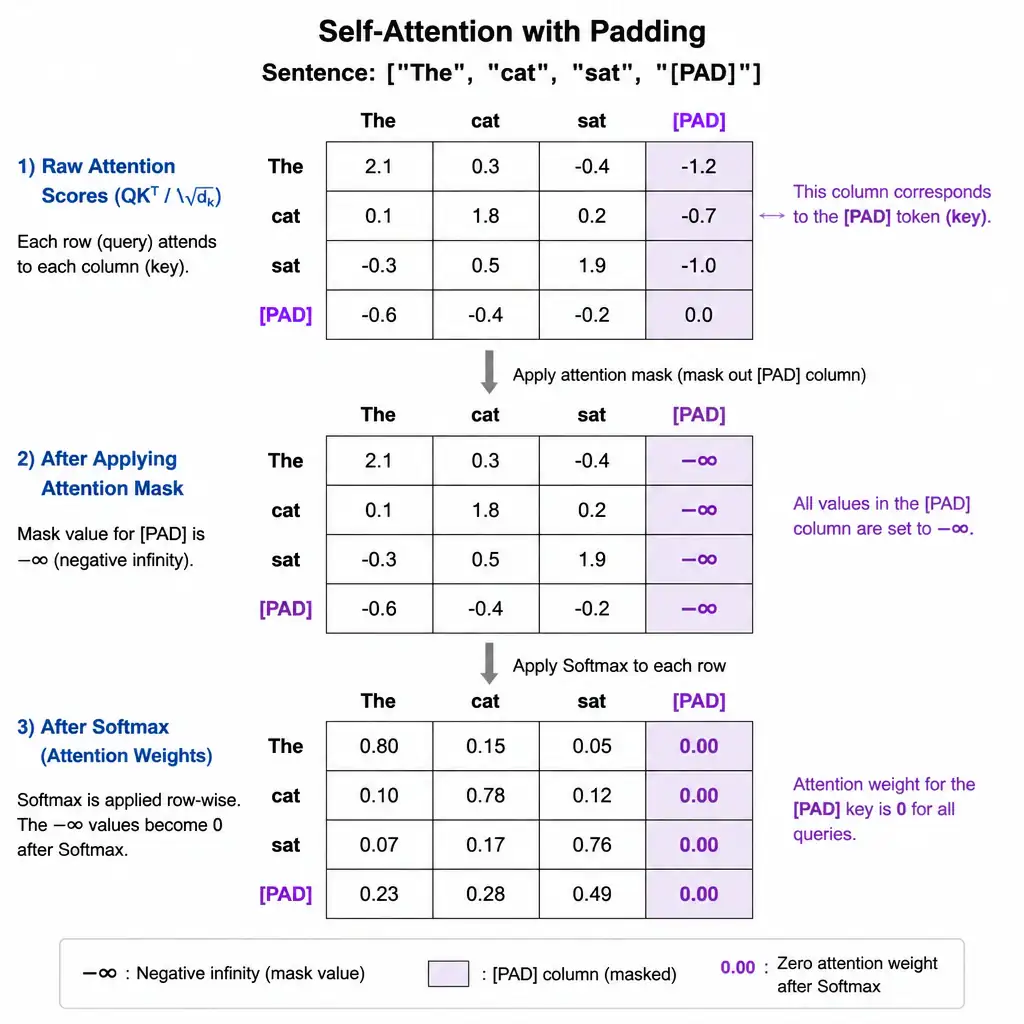
Here's the deal: when you pad a batch, you need a binary mask that tells the model to focus on real tokens and ignore padding tokens. That keeps the padding from contaminating the real words' representations.
Full Explanation
In Transformer architectures, batch processing requires inputs to be structured as uniform tensors of identical shapes. Because sentences vary in length, shorter sequences are padded with placeholder tokens such as [PAD]. To prevent these padding tokens from influencing the representations of actual words, the model uses an attention mask. During the self-attention calculation, Attention(Q, K, V) = softmax((QK^T)/sqrt(d_k) + M)V, where M is the attention mask matrix. For real tokens, the mask value is 0, leaving the attention score unchanged. For padding tokens, the mask value is set to a large negative value, typically negative infinity or -10^9. When softmax is applied, these large negative values are mapped to an attention probability of exactly 0. This mathematical operation ensures that the self-attention mechanism completely ignores the padding tokens, preventing them from corrupting the contextual representation of the sequence. Therefore, the correct answer is the one that says the mask blocks the self-attention mechanism from calculating attention scores for padding tokens, ensuring they do not influence the representations of actual words. The stop-word stripping option is incorrect because stop word removal is a text cleaning step that occurs before tokenization, not during the forward pass of the model. The random token masking option is incorrect because it describes the masked language modeling pre-training objective, where words are replaced with [MASK], which is distinct from the attention mask used to hide padding. The GPU memory removal option is incorrect because padding tokens cannot be physically removed from a tensor during batch processing, as tensor shapes must remain static.