
Large Language Models (LLMs) like GPT-3 or GPT-4 are designed as general-purpose text engines. Which of the following tasks represents a core, primary application for which these models are optimized?
Select an answer to reveal the explanation.
Short Explanation
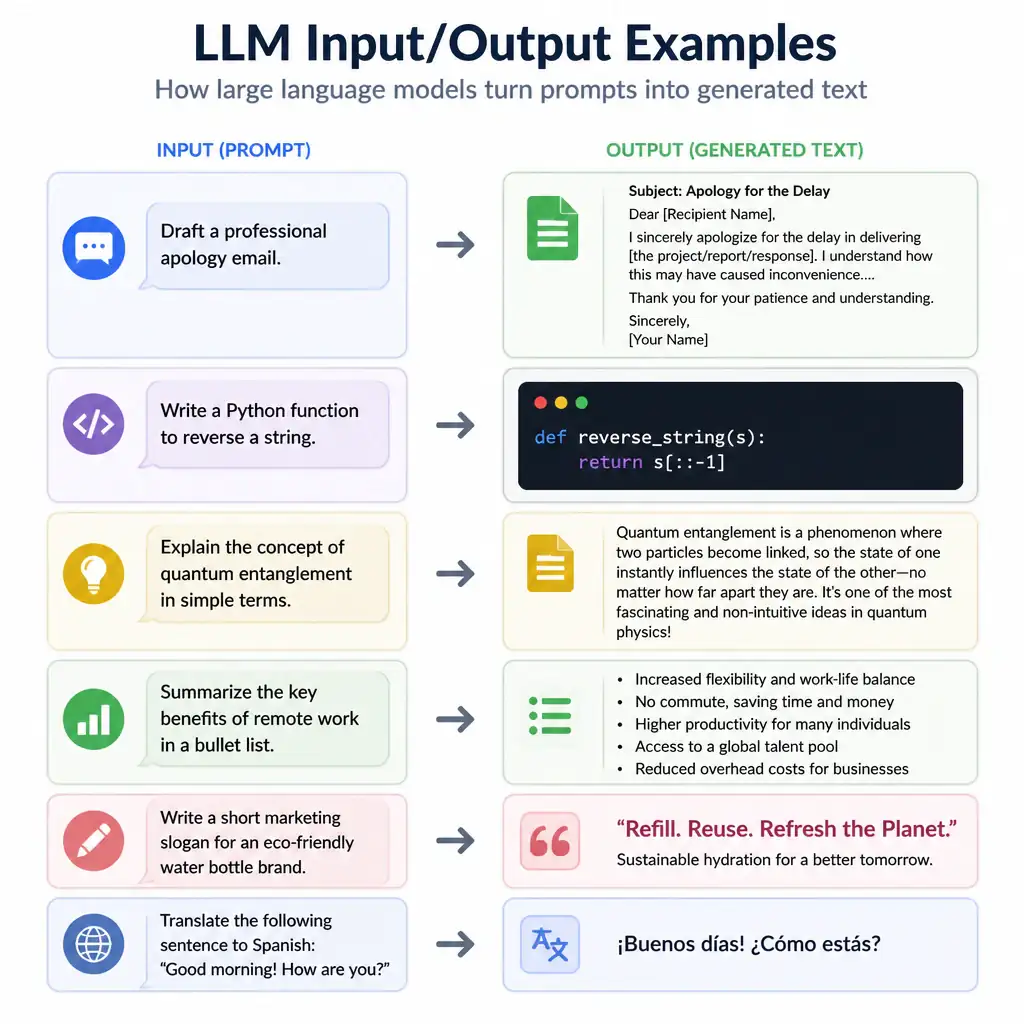
Here's the deal: Large language models like GPT-3 or GPT-4 are word-prediction engines on steroids, so you should use them for generating coherent, contextually relevant natural language text—like article drafts, emails, or code snippets. Don't ask them to predict stock prices, dedupe database records, or run native image classification; that's not what they're optimized for. Stick to text generation and reasoning, and you'll be golden.
Full Explanation
Large Language Models are trained on massive text corpora using self-supervised learning, where the model learns to predict masked or subsequent tokens. Through this pre-training process, they capture syntax, semantics, world knowledge, and context. As a result, their primary strength is generating coherent, contextually accurate natural language text. This enables applications such as automated content creation, drafting emails, summarizing documents, writing and debugging programming code, and engaging in conversational dialog.
Let's dissect why the other options are incorrect: - Calculating real-time algorithmic trades by predicting numeric fluctuations in stock market prices is incorrect because these models are not statistical forecasting tools for numeric time-series data like stock prices. While they can discuss stock concepts, they cannot calculate real-time algorithmic trades. - Performing high-throughput clustering and deduplication of relational database records is incorrect because data consolidation and database deduplication are tasks for data integration pipelines and traditional entity resolution algorithms, not generative language models. - Executing native convolutional image classification to detect defects in manufacturing lines is incorrect because image classification is a computer vision task traditionally solved by convolutional neural networks or vision transformers, rather than standard language models trained on text sequences.