
You are building an email classifier to separate spam from legitimate communications. To keep your vocabulary size manageable and prevent common, uninformative words from skewing the model's predictions, which combination of preprocessing steps should you perform?
Select an answer to reveal the explanation.
Short Explanation
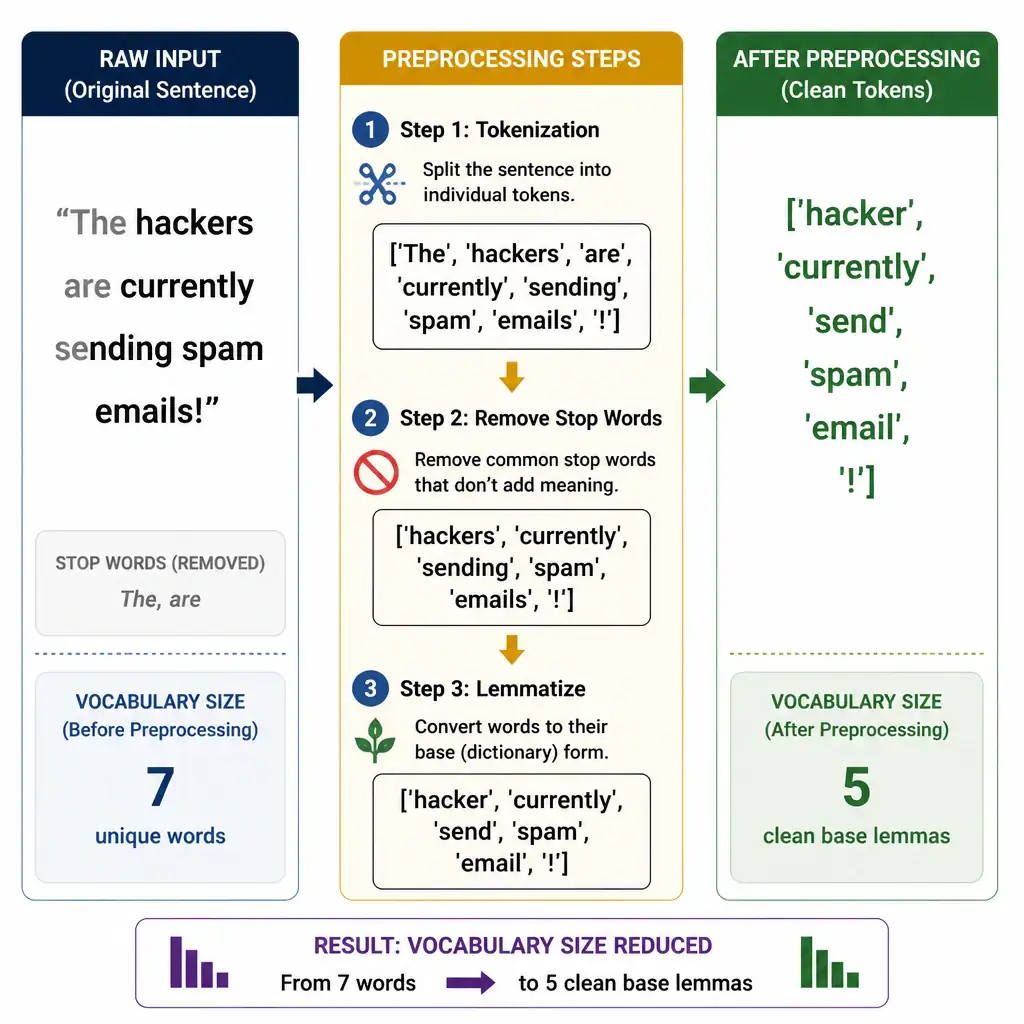
When you're building a spam filter, you need to cut noise without losing meaning. Pairing stemming or lemmatization with stop-word removal collapses variants like 'running' and 'runs' into a base form and drops filler words like 'the' and 'is'. Trust me, your server's memory will thank you!
Full Explanation
Text preprocessing is a critical step in natural language processing, especially for classification tasks like spam filtering. The primary goal of preprocessing is to reduce the dimensionality of the feature space while retaining the semantic core of the message. The correct combination is stemming or lemmatization paired with stop-word removal, because it reduces vocabulary size and removes high-frequency words that carry little task-specific meaning.
Stop words are high-frequency words (such as 'and', 'the', 'a', 'in') that appear in almost all documents but carry little to no task-specific semantic weight. Removing them drastically reduces the total number of features (vocabulary size) the model must track, preventing overfitting and reducing computational resource usage.
Lemmatization is the process of grouping together the inflected forms of a word so they can be analyzed as a single item, identified by the word's lemma (its dictionary form). For example, 'organizes', 'organized', and 'organizing' are all reduced to 'organize'. Unlike stemming, which crudely chops off word endings and can result in non-words, lemmatization uses vocabulary and morphological analysis to return valid base words.
The distractors fail for specific reasons. One-hot encoding and padding only is incorrect because one-hot encoding on its own does not reduce vocabulary size—in fact, it creates a sparse matrix that expands linearly with vocabulary size. Padding is used to standardize sequence lengths, not to shrink vocabulary. Bag-of-words vectorization without tokenization is incorrect because you cannot create a Bag-of-Words representation without first tokenizing the text into individual words or symbols. Direct conversion to tf-idf representations of raw, unmodified text strings is incorrect because building a tf-idf matrix directly from raw, unprocessed text preserves all stop words and morphological variations, leading to a massive, noisy, and inefficient feature space.