
Because Transformer architectures process all tokens in a sequence simultaneously rather than sequentially, they lack an inherent understanding of word order. How do Transformers solve this issue to preserve the structural meaning of a sentence?
Select an answer to reveal the explanation.
Short Explanation
You need positional encodings because Transformers process all tokens at once, so they don't have any natural sense of word order. You add unique mathematical signatures—like timestamps—to word embeddings, so the model knows where each word sits while keeping parallel processing fast. On the exam, remember: no sequential processing means no natural word order, and positional encoding is the fix that saves the day!
Full Explanation
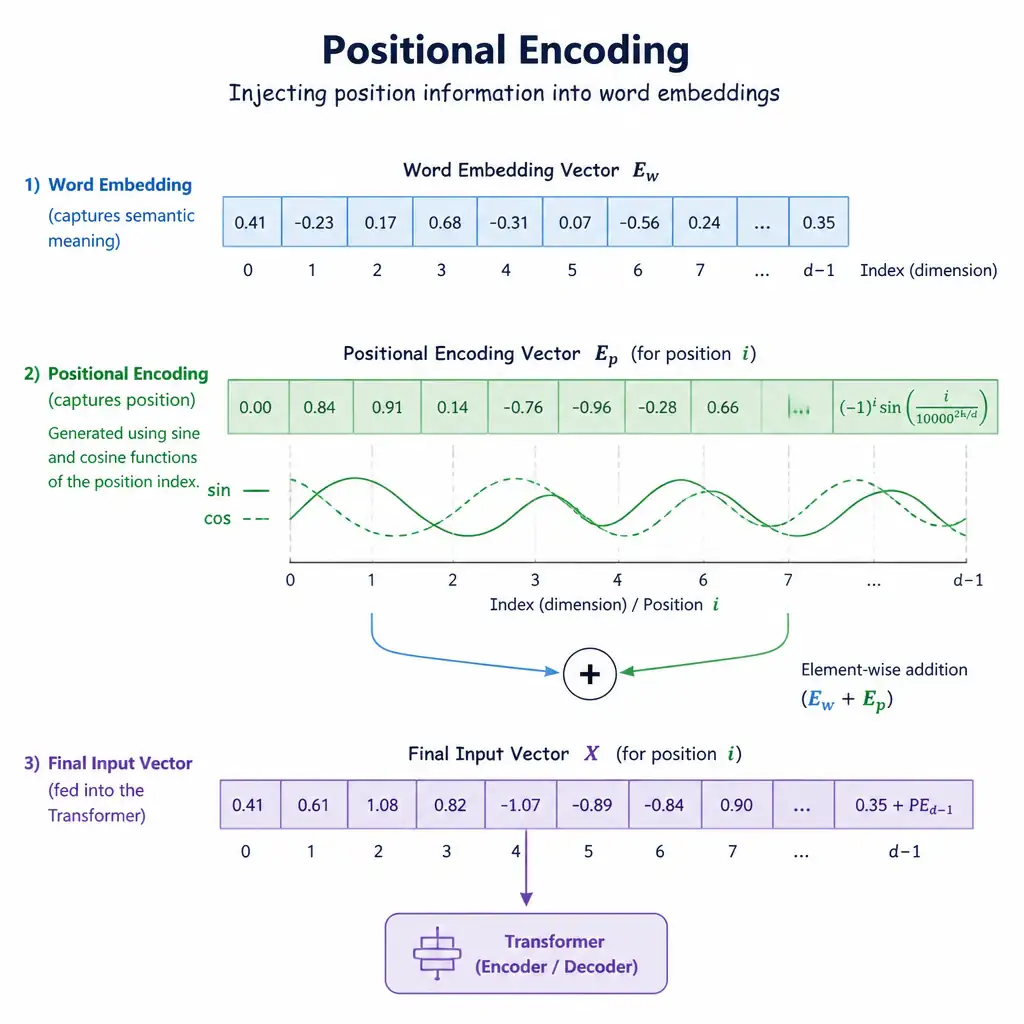
In sequential models like Recurrent Neural Networks, word order is implicitly captured because tokens are processed one step after another. However, the Transformer architecture processes the entire input sequence simultaneously to enable parallel training. While this approach is highly efficient, it makes the model permutation-invariant; without an explicit mechanism, the model would treat 'the dog chased the cat' and 'the cat chased the dog' as identical sets of words. To address this limitation, Transformers use positional encodings. These are vectors added directly to input word embeddings before the data enters the attention layers. The positional encoding vectors contain mathematical values, often calculated using sine and cosine functions of different frequencies, that correspond to the token's absolute or relative position in the sequence. By summing the word embedding vector and the positional encoding vector, the model receives input that combines the semantic meaning of the word and its specific location in the sequence. The recurrent hidden states option, which passes token order information from left to right, is incorrect because recurrent hidden states are features of Recurrent Neural Networks, not Transformers. The convolutional sorting option, which reorganizes words alphabetically before processing, is incorrect because sorting words alphabetically would destroy the grammatical structure of the sentence, not preserve it. The database lookup option, which assigns static grammatical labels such as noun, verb, adjective to each token, is incorrect because static grammatical labels do not provide information about the actual sequential positioning of words in the sentence.