
Which of the following best describes the primary objective of fine-tuning a pre-trained Large Language Model (LLM)?
Select an answer to reveal the explanation.
Short Explanation
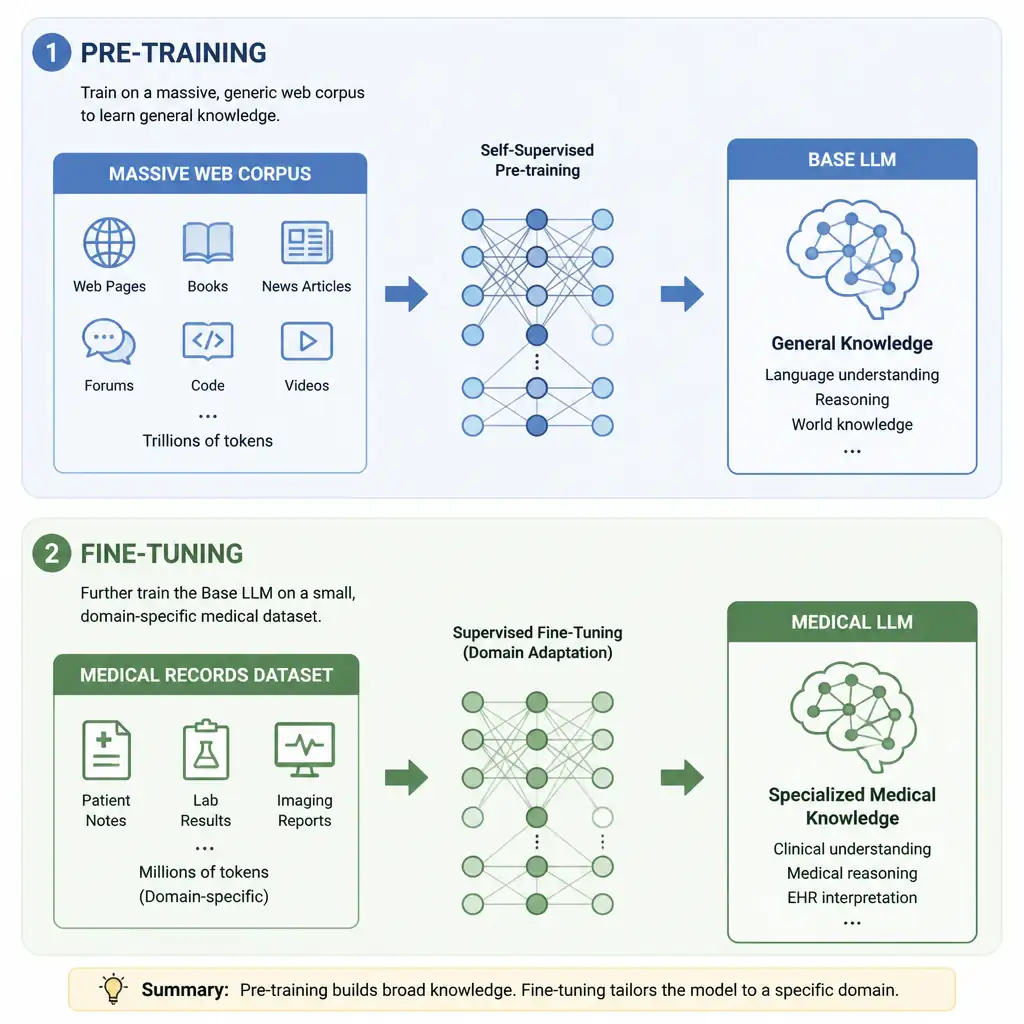
Here's the deal: a pre-trained model already knows general language, but it doesn't automatically know your medical, legal, or code-specific style. You fine-tune it by doing extra training on a smaller, specialized dataset, adapting its existing knowledge to the job without rebuilding it from scratch.
Full Explanation
Fine-tuning is a transfer learning technique where a pre-trained language model is trained further on a target dataset. During initial pre-training, the model learns general language features, grammar, syntax, and broad factual knowledge from massive datasets, such as Wikipedia and web crawls, at a very high computational cost. However, this general model may not perform optimally on highly specialized tasks, such as diagnosing medical symptoms from clinical notes or writing code in a proprietary language. In fine-tuning, the developer takes the pre-trained model and continues training it, performing gradient descent and weight updates, on a much smaller, task-specific dataset. This process adjusts the model's weights to adapt to the specific vocabulary, tone, structure, and objectives of the target domain without losing the general linguistic knowledge acquired during pre-training. The pruning and compression option is wrong because it describes reducing model size and accelerating inference, not adapting the model to new tasks. The randomizing weights option is wrong because randomizing weights would destroy the model's learned language capabilities, rendering it useless. The adding new layers and expanding parameter capacity option is wrong because fine-tuning typically preserves the existing model architecture and parameter count rather than increasing complexity or adding new layers. For the exam, remember that fine-tuning is about adapting a pre-trained model's general capabilities to a specific downstream task using specialized data.