
What is the primary purpose of the self-attention mechanism in a Transformer-based neural network architecture?
Select an answer to reveal the explanation.
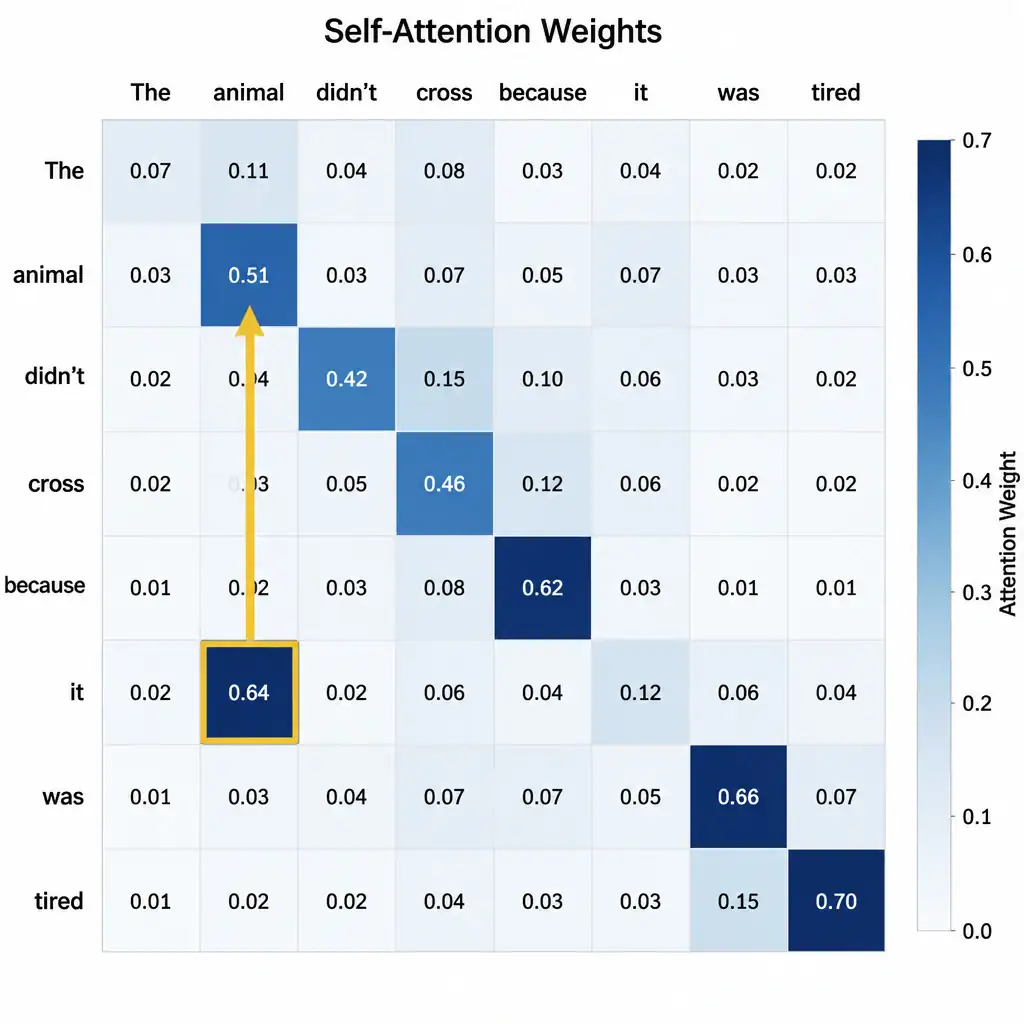
Short Explanation
Here's the deal with self-attention—it lets the model look at every word in a sequence at once and assign dynamic weights to show which other words matter most for the word being encoded. You use it to capture relationships like 'bank' and 'river' instantly, not to process words one by one, shrink embeddings, or drop stop words.
Full Explanation
The primary purpose of self-attention is to dynamically calculate attention weights that determine the relative importance of all other words in a sequence when encoding a specific target word. It is the foundational component of the Transformer architecture, introduced by Vaswani et al. in 2017. Before Transformers, sequence processing relied on Recurrent Neural Networks or LSTMs, which processed tokens sequentially from left to right. This sequential dependency created a bottleneck: it made parallel training impossible and struggled to retain context over long distances due to the vanishing gradient problem. Self-attention addresses these limitations by allowing a model to process the entire sequence of tokens simultaneously. When encoding a specific target word, the mechanism dynamically calculates attention weights for every other word in the sequence, measuring how much focus should be placed on them to capture the target word's context. Internally, each input token's embedding is projected into Query, Key, and Value vectors. The model calculates dot-products between Queries and Keys to produce attention scores, which are scaled and passed through a softmax function to create a weight distribution. These weights are multiplied by the Value vectors to produce a context-aware representation of the target word. This process allows the network to capture long-range dependencies and handle homographs effortlessly. The option describing sequential processing to preserve word order is wrong because that describes Recurrent Neural Networks, while Transformers avoid sequential processing and use positional encodings instead to maintain token order while processing in parallel. The option about compressing word embeddings into lower-dimensional spaces to reduce training time is wrong because self-attention does not compress embeddings; instead, it outputs vectors of the same dimensionality that incorporate context from the rest of the sequence. The option about automatically identifying and filtering out common stop words is wrong because stop-word removal is a pre-processing step that is completely unrelated to the attention mechanisms inside neural networks.