
A developer is preprocessing a large text corpus for an NLP application. They need to choose between stemming and lemmatization for normalization. What is the fundamental difference in how these two techniques reduce words to their base forms?
Select an answer to reveal the explanation.
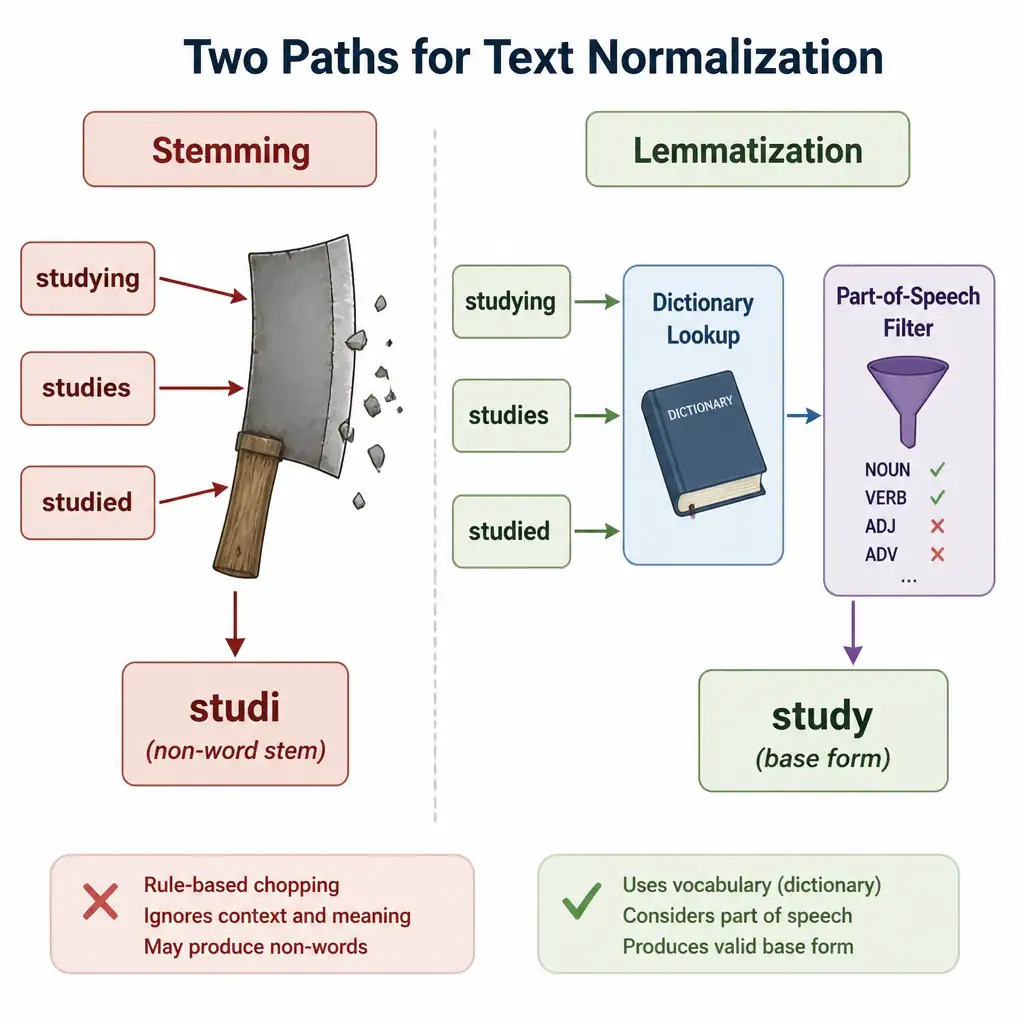
Short Explanation
Think of stemming as a lumberjack with a chainsaw: it hacks off word endings with simple rules and can leave non-dictionary stems. Lemmatization is the careful detective: it uses vocabulary and morphology to return the real dictionary root. Cisco wants you to remember that stemming chops, while lemmatization looks up the true lemma.
Full Explanation
Text normalization is a crucial preprocessing step in Natural Language Processing (NLP) designed to reduce vocabulary size by mapping different forms of a word to a common base. Stemming and lemmatization are the two primary techniques used to achieve this, but they operate under completely different mechanisms and yield different results.
Stemming relies on simple, rule-based heuristics to strip common prefixes or suffixes (like '-ing', '-ed', or '-es') from the ends of words. The Porter Stemmer uses a cascade of rules to prune words. Because stemming does not possess any understanding of grammar, syntax, or context, it often produces truncated strings that are not valid dictionary words. For example, the words 'arguing', 'argued', and 'argues' might all be reduced to the stem 'argu'. While stemming is computationally fast, lightweight, and requires no external vocabulary databases, its crude nature can lead to under-stemming (failing to reduce related words to the same root) or over-stemming (reducing unrelated words to the same root, such as mapping 'universal' and 'university' both to 'univers').
Lemmatization, by contrast, performs a full morphological and grammatical analysis of the word. It leverages a vocabulary database (such as WordNet) and takes into account the word's part of speech (POS) and context to resolve it to its actual dictionary base form, known as a lemma. Under lemmatization, 'is', 'was', and 'am' all resolve to 'be', and 'better' resolves to 'good'—relationships a stemmer could never identify. This makes lemmatization highly accurate and semantically precise, although it is computationally more expensive and has a larger memory footprint.
The correct choice is the one that says stemming chops off the ends of words using heuristic rules, often resulting in non-dictionary base forms, whereas lemmatization uses vocabulary and morphological analysis to return valid dictionary root words. That matches the mechanisms above: stemming is rule-based truncation, while lemmatization is dictionary- and morphology-aware normalization.
The reversed definition that claims stemming uses dictionary-based lookup to find the true root form, whereas lemmatization applies crude heuristic rules to chop off prefixes and suffixes, is incorrect because it swaps the two techniques. The claim that stemming is only applicable to English verbs and nouns, whereas lemmatization is language-agnostic and can process any part of speech, is incorrect because stemming can be applied to any part of speech and is not restricted to English verbs and nouns. The claim that stemming and lemmatization are functionally identical, but stemming is computationally slower due to its dependency on context and database lookups, is incorrect because the two techniques are fundamentally different, and stemming is actually much faster than lemmatization, not slower, since it does not perform database lookups or contextual analysis.