
While preparing a text dataset for a machine learning model, you decide to filter out words like "the", "is", "at", and "which" because they appear frequently but carry very little semantic information. What is this preprocessing step called?
Select an answer to reveal the explanation.
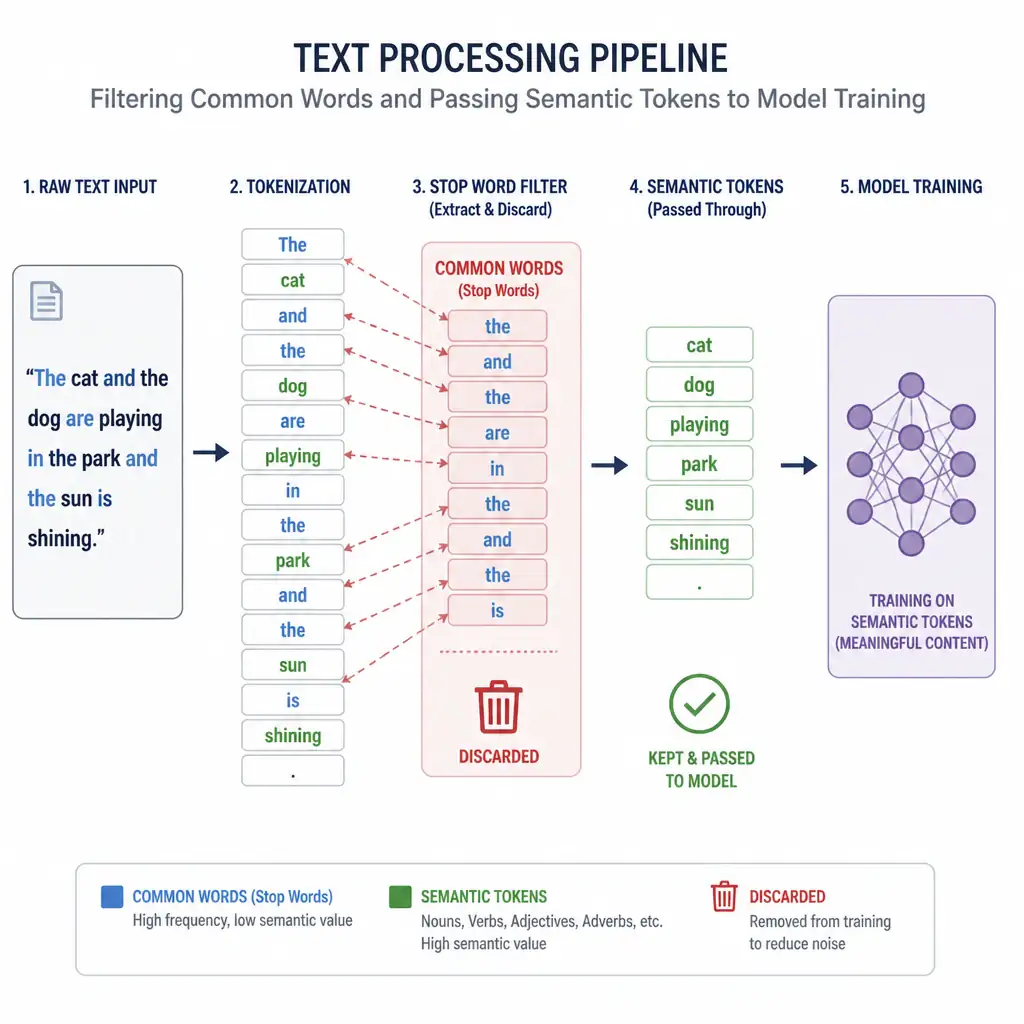
Short Explanation
Think of it like this: you skip filler words like 'the', 'is', 'at', and 'which' because they're grammatical glue, not meaning. That cleanup step is removing stop words. Don't confuse it with tokenization or stemming.
Full Explanation
Stop words are high-frequency words that are commonly filtered out during text preprocessing in natural language processing pipelines. While crucial for grammatical coherence in human communication, they lack unique semantic content for information retrieval and document classification.
Removing stop words is the process of discarding these common, low-information words from the dataset to focus analysis on semantically dense terms.
Tokenization is incorrect because it is the initial step of splitting a string of text into smaller units, such as words or punctuation, but it does not filter out any data.
Stemming is incorrect because it reduces words to their word stem or root form, such as 'arguing' to 'argu', but it does not delete words from the corpus.
Part-of-speech tagging is incorrect because it is the process of marking up a word in a text as corresponding to a particular part of speech, such as noun, verb, or adjective, based on its definition and context.