
Imagine you are using a Term Frequency-Inverse Document Frequency (TF-IDF) vectorizer to analyze a collection of technical articles. If a specific word receives a high TF-IDF score within one particular document, what does this indicate about that word?
Select an answer to reveal the explanation.
Short Explanation
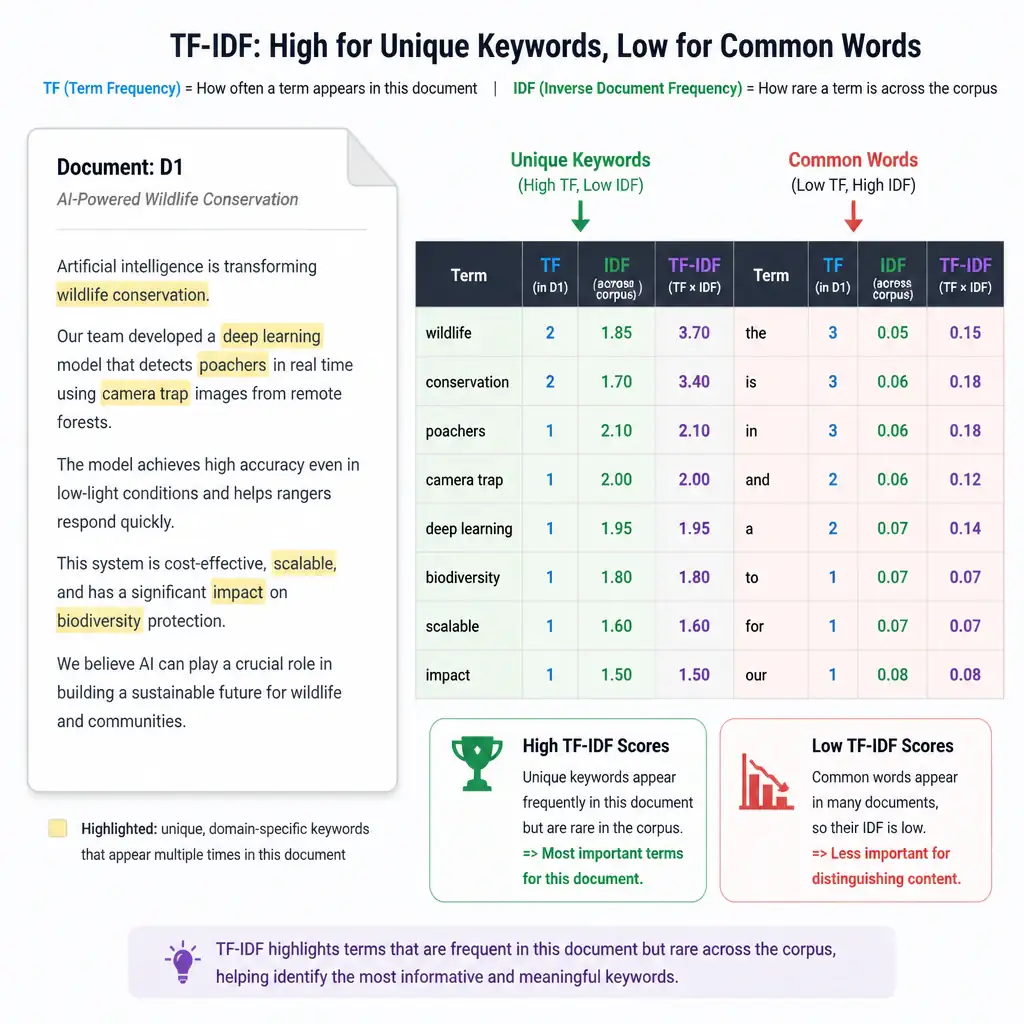
Think of it like this: if you see a word popping up over and over in one article but hardly anywhere else, that's a big clue about what makes that article unique. TF-IDF rewards high frequency in the document and penalizes words that show up everywhere, so a high score means the word is highly representative of that document's content.
Full Explanation
Term Frequency-Inverse Document Frequency (TF-IDF) is a statistical measure used to evaluate how important a word is to a document in a collection or corpus. The importance increases proportionally to the number of times a word appears in the document but is offset by the frequency of the word in the corpus.
The answer stating that the word appears frequently in this specific document but is rare across the rest of the corpus, making it highly representative of this document's unique content, is correct. A high TF-IDF score is achieved when a term has a high term frequency in a specific document but a low document frequency across the overall corpus, meaning it is a strong indicator of that document's unique content.
The answer stating that the word is a common stop word that carries very little semantic meaning but appears frequently in all documents is incorrect. Common stop words, like the and is, appear across almost all documents, which gives them a very low inverse document frequency score, resulting in a low TF-IDF score.
The answer stating that the word is a rare typographical error or noise that should be filtered out during preprocessing is incorrect. While typos might be rare in the corpus, a typo would only receive a high TF-IDF score if it were repeated frequently within a single document. However, TF-IDF is not designed to identify typos, but rather to evaluate term importance.
The answer stating that the word is extremely common across every document in the corpus, serving as a general domain identifier, is incorrect. If a word is common across the entire corpus, its document frequency is high, which drives the inverse document frequency component toward zero, resulting in a very low TF-IDF score.