
In a multi-class classification neural network, what is the primary role of the softmax activation function when applied to the output layer?
Select an answer to reveal the explanation.
Short Explanation
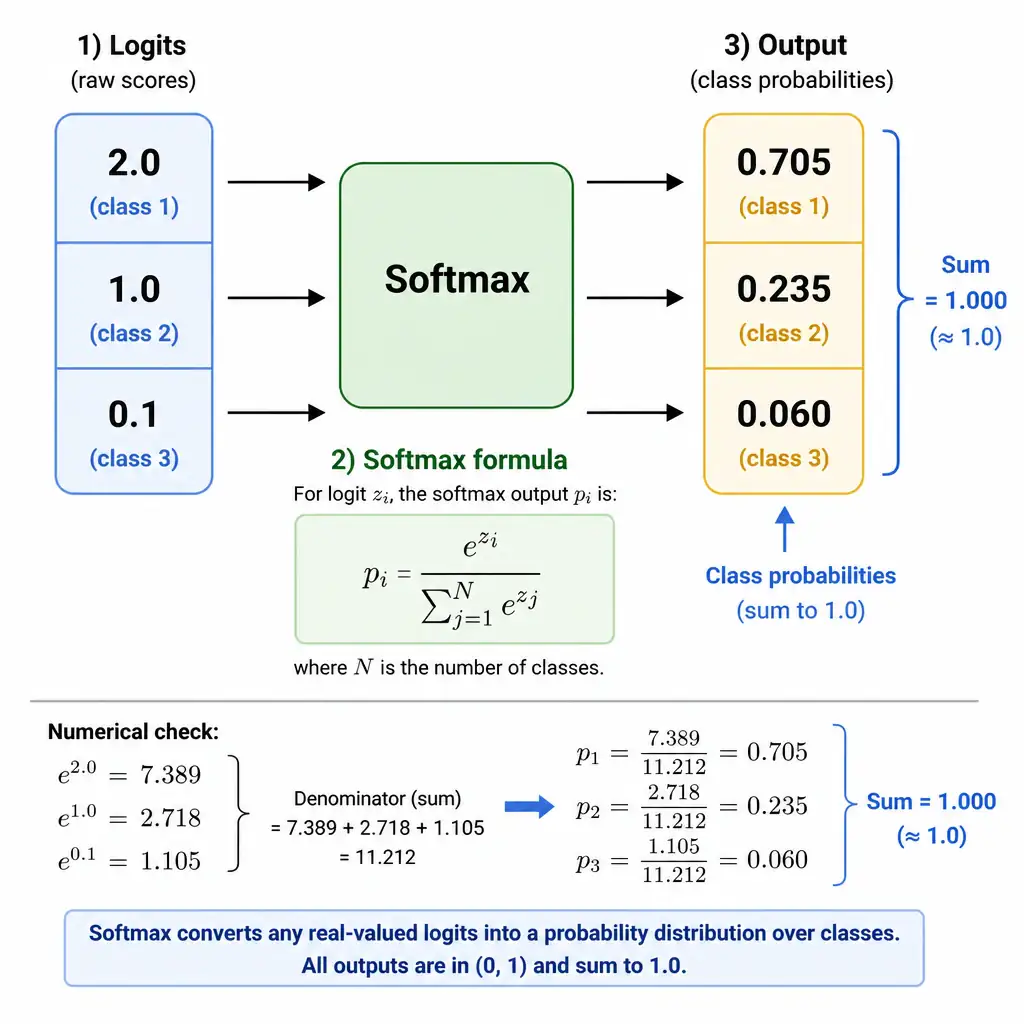
When your network finishes calculating everything for a multi-class problem, it outputs raw scores called logits. Softmax squashes those scores into values between 0 and 1 and makes them add up to exactly 1.0, so you can read them as class probabilities.
Full Explanation
In deep learning, the final layer of a neural network designed for multi-class classification generates a vector of raw, unnormalized real values called logits. The softmax function is applied to these logits to transform them into a probability distribution. Mathematically, for a vector of class scores, the softmax function converts the logits using exponentials normalized by the sum of exponentials of all logits. The exponential function ensures that all resulting outputs are positive. Dividing by the sum of exponentials normalizes the vector such that each value falls within the range (0, 1) and the sum of all values is exactly 1. This allows the network's output to be interpreted as a probability distribution over the classes, where the class with the highest probability is selected as the prediction. Let's look at why the other choices are wrong: the choice about normalizing input features to a standard scale between 0 and 1 before training refers to feature scaling or input normalization, which is done during preprocessing, not in the output layer. The choice about mapping a single real-valued output to a binary 0 or 1 decision boundary refers to the Sigmoid function, which is used for binary classification tasks (mapping a single output to a value between 0 and 1) rather than multi-class probability vectors. The correct answer is the choice that converts a vector of raw model outputs (logits) into a probability distribution where all values sum to 1. The choice about performing a linear matrix multiplication of weights and inputs refers to the linear layers (dense/fully connected layers) themselves, which perform linear transformations before the activation function is applied. For the exam, remember that Softmax is the standard for multi-class classification because it outputs a probability distribution summing to 1.