
What design feature allows Long Short-Term Memory (LSTM) networks to successfully capture long-range temporal dependencies compared to standard Recurrent Neural Networks (RNNs)?
Select an answer to reveal the explanation.
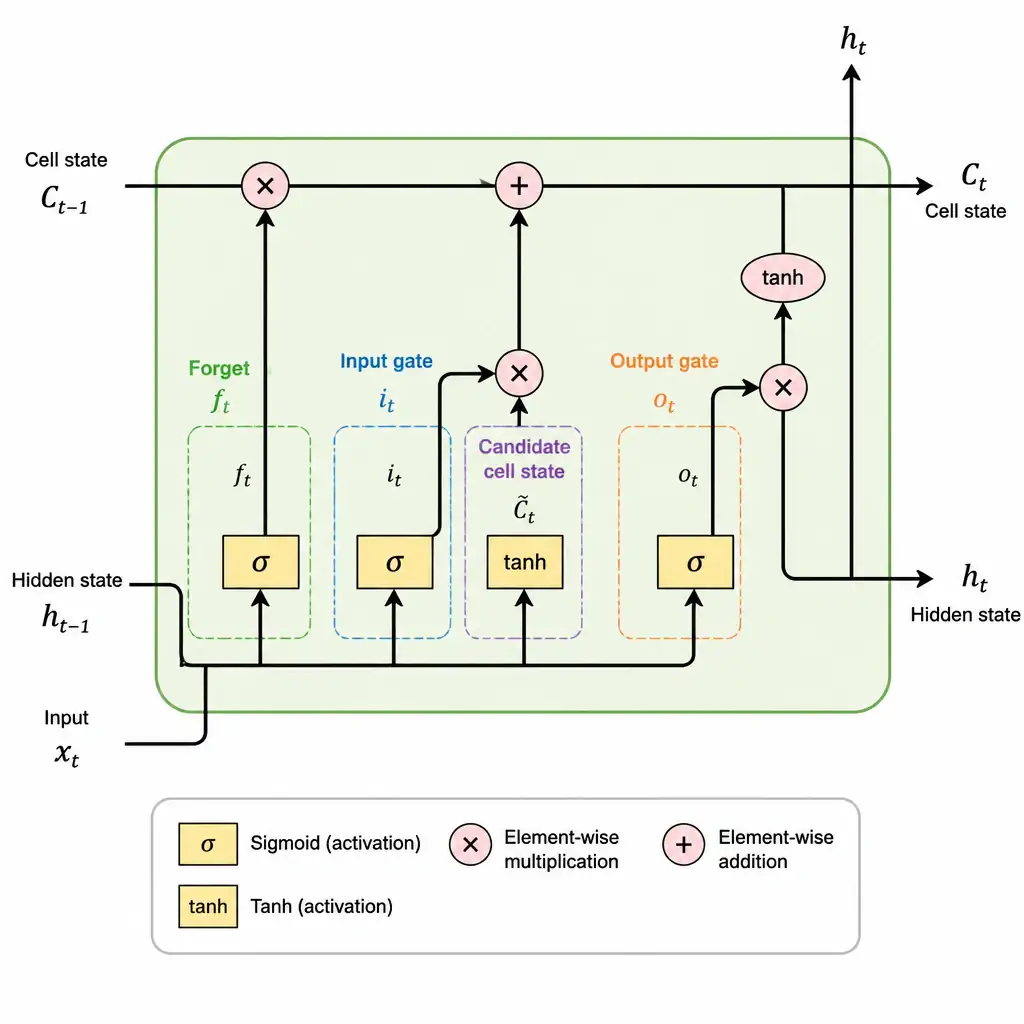
Short Explanation
Standard RNNs lose long-range memory because gradients vanish over time. LSTMs fix that with a cell state and gates that control what's kept, added, and passed on, so information can travel far without fading. You get long-term dependencies without the vanishing-gradient mess.
Full Explanation
Standard Recurrent Neural Networks (RNNs) suffer from vanishing gradients when backpropagating through long sequences, which prevents them from learning long-term dependencies. Long Short-Term Memory (LSTM) networks, introduced by Hochreiter & Schmidhuber, solve this problem by redesigning the recurrent unit structure. The core of an LSTM is the cell state (often described as a conveyor belt or memory cell), which runs straight down the entire chain of units with only minor linear interactions. The flow of information to and from the cell state is regulated by three neural network layers called gates: the forget gate decides what information from the previous cell state should be discarded using a sigmoid activation function; the input gate decides which new information from the current input should be stored in the cell state; and the output gate decides what the next hidden state should be based on the updated cell state. Because the cell state update involves linear addition rather than repeated matrix multiplication, gradients can flow backward through time without vanishing, allowing LSTMs to effectively learn long-term sequences. The option that restricts sequence length to short, fixed-size windows is incorrect because LSTMs are specifically designed to handle long sequences, not restrict them. The option that eliminates recurrent loops and relies solely on feedforward dense layers is incorrect because LSTMs are recurrent architectures, not pure feedforward networks. The option that uses parallel spatial feature extraction pipelines optimized exclusively for image-based inputs is incorrect because LSTMs are sequence models used for text, audio, and similar sequential data, not specialized computer vision networks. For the exam, memorize the three gates (forget, input, output) and the cell state as the defining components of an LSTM that resolve the vanishing gradient issue.