
A developer training a deep neural network observes that the weights in the early layers update extremely slowly, while the gradients shrink exponentially during the backward pass. What is this common training challenge called?
Select an answer to reveal the explanation.
Short Explanation
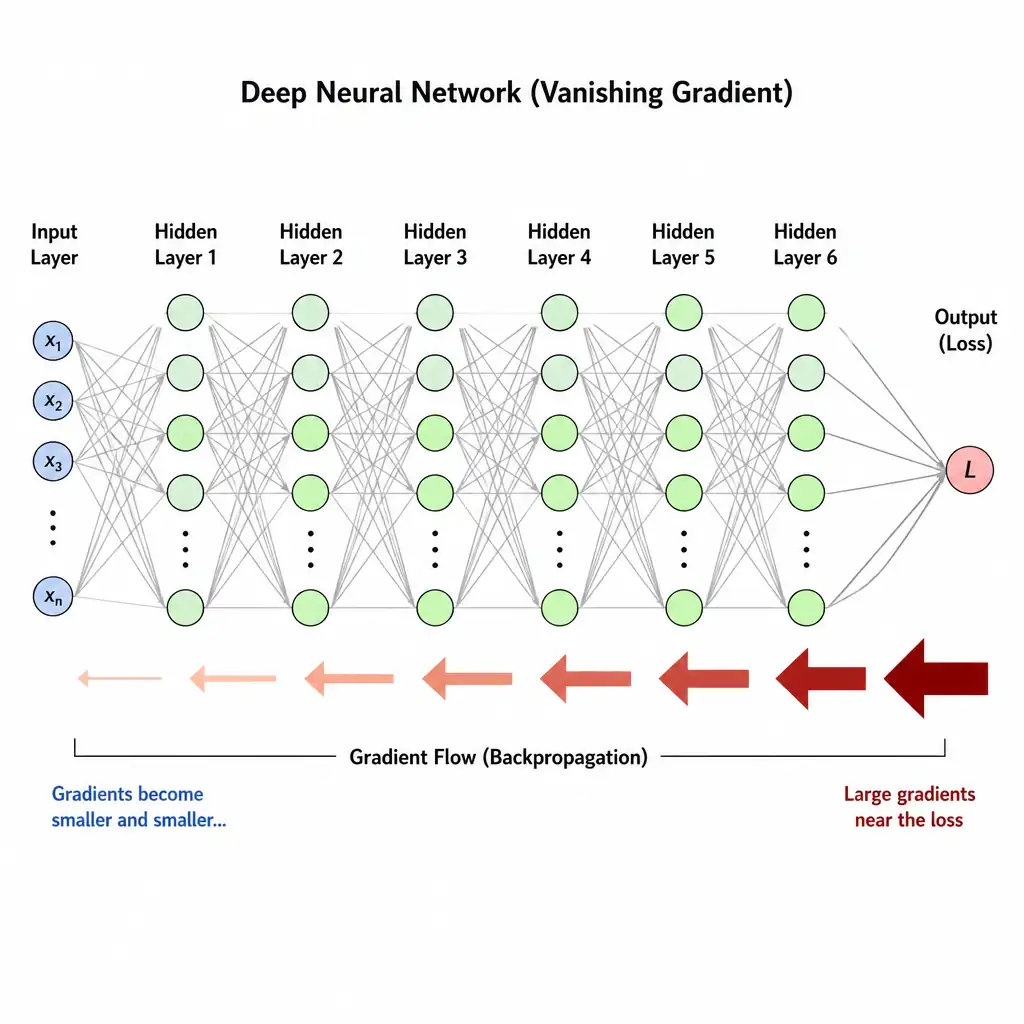
Here's the deal: when you train a really deep neural network, backprop multiplies derivatives all the way back to the early layers. If those derivatives are small, the gradients shrink exponentially, so the early weights barely update. That's the vanishing gradient problem.
Full Explanation
The phenomenon described is known as the vanishing gradient problem. In deep neural networks, weights are updated proportionally to the partial derivatives of the loss function with respect to those weights, which are calculated using the chain rule during backpropagation.
As backpropagation moves from the output layer back toward the input layer, the gradient is repeatedly multiplied by the derivatives of the activation functions. If these derivatives are less than 1, which is common for activation functions like Sigmoid or Tanh, where the maximum derivative is 0.25 and 1.0 respectively but often much lower in saturation regions, the gradient shrinks exponentially with each added layer. By the time the gradient reaches the initial layers of a deep network, it becomes extremely close to zero. Consequently, the weights in these early layers undergo virtually no adjustment, preventing the model from learning the fundamental low-level features of the input data and stalling overall training. This is why deep networks were historically hard to train until ReLU activations and residual connections became common.
Overfitting is when a model learns the noise and details of the training data too well, resulting in poor generalization to new validation data. It is not characterized by vanishing gradients during training.
Exploding gradients is the opposite problem, where gradients accumulate and grow exponentially, leading to extremely large weight updates, numerical overflow (NaNs), and unstable training.
Underfitting occurs when a model is too simple to capture the underlying pattern of the data. While vanishing gradients can cause underfitting, the specific mechanism of shrinking gradients in early layers is named the vanishing gradient problem.