
Which activation function is most widely used in the hidden layers of deep neural networks because its linear, non-saturating nature for positive inputs helps mitigate the vanishing gradient problem?
Select an answer to reveal the explanation.
Short Explanation
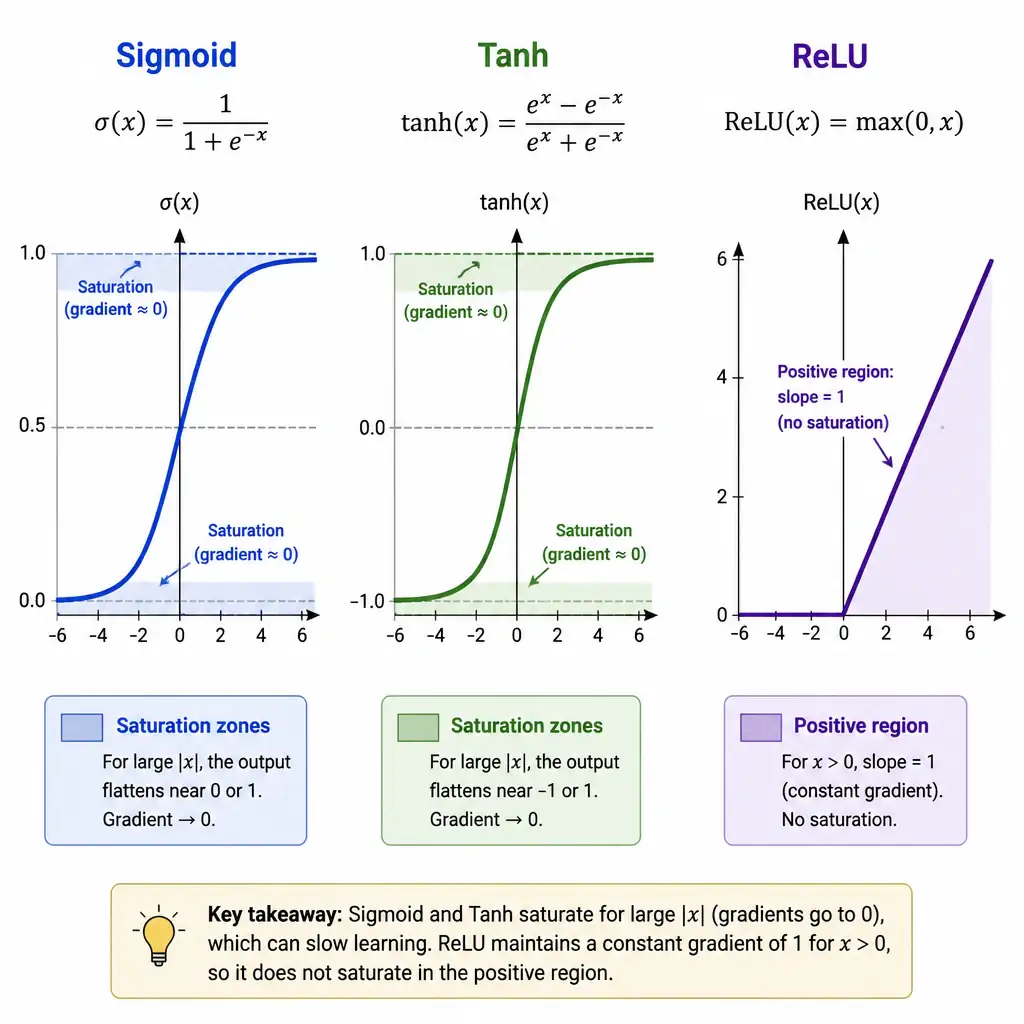
When you're training a deep neural network, you need gradients to keep flowing through the hidden layers. ReLU gives positive inputs a constant slope of 1, so it avoids the saturation that makes sigmoid and tanh stop learning. That's why it's the go-to activation for hidden layers.
Full Explanation
The choice of activation function in hidden layers determines how well a deep neural network can propagate error gradients during backpropagation. The Rectified Linear Unit (ReLU) activation function, which outputs f(x) = max(0, x), is widely used because it addresses the vanishing gradient problem that plagues alternative activation functions.
Sigmoid and Hyperbolic Tangent (Tanh) activation functions are saturating functions. As their input values move away from zero, their outputs flatten toward their asymptotic limits (0 and 1 for Sigmoid; -1 and 1 for Tanh). In these saturated regions, the derivatives of these functions approach zero. During backpropagation, when these small derivatives are multiplied through the layers, the overall gradient decreases exponentially. This results in the vanishing gradient problem, preventing the weights of early layers from being updated. ReLU prevents this saturation for all positive inputs (x > 0) because its derivative is constant at 1. Consequently, gradients can flow back through deep networks without scaling down, allowing for effective training of many layers.
The softmax function is used in the output layer of multi-class classification networks to convert raw scores (logits) into a probability distribution that sums to 1. It is not suitable for hidden layers. The sigmoid function is a saturating activation function that suffers from the vanishing gradient problem, making it poorly suited for the hidden layers of deep networks. The hyperbolic tangent (Tanh) function is also a saturating activation function that suffers from the vanishing gradient problem, making it poorly suited for the hidden layers of deep networks.