
You are training a machine learning model to detect credit card fraud, where only 0.1% of the transactions in your dataset are actually fraudulent. Which data-level technique should you use to prevent the model from simply predicting 'not fraud' for every transaction?
Select an answer to reveal the explanation.
Short Explanation
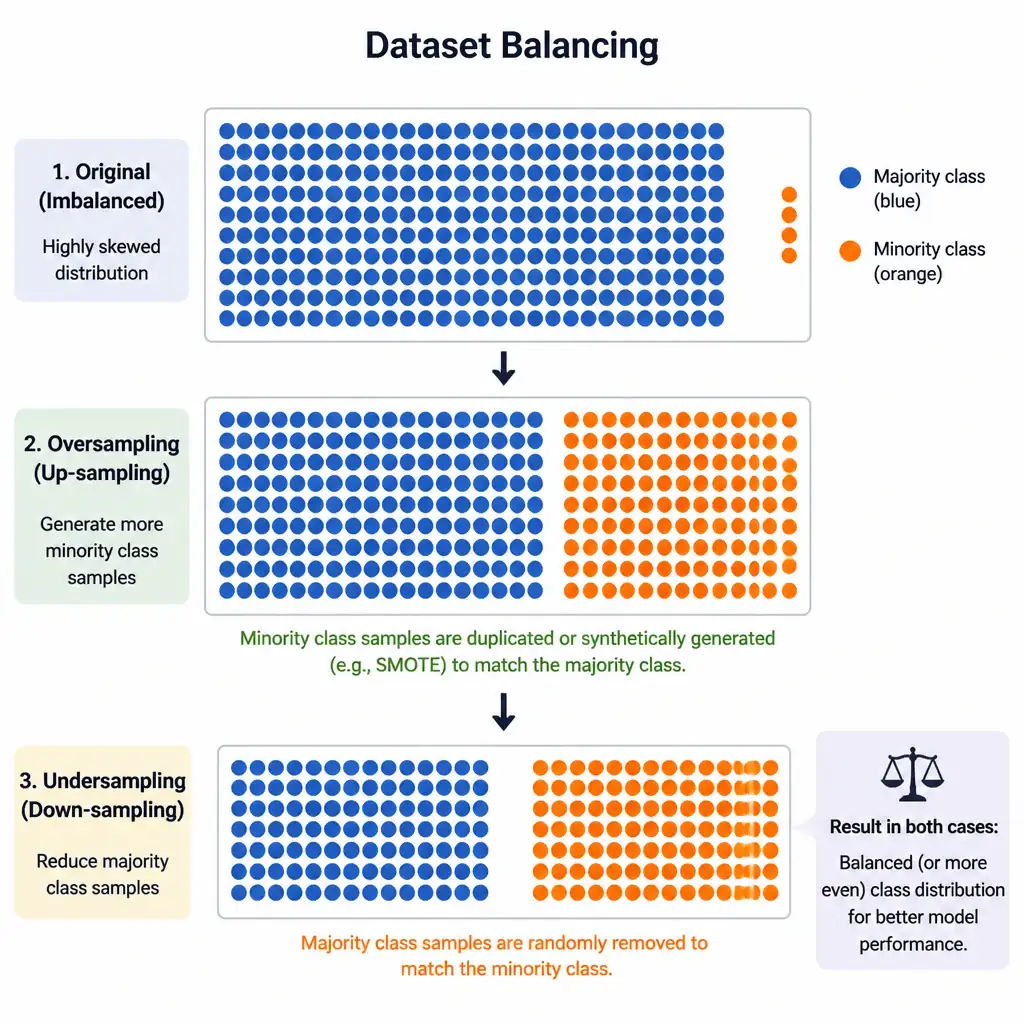
If 99.9% of your transactions are normal and only 0.1% are fraud, your model can look great by just saying 'not fraud' every time. You need to balance the scales by resampling: oversample the rare fraud cases or undersample the normal transactions so the model actually learns both patterns.
Full Explanation
Class imbalance occurs when one class vastly outnumbers the other in a classification dataset. Standard machine learning algorithms are designed to maximize overall accuracy, which biases them heavily toward the majority class. To resolve this at the data level, use resampling techniques: oversampling increases the size of the minority class, either by duplicating existing samples or synthetically generating new ones using Synthetic Minority Over-sampling Technique; undersampling reduces the size of the majority class by randomly or strategically removing samples to balance the class distribution. Using resampling helps ensure that the model receives enough signal from the minority class to learn its characteristics and make reliable predictions. The Principal Component Analysis approach is a dimensionality reduction technique used to project high-dimensional data into a lower-dimensional space, which does not address the ratio of class representations. The gradient descent approach with a high learning rate is an optimization method used to update model weights to minimize the loss function; adjusting the learning rate does not fix the underlying data imbalance. The cross-validation approach that splits data into training and testing folds is a validation strategy to assess model generalization, but it does not modify the class distribution of the training data.