
When training a machine learning model using gradient descent, what is the primary consequence of setting the learning rate to an excessively small value?
Select an answer to reveal the explanation.
Short Explanation
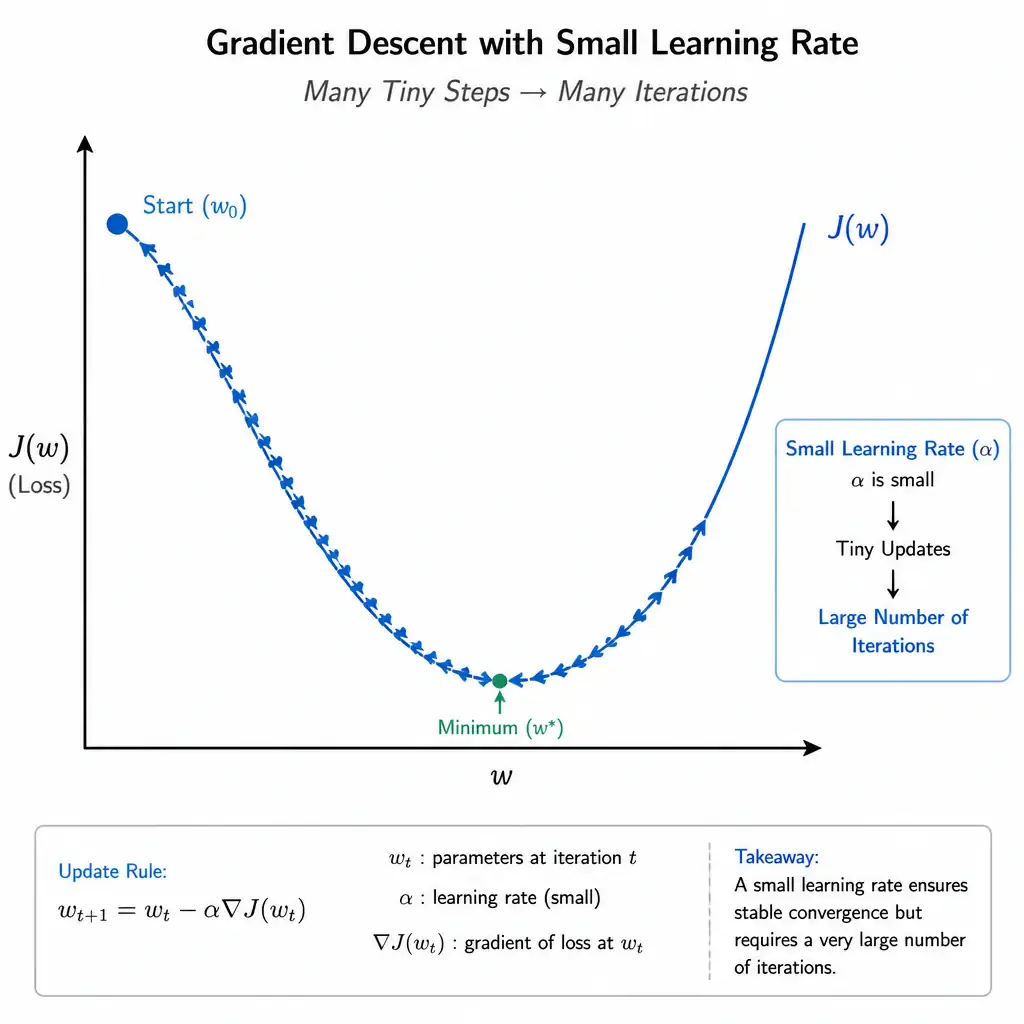
Here's the deal: an excessively small learning rate makes each weight update tiny, so you crawl toward the minimum. You'll burn through compute time and budget long before training finishes, because convergence becomes extremely slow.
Full Explanation
In gradient descent optimization, the learning rate (often denoted as alpha or eta) is the crucial hyperparameter that determines the step size taken in the direction of the negative gradient during each weight update. The primary consequence of setting it to an excessively small value is that the convergence process becomes extremely slow, requiring massive numbers of iterations to reach the minimum loss. When the learning rate is configured to be very small, the adjustment made to the model's weights in each iteration is minimal. While providing high precision and ensuring that the optimizer is unlikely to overshoot the minimum or diverge, the primary trade-off is computational speed. The optimizer must take millions of tiny steps to make significant progress down the loss surface. Consequently, training requires many more iterations (epochs), leading to high wall-clock training times, increased server costs, and slower development cycles. In practice, if too small, the updates can become smaller than the machine's floating-point precision, causing the model to stall and stop improving altogether. The claim that the optimization path is virtually guaranteed to bypass the global minimum and settle into shallow local minima is incorrect. This small learning rate can increase the likelihood of getting stuck in local minima, since it lacks momentum to jump out of shallow valleys, but it does not guarantee doing so, and this is not the main operational disadvantage. The claim that the model is mathematically blocked from reducing its loss value below its initial random starting point is incorrect because the small learning rate will eventually minimize training error given sufficient time and iterations. The claim that the model will inevitably overfit the training dataset and suffer severe loss in generalization capability is incorrect because overfitting is the function of model capacity, training duration, and lack of regularization, not the learning rate value itself. For the exam, remember the core trade-off: high learning rate causes instability and divergence, while low learning rate leads to extremely slow training convergence.