
When training a deep neural network, you must configure a key hyperparameter called "batch size" before initiating the training loop. What is the specific purpose of this setting?
Select an answer to reveal the explanation.
Short Explanation
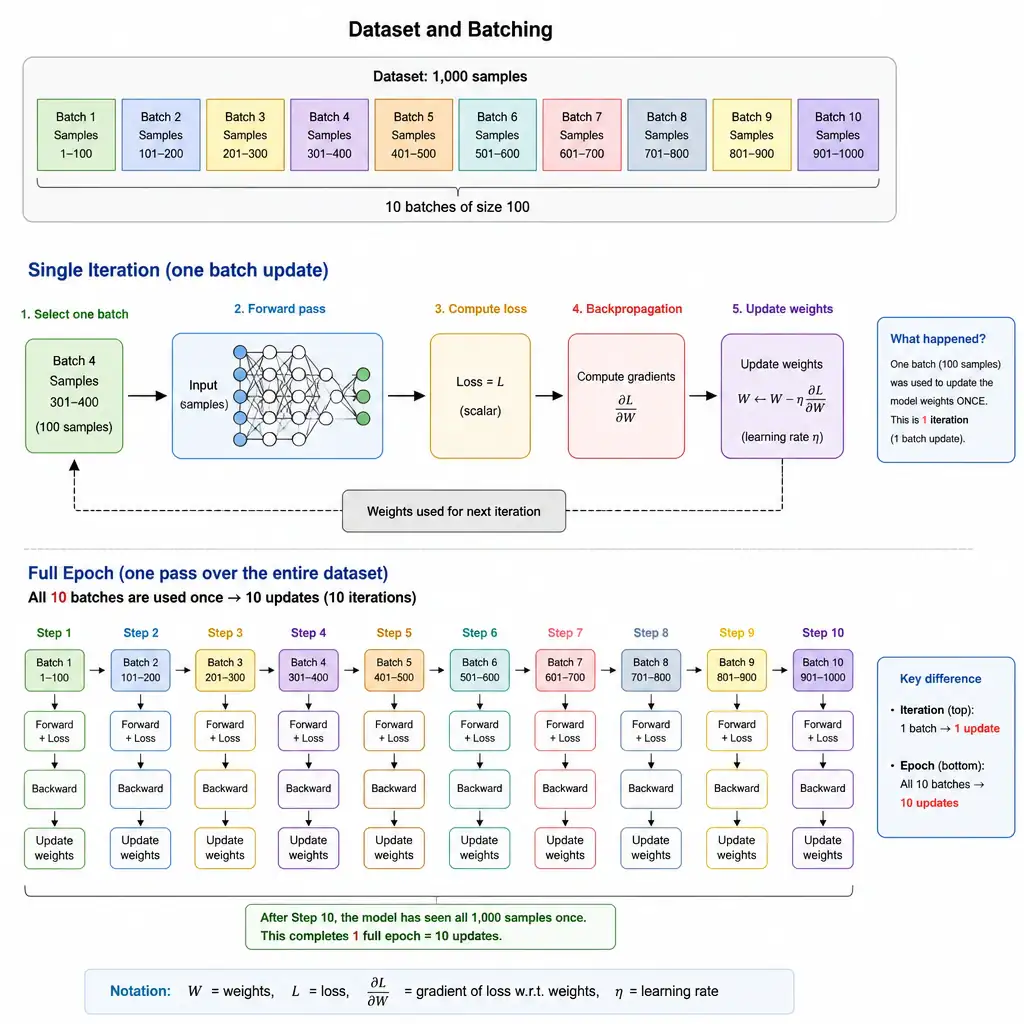
Think of batch size as the number of training examples you feed through the network before it updates its weights. Too big and your hardware memory chokes; too small and training gets noisy and slow. That's why the setting that defines samples processed together in one forward and backward pass is the right one.
Full Explanation
In the training of deep neural networks, optimization algorithms such as Mini-batch Gradient Descent calculate the gradient of the loss function to update the model's internal weights. The batch size is a critical hyperparameter that determines how many training examples are processed together during a single forward and backward pass before the model's weights are updated.
When batch size is set to the entire dataset (Batch Gradient Descent), the calculated gradients are a highly stable and accurate representation of the entire dataset, but the calculation requires immense memory and processing power, often resulting in out-of-memory errors on modern accelerators. Conversely, setting the batch size to 1 (Stochastic Gradient Descent) updates the weights after every single sample. While this is memory-efficient, the updates are highly noisy and unstable, which can prevent the model from smoothly converging. Modern deep learning practitioners therefore choose a mini-batch size (typically between 32 and 512) to strike an optimal balance: utilizing the parallel processing capabilities of GPUs while maintaining stable and efficient gradient updates.
Let's look at the other options to understand why they are incorrect: - The option about establishing the total count of hidden layers refers to the depth of the network, which is determined by the number of hidden layers, not the batch size. - The option about determining the total number of complete passes through the entire dataset describes the concept of an epoch, which is one complete pass through the entire training dataset. One epoch is made up of multiple iterations (steps) determined by the batch size. - The option about specifying the number of individual neurons in the final output layer refers to the output layer size, which is dictated by the number of target classes or values in your specific classification or regression task.
For the exam, make sure you associate 'batch size' with the number of training examples processed in a single weight-update iteration.