
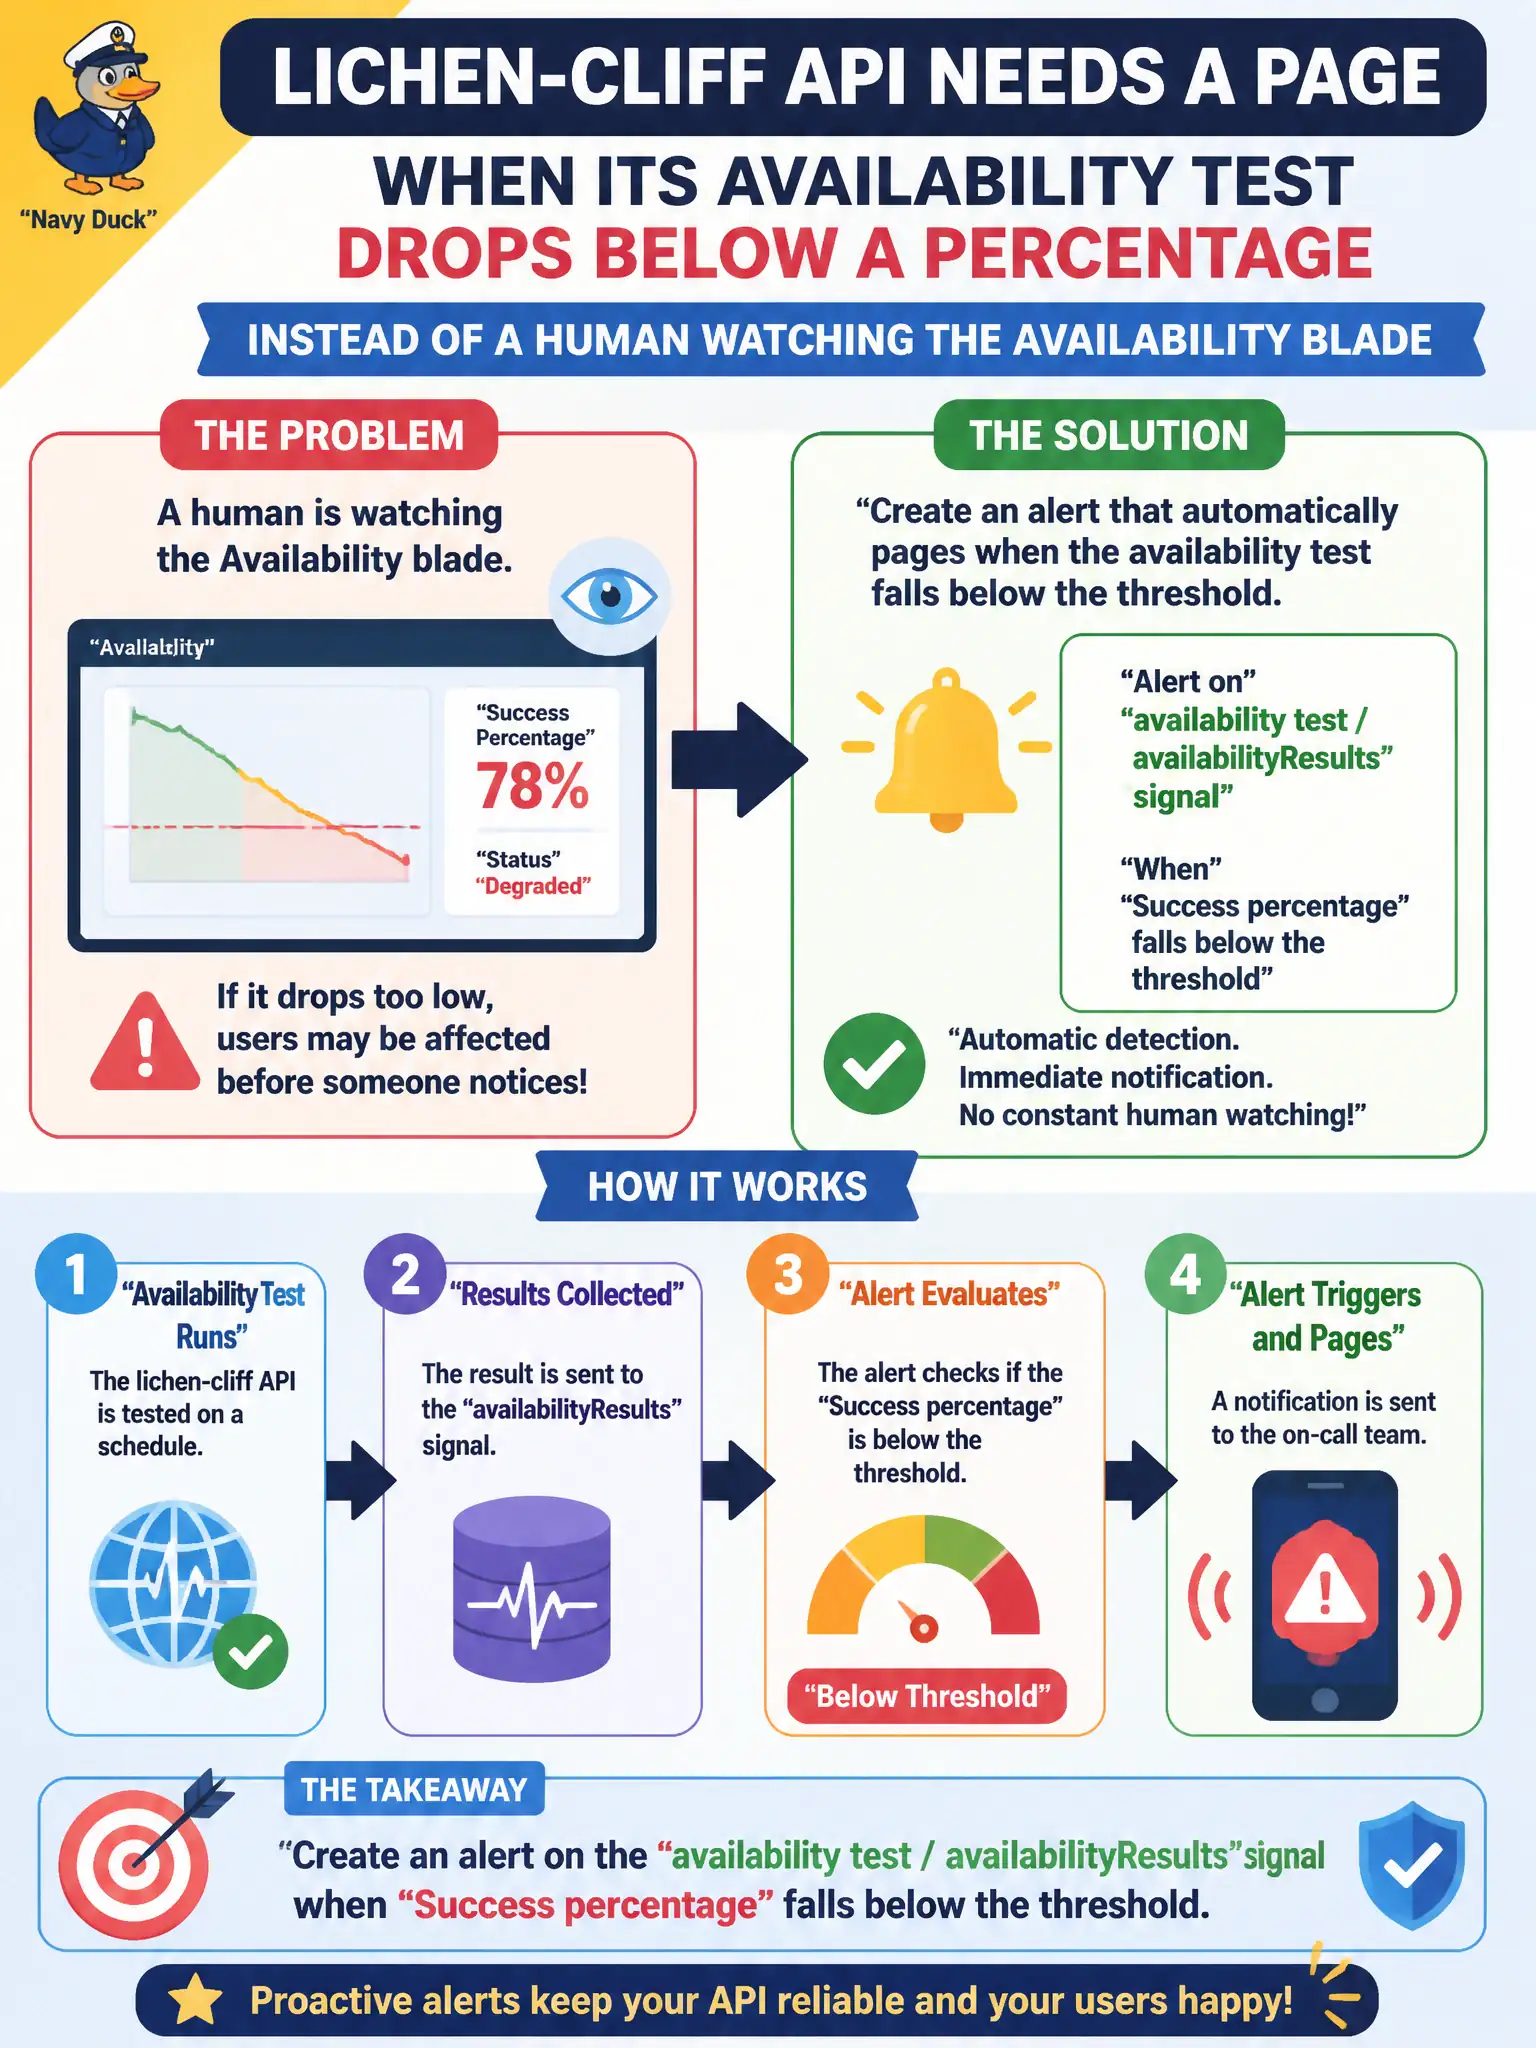
A lichen-cliff API needs a page when its availability test drops below a percentage instead of a human watching the Availability blade. What should the developer create?
Select an answer to reveal the explanation.
Short Explanation
Wire an alert to the availability test (availabilityResults). Watching the blade forever is not a strategy; VM CPU and CDN purge mail are different tools.
Full Explanation
Watching the Availability blade is not an on-call strategy. For the lichen-cliff API, create an alert on the availability test / availabilityResults signal that fires when success percentage falls below the threshold. That wires automated paging to the same outside-in results Application Insights already stores.
Only a platform VM CPU alert with no link to the availability test fails because guest CPU does not measure HTTP availability percentage from Insights tests. CPU can be healthy while the public endpoint fails TLS or DNS.
A CDN purge schedule that emails whenever edge nodes refresh fails because purge notifications are operational edge events, not availability success-percentage alerts on availabilityResults.
An App Service autoscale rule labeled as an availability percentage alert fails because autoscale rules scale instances from load metrics; renaming them does not create an Insights availabilityResults alert.
Exam caveat: align alert severity and evaluation window with test frequency so one missed run does not thrash, and include action groups that reach the right channel. Operational check: force a failing test (wrong path or blocked URL in a staging slot), confirm availabilityResults drop, and verify the alert fires and notifies the action group.