
A pebble-beach rental tool wants to page Cosmos changes on demand instead of hosting a continuous processor loop. Which official approach should the developer use?
Select an answer to reveal the explanation.
Short Explanation
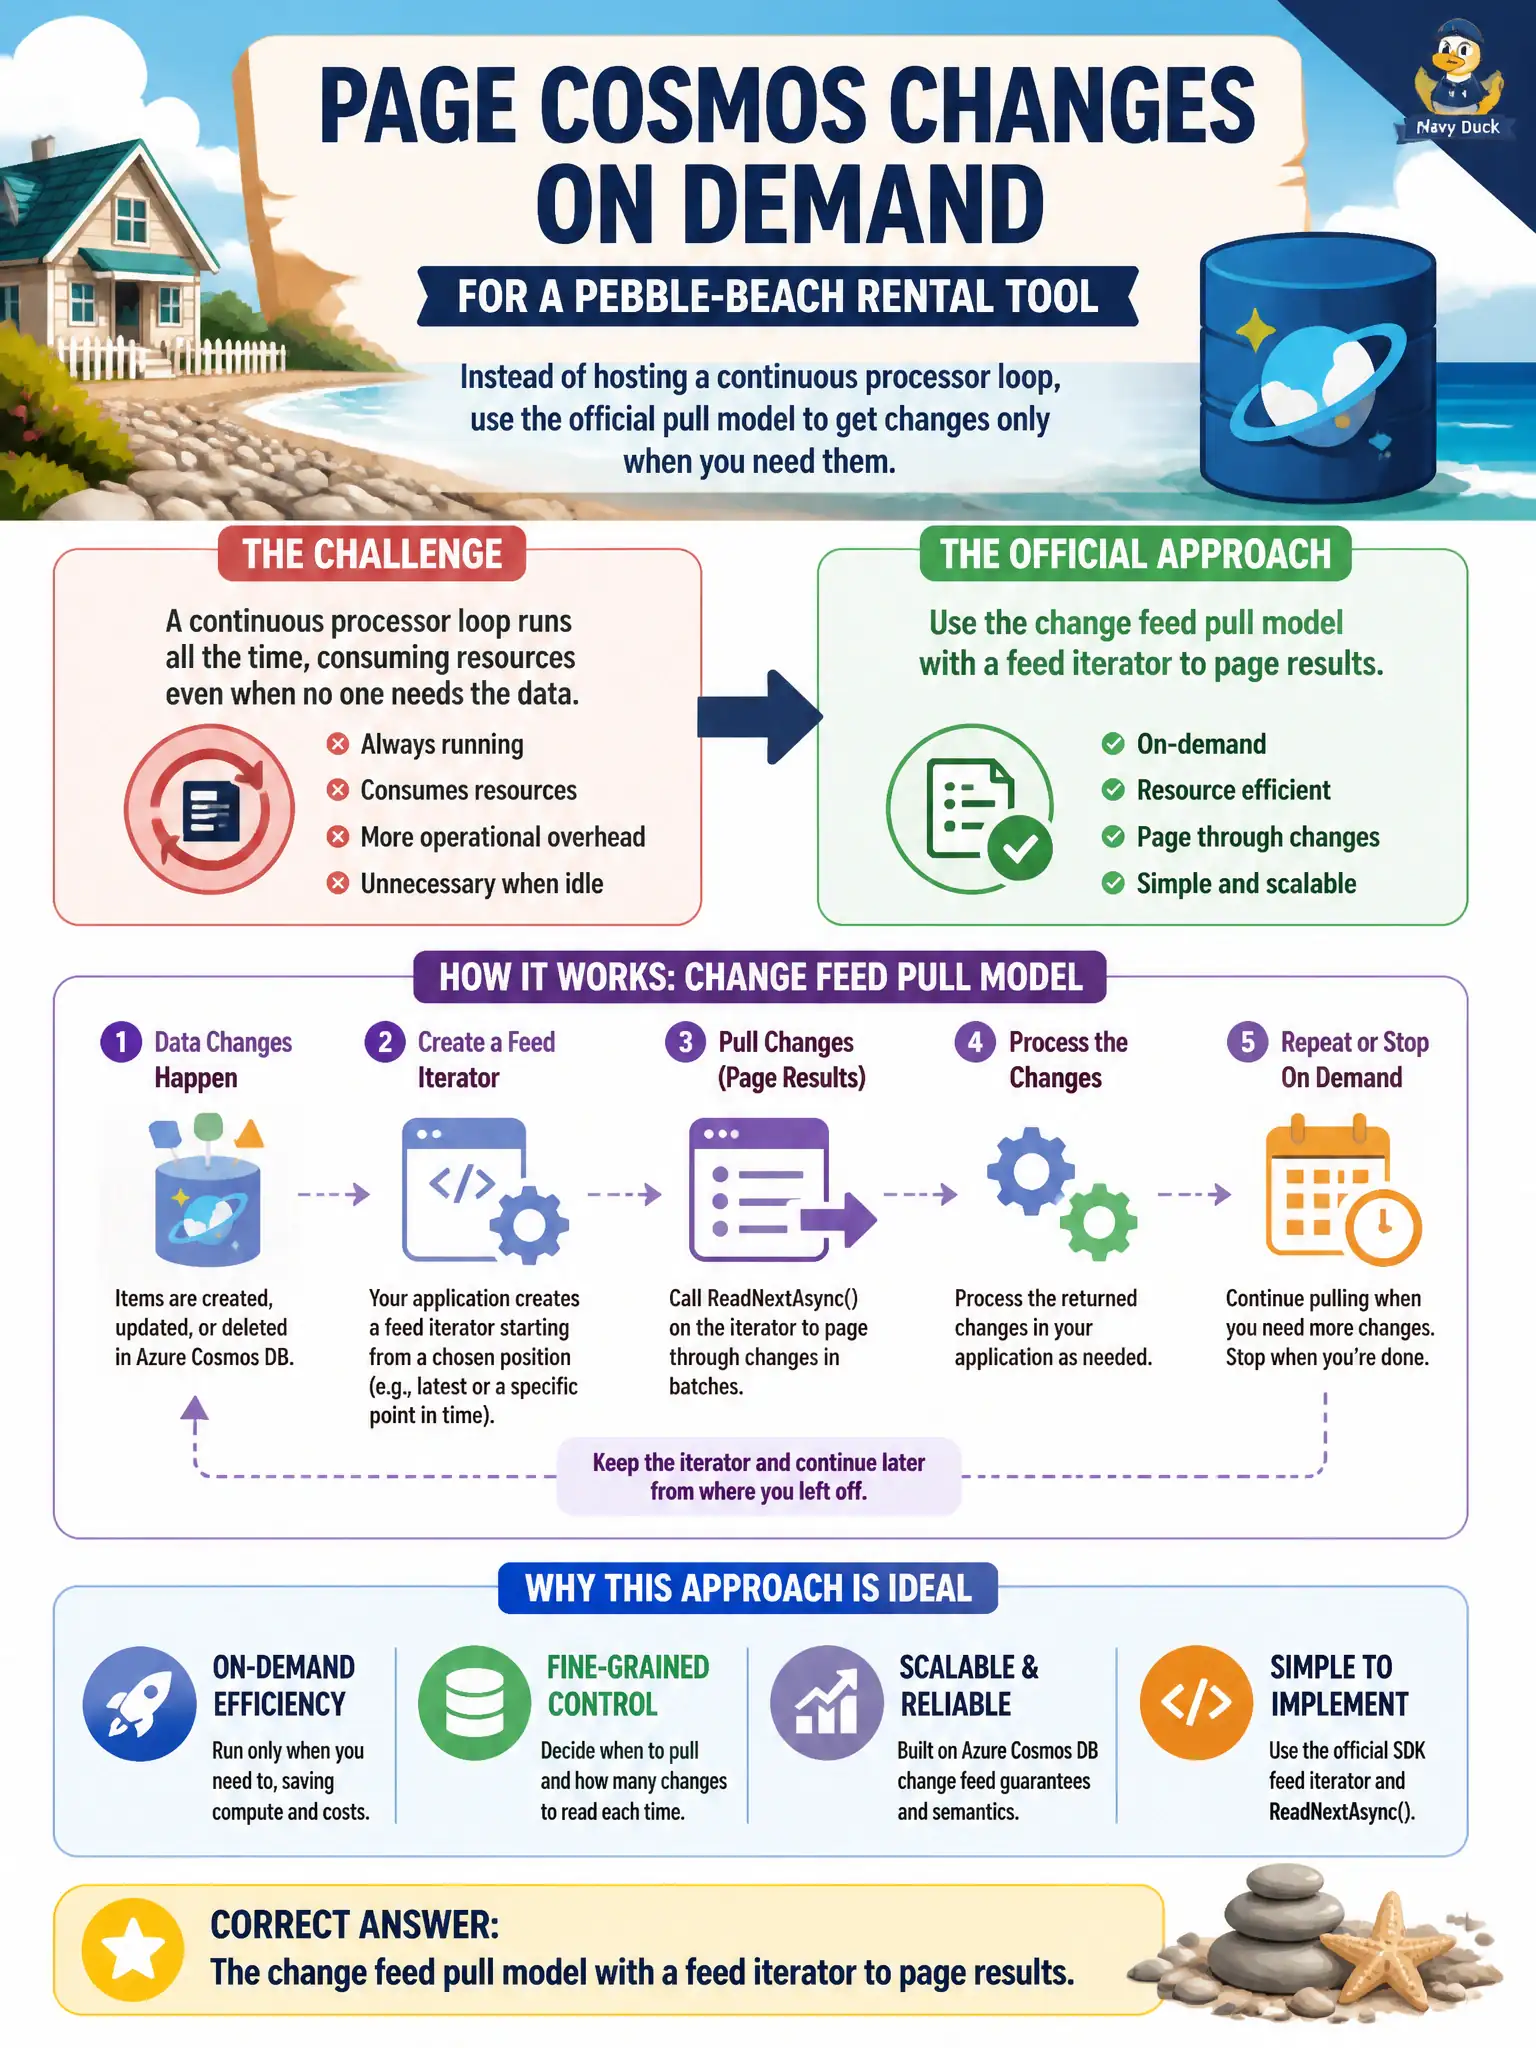
Sometimes you want to flip pages yourself instead of running a always-on reader. That is the change feed pull model with a feed iterator. Spark can show up in docs, but it is not the AZ-204 answer here.
Full Explanation
A pebble-beach rental tool that wants to page Cosmos changes on demand instead of hosting a continuous processor loop should use the change feed pull model with a feed iterator. The pull model lets the application request the next page of changes when a user clicks Next or when a job is ready, without running the processor’s always-on loop and lease machinery for continuous consumption.
Claiming only Apache Spark change-feed connectors work because the SDK has no pull option is false; Spark appears in broader documentation, but AZ-204 centers on the SDK pull/processor paths. A Logic App that lists the container on each Next click is polling current items, not reading the change feed’s incremental pages. Durable Functions orchestration is not the required change-feed host for this Domain 2 item and adds workflow complexity the stem does not ask for.
Exam caveat: pull model still requires you to persist continuation tokens if you want to resume later; without storing the iterator state, on-demand paging can restart or skip unexpectedly.
Operational check: create a feed iterator for the rental container, page twice while inserting items between calls, persist the continuation, restart the app, and confirm the next page resumes from the saved token rather than from the beginning.