
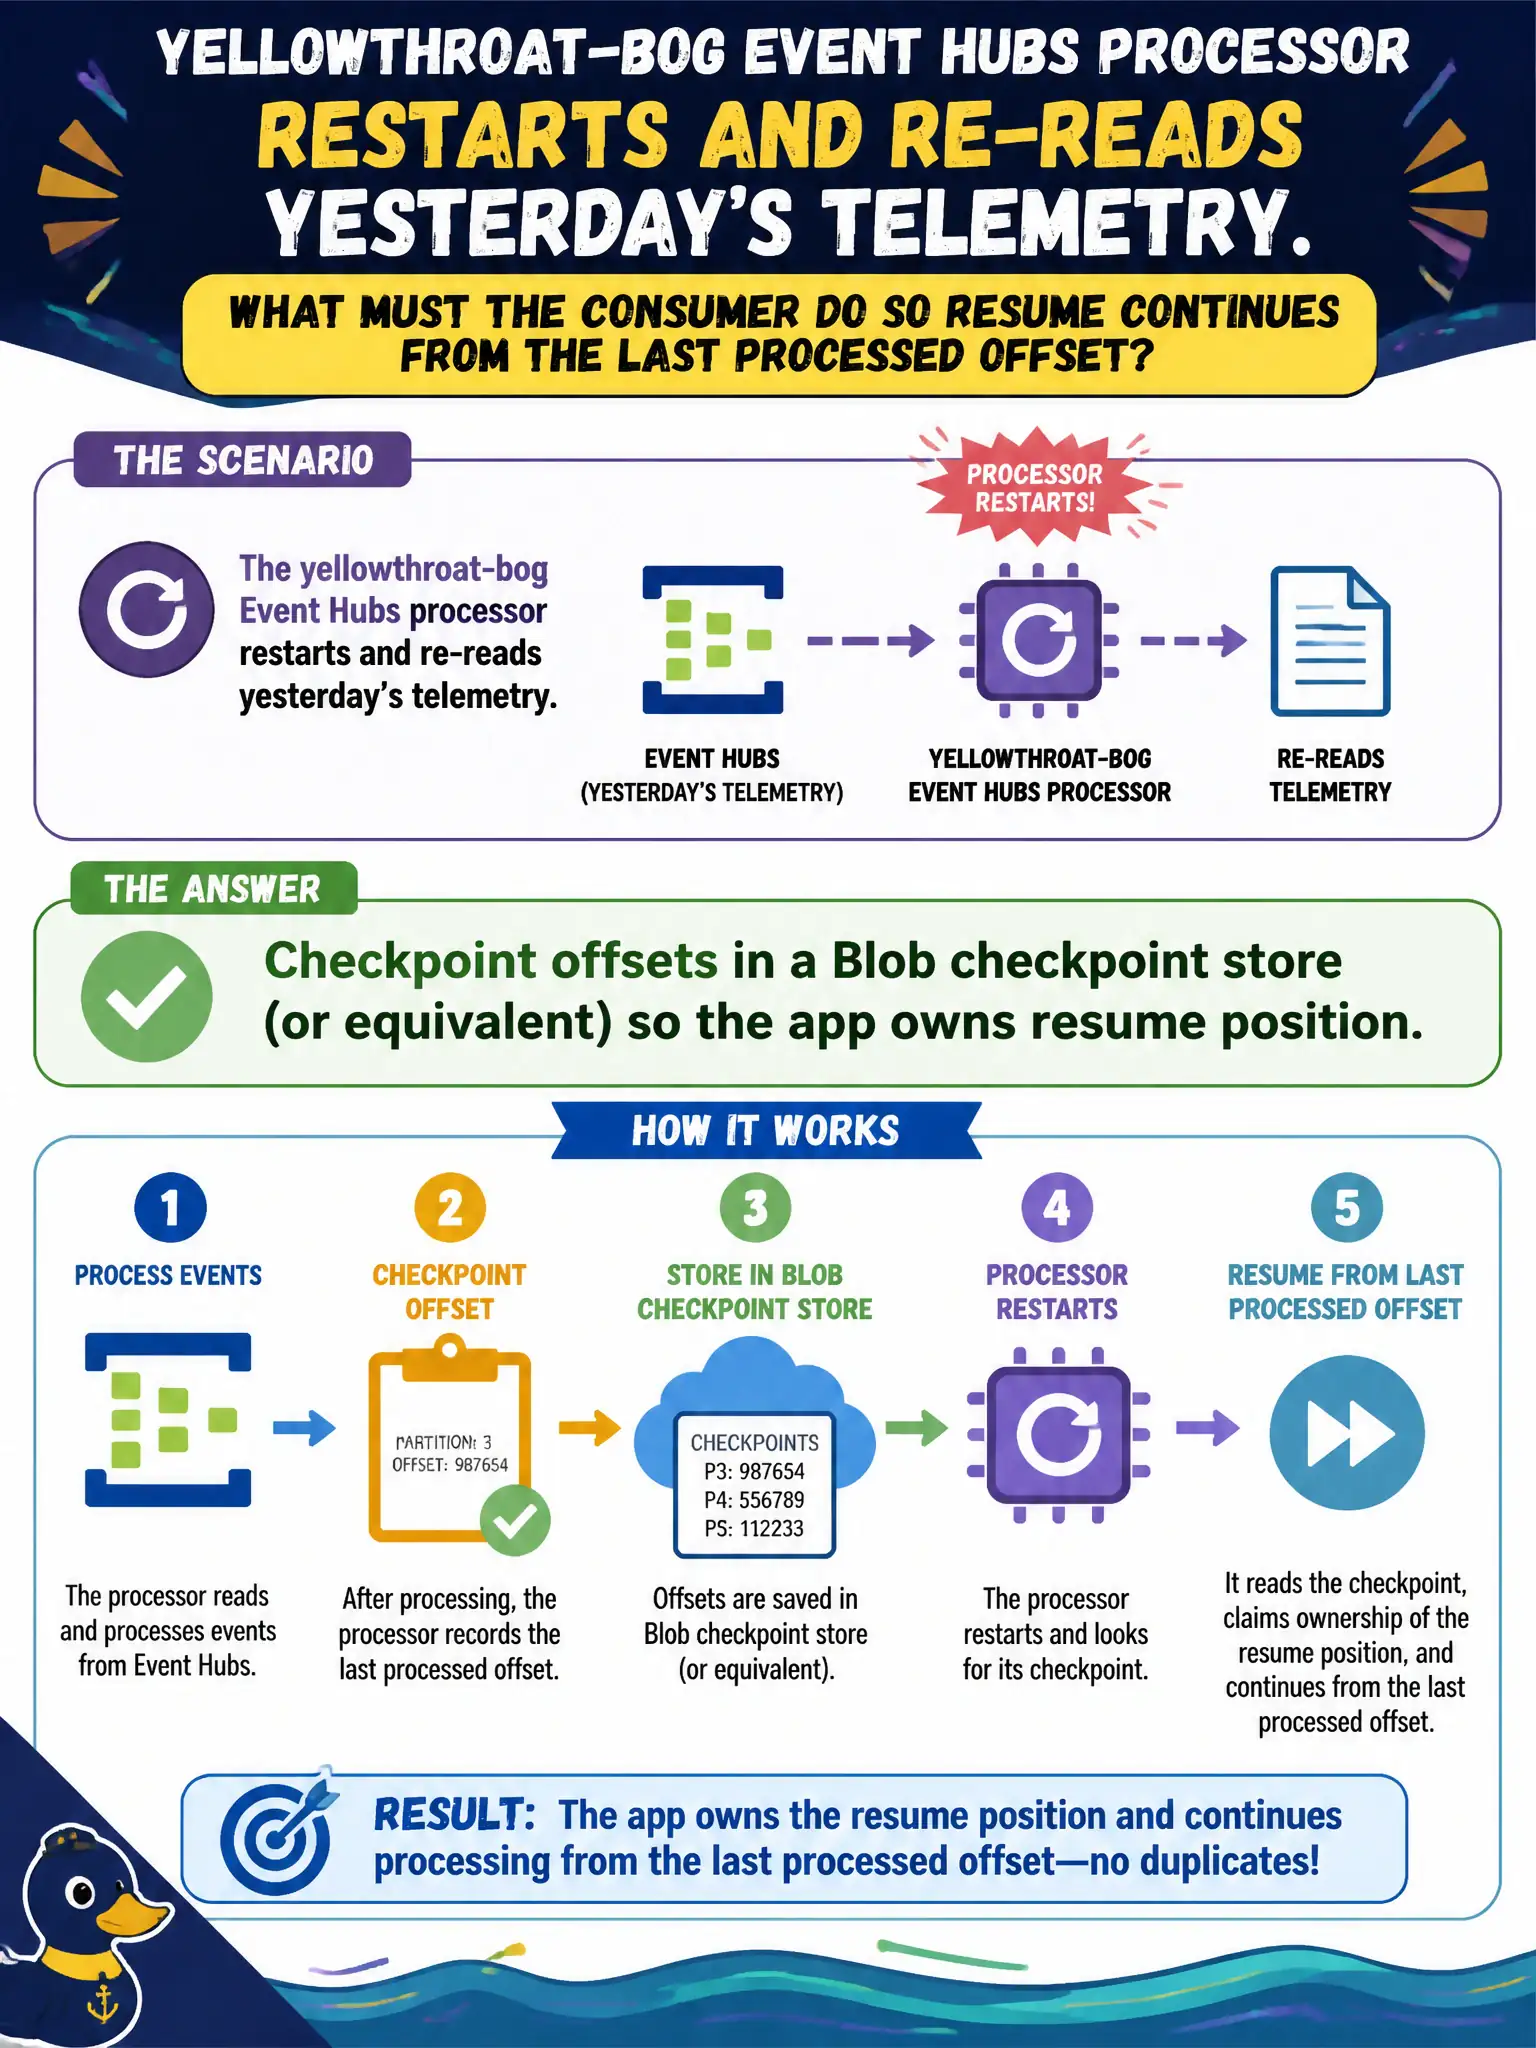
A yellowthroat-bog Event Hubs processor restarts and re-reads yesterday's telemetry. What must the consumer do so resume continues from the last processed offset?
Select an answer to reveal the explanation.
Short Explanation
Event Hubs is a log — it does not babysit your cursor. Checkpoint the offset (Blob checkpoint store with the processor client is the usual path) so a restart picks up where you left off, not yesterday.
Full Explanation
Event Hubs stores an append-only partitioned log; it does not remember which offsets a particular yellowthroat-bog processor has already handled. The correct approach is for the consumer to checkpoint its own progress—commonly with EventProcessorClient (or equivalent) writing offsets into a Blob checkpoint store—so a restart continues from the last committed position instead of replaying yesterday's telemetry. That ownership model is what makes multi-instance, restart-safe processing possible across partitions.
Expecting Event Hubs to push the last offset automatically to every webhook fails because Event Hubs is a pull/read log, not an Event Grid-style push dispatcher that tracks subscriber cursors for you. Deleting partitions so the hub "resets" fails conceptually: partition surgery is destructive and operationally risky, and it still does not create durable per-consumer progress tracking. Switching the hub to Logic Apps so offsets become optional fails because changing orchestration tooling does not remove the need for a consumer-owned resume cursor when you process a high-throughput stream.
Exam caveat: checkpointing after every single event can throttle throughput; checkpoint too rarely and a crash replays a large window—balance frequency against idempotent handlers. Operational check: after a controlled process restart, confirm the Blob checkpoint container updates and that the processor resumes near the expected offset rather than from the beginning of retention.