
A large distributed cache must keep serving if one rack fails. The nodes can be divided across partitions, and someone suggested a cluster placement group to pack them close. Which placement group fits the failure goal?
Select an answer to reveal the explanation.
Short Explanation
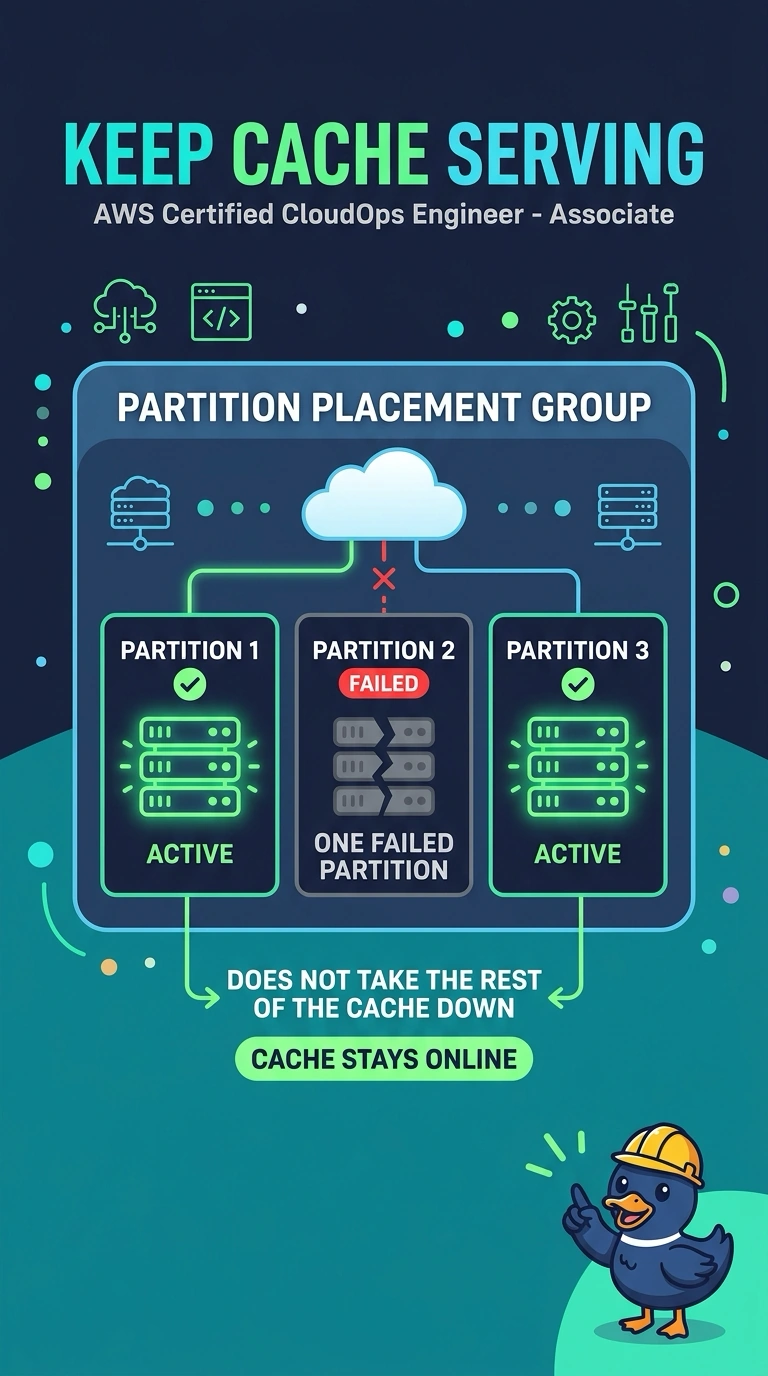
Packing every cache node into one aisle means one bad rack clears the aisle. A partition placement group spreads a large fleet across partitions so a failure in one partition leaves the others up, which is what you want for this cache. A cluster group packs instances close for latency, and a spread group is for a small set of critical instances rather than a cache this large.
Full Explanation
A partition placement group spreads instances across logical partitions. Instances in different partitions do not share the same racks, so a failure that takes one partition leaves the other partitions running. A large cache that must survive a rack failure, and that can be divided across partitions, is the case this group is for. A cluster placement group packs instances close together in a single Availability Zone for low latency. A rack or host failure in that packed group is exactly what the cache is trying not to treat as fatal, so the suggestion to cluster them works against the goal. A spread placement group puts each instance on distinct hardware, but it only holds a small number of instances in each Availability Zone. It is the wrong shape for a large cache, and it does not divide the fleet into partitions. No placement group does not create those failure domains. Nothing in ordinary placement promises that a rack failure leaves most of the cache up. Caveat: replicas of the same cache data should be placed in different partitions, or a partition failure can still remove every copy of one key. Operational check: confirm the nodes show the partition group and that a test node's partition is not the partition used by its replicas.