
A retail platform runs 200 EC2 instances behind an ALB and needs early warning of impaired hosts, failed health checks, and reboot events with actionable alerts. Which workload monitoring strategy provides comprehensive resource health checks with automated alerting?
Select an answer to reveal the explanation.
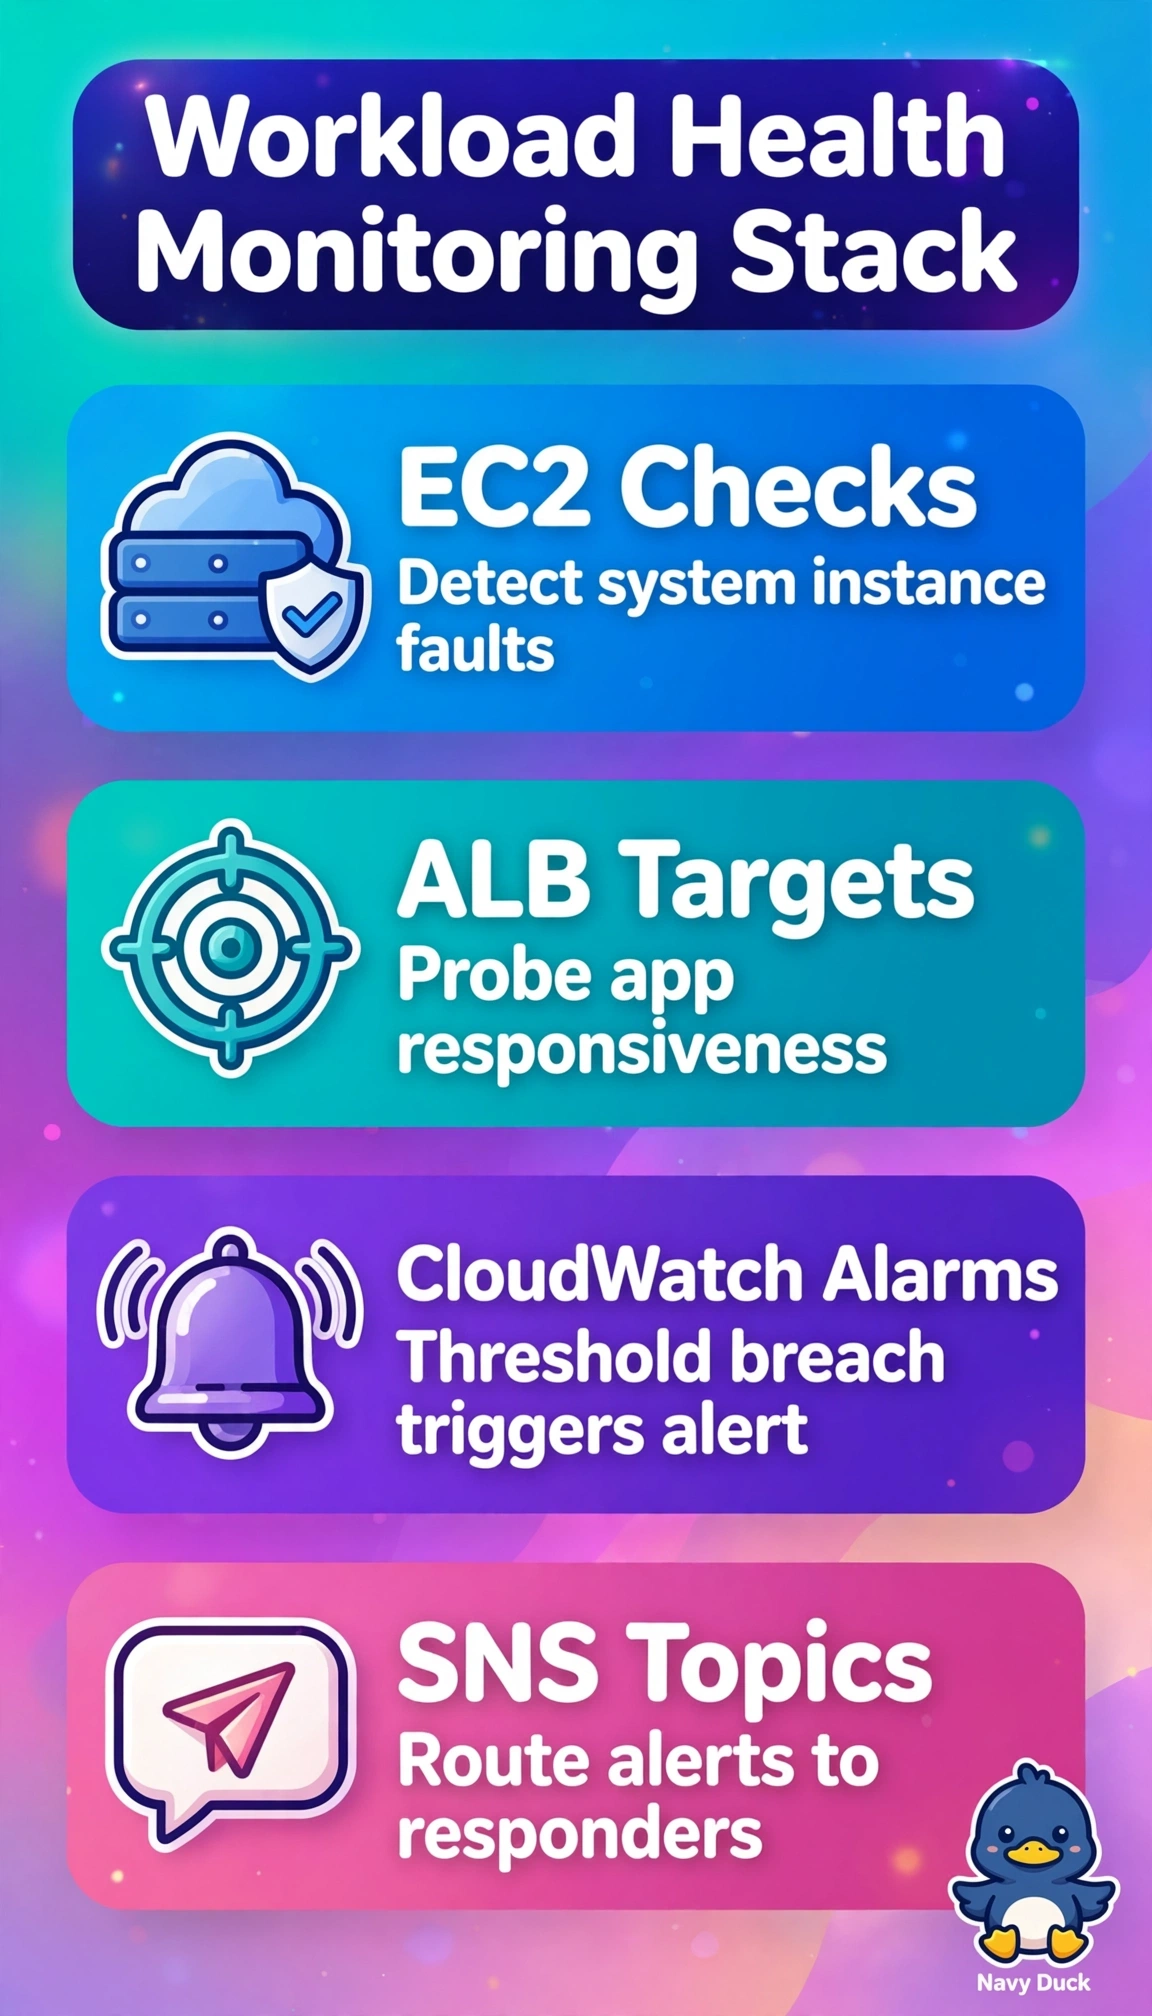
Short Explanation
Your fleet needs a nurse checking vitals around the clock, not an annual physical. Health checks from EC2, ALB, and CloudWatch alarms give you that live pulse.
Full Explanation
The correct strategy succeeds because detailed monitoring provides high-resolution metrics for early warning, ALB target health exposes failed health checks and routing issues across the fleet, EC2 system and instance status checks detect impaired hosts and reboot events, and alarms routed to SNS turn those signals into actionable alerts at scale. The dashboard-centered design with detailed monitoring, ALB health and EC2 checks is a legitimate visualization practice for trends and investigations but fails on automated alerting because it relies on manual review rather than pushing notifications when thresholds breach. The EC2 recovery-centered design with detailed monitoring, status checks and SNS notifications is a standard resilience practice for host failures but fails on load balancer awareness because it cannot see targets marked unhealthy by ALB health checks when the instance itself still passes status checks. The ALB notification-centered design with detailed monitoring, target metrics and SNS notifications is a standard routing-health practice for load-balanced fleets but fails on host depth because without EC2 status checks it cannot confirm hardware impairment, software failure or reboot causes. For exams, remember comprehensive health requires both target-level and instance-level visibility plus alarm-to-notification wiring, and sound-looking answers often contain two of the three to test completeness. As a practical check, confirm alarms exist for UnHealthyHostCount, StatusCheckFailed_System and StatusCheckFailed_Instance with tested SNS subscriptions and run a controlled reboot to verify end-to-end delivery.