
A support platform generates 2M Bedrock summarizations daily with many duplicate tickets, spiky daytime traffic, and repeated system prompts. Inference dominates the AWS bill and p95 latency rises during peaks. Which AI workload optimization combining tier selection, batching, and caching best cuts cost while meeting latency?
Select an answer to reveal the explanation.
Short Explanation
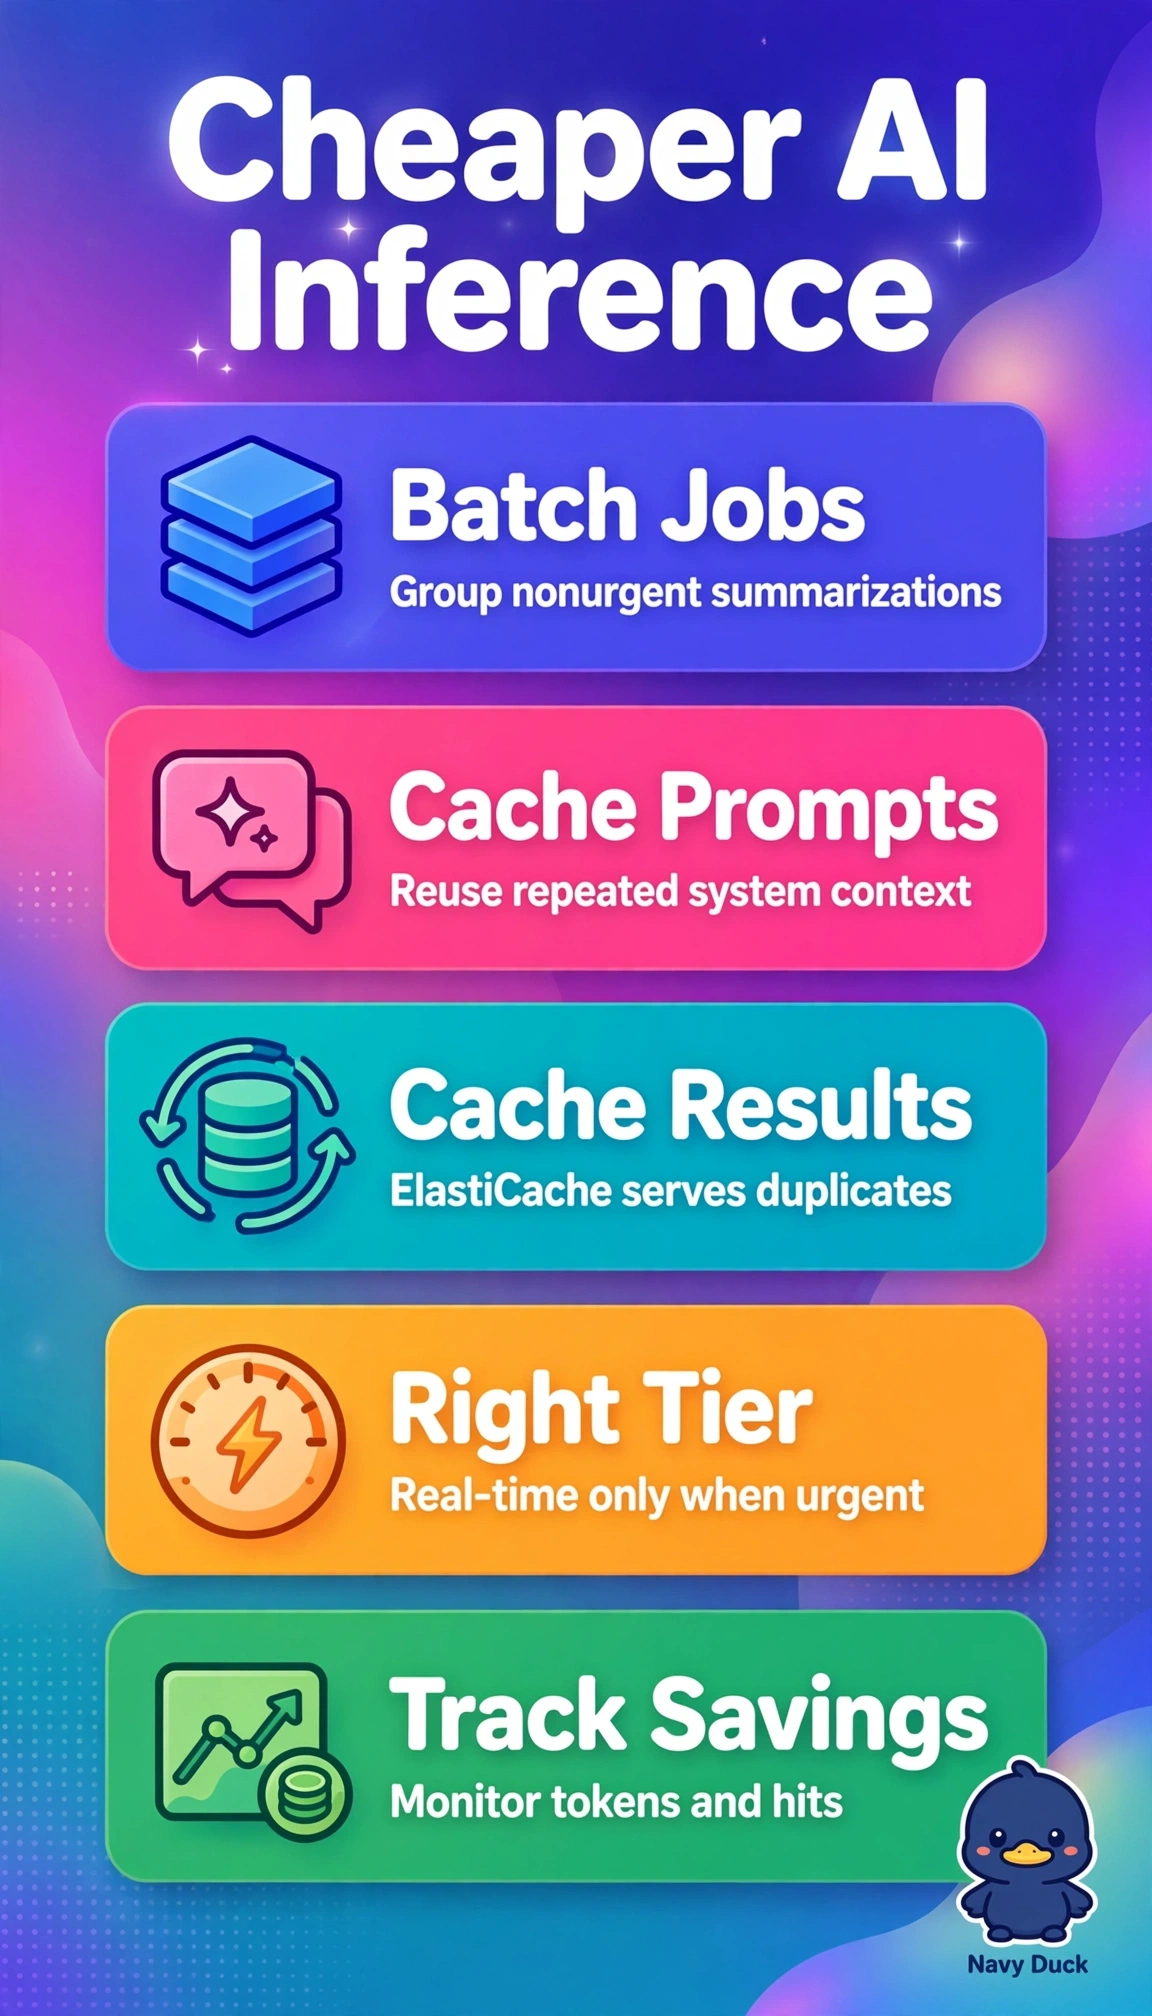
You’re rewriting the same answer two million times at full price. Prompt caching plus batching and result reuse slashes tokens and smooths those spikes.
Full Explanation
The correct combination aligns each optimization to a distinct cost driver while preserving peak latency: batch inference moves delay-tolerant summarizations off expensive real-time capacity to lower-cost bulk processing that absorbs daytime spikes, prompt caching avoids reprocessing identical repeated system prompts across 2M calls, and ElastiCache provides millisecond reuse for duplicate tickets to cut both inference spend and p95 tail latency. The off-peak batch plus ElastiCache approach without prompt-level reuse is operationally sound for duplicate-heavy workloads but fails the repeated-prompt fact because system instructions would still be billed and recomputed on every unique ticket. The real-time On-Demand approach with both caching layers is standard for latency-sensitive serving but misses the batching requirement, so spiky daytime traffic stays on the highest-price tier and p95 remains exposed despite cache hits. The all-batch approach with prompt reuse is efficient for throughput-oriented pipelines but violates the latency requirement by queueing urgent daytime tickets that need immediate response, trading p95 compliance for bulk savings. As an exam caveat, distinguish delay tolerance from overall volume: high volume alone does not justify batching everything if peaks include interactive requests with strict SLOs. As a practical check, segment tickets by urgency and duplication rate in CloudWatch, then validate cache hit ratio in ElastiCache and cached prompt token ratio in Bedrock metrics before committing to Provisioned Throughput.