
A support team launched an Amazon Bedrock RAG chatbot that cites policies, but answers drift and compliance worries grow. Product owners require repeatable quality scores, detection of harmful or hallucinated replies, and regression comparison across prompts. Which validation approach evaluates AI outputs rigorously?
Select an answer to reveal the explanation.
Short Explanation
You're grading essays with a rubric, not just glancing at handwriting. Bedrock Evaluations scores accuracy and safety on repeatable tests, so regressions pop like red ink.
Full Explanation
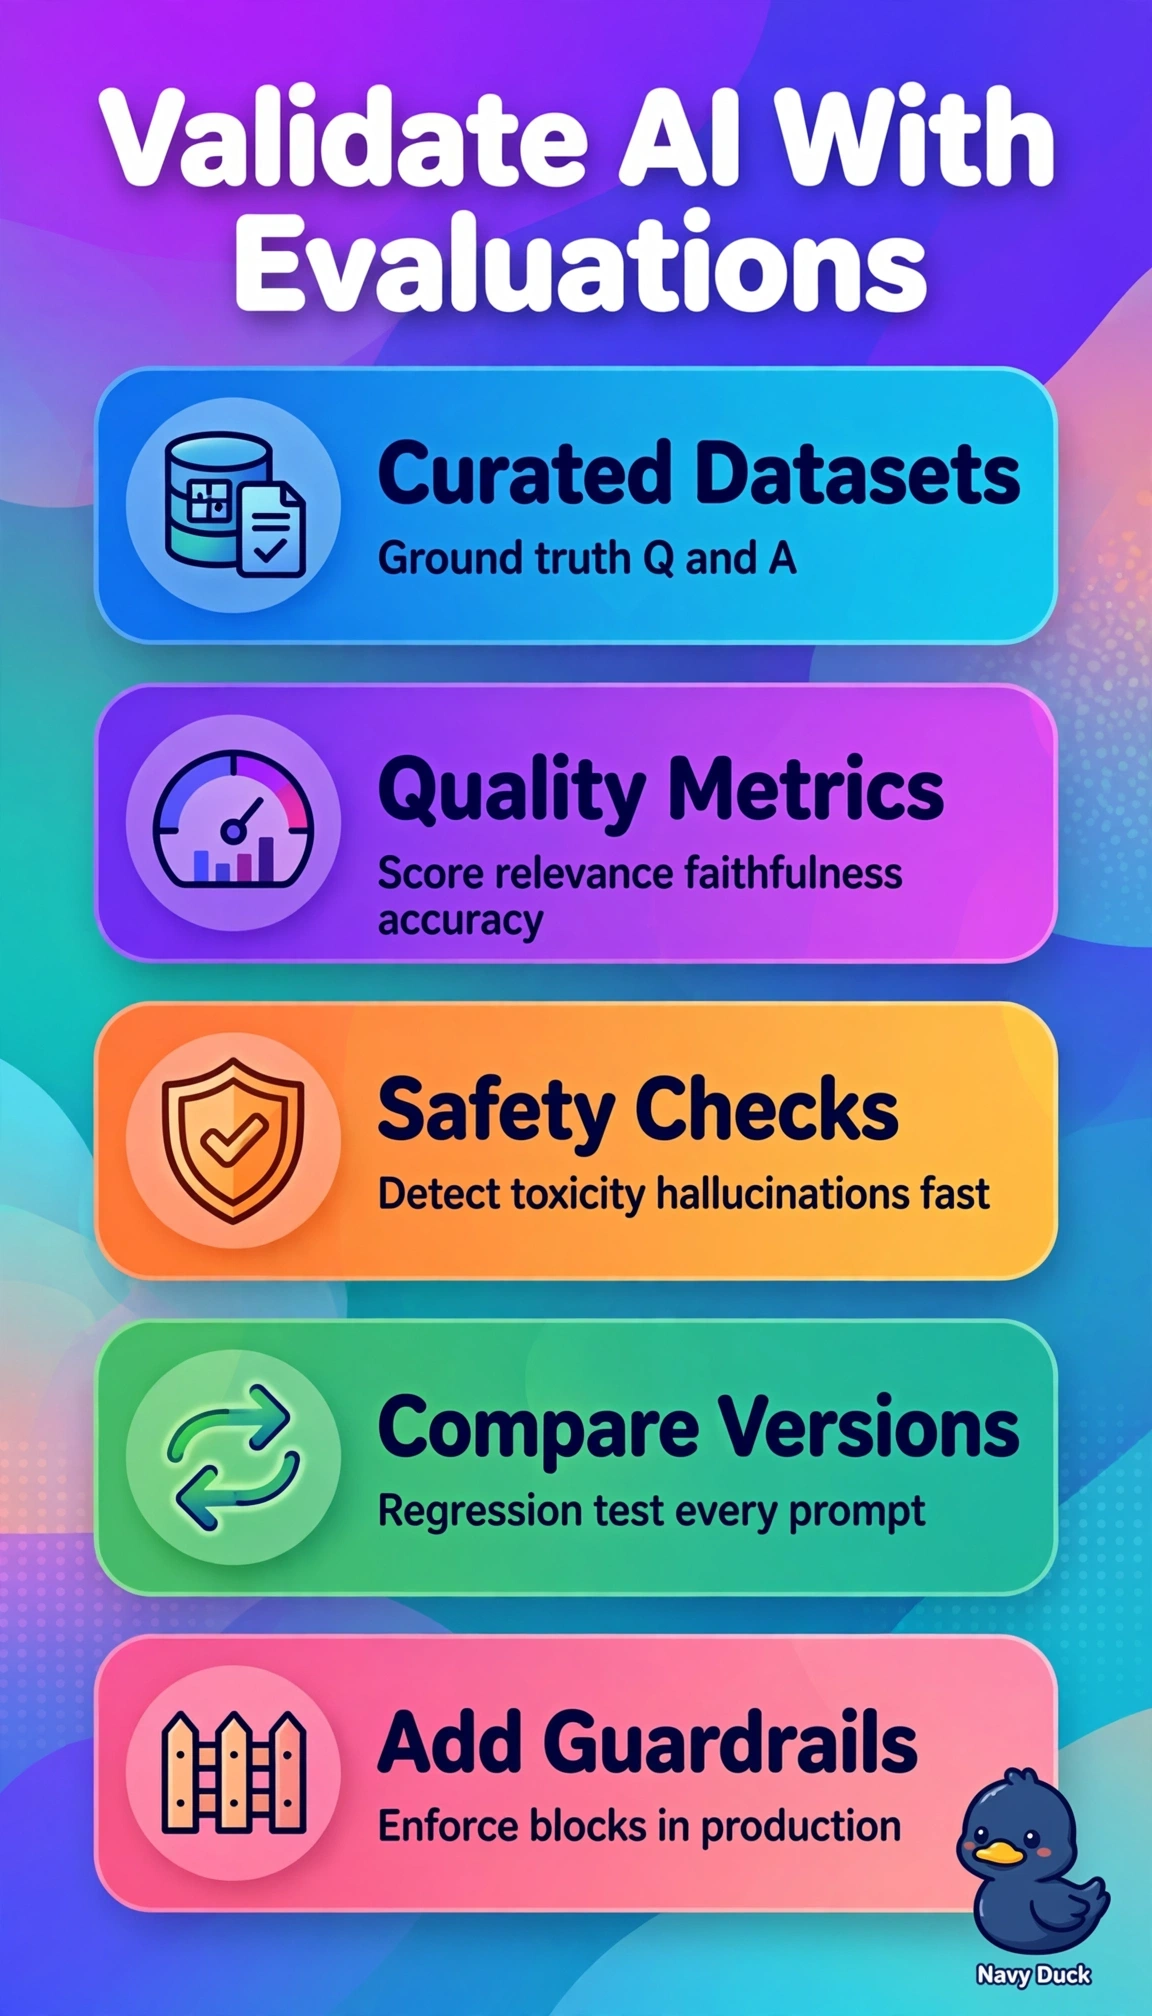
The rigorous approach requires Amazon Bedrock Evaluations because it combines curated golden datasets for the policy RAG use case with repeatable automatic metrics such as exact match for citations, semantic similarity and faithfulness for drift and hallucination, plus LLM-as-judge and guardrail-related checks for toxicity and safety, and it supports side-by-side regression comparison across prompt and model versions. The human evaluation with semantic scoring correctly provides repeatable quality measurement and prompt-version comparison but fails as a complete validation concept because without configured harmfulness, toxicity, and guardrail policy checks it does not systematically detect unsafe or noncompliant replies. The guardrails enforcement choice correctly implements production safety controls and violation monitoring but fails as an evaluation concept because blocking and logging do not produce scored quality, faithfulness, or similarity results nor controlled dataset-based regression. The one-time exact-metric and toxicity test correctly validates initial accuracy and safety but fails as a lifecycle concept because a single prelaunch run cannot track drift or compare regressions as prompts evolve. For the exam, do not confuse operational guarding or CloudWatch operational monitoring with model evaluation, since only evaluations produce scored quality and safety results on datasets. As a practical check, maintain versioned prompt plus dataset pairs in Bedrock Evaluations and require passing thresholds on faithfulness, correctness, and safety before promotion.