
A travel company launches a Bedrock chatbot that drafts itineraries and must block self-harm advice, mask passport numbers, and refuse restricted travel-document forgery topics with auditable interventions. Which generative AI compliance control design best enforces this content filtering requirement?
Select an answer to reveal the explanation.
Short Explanation
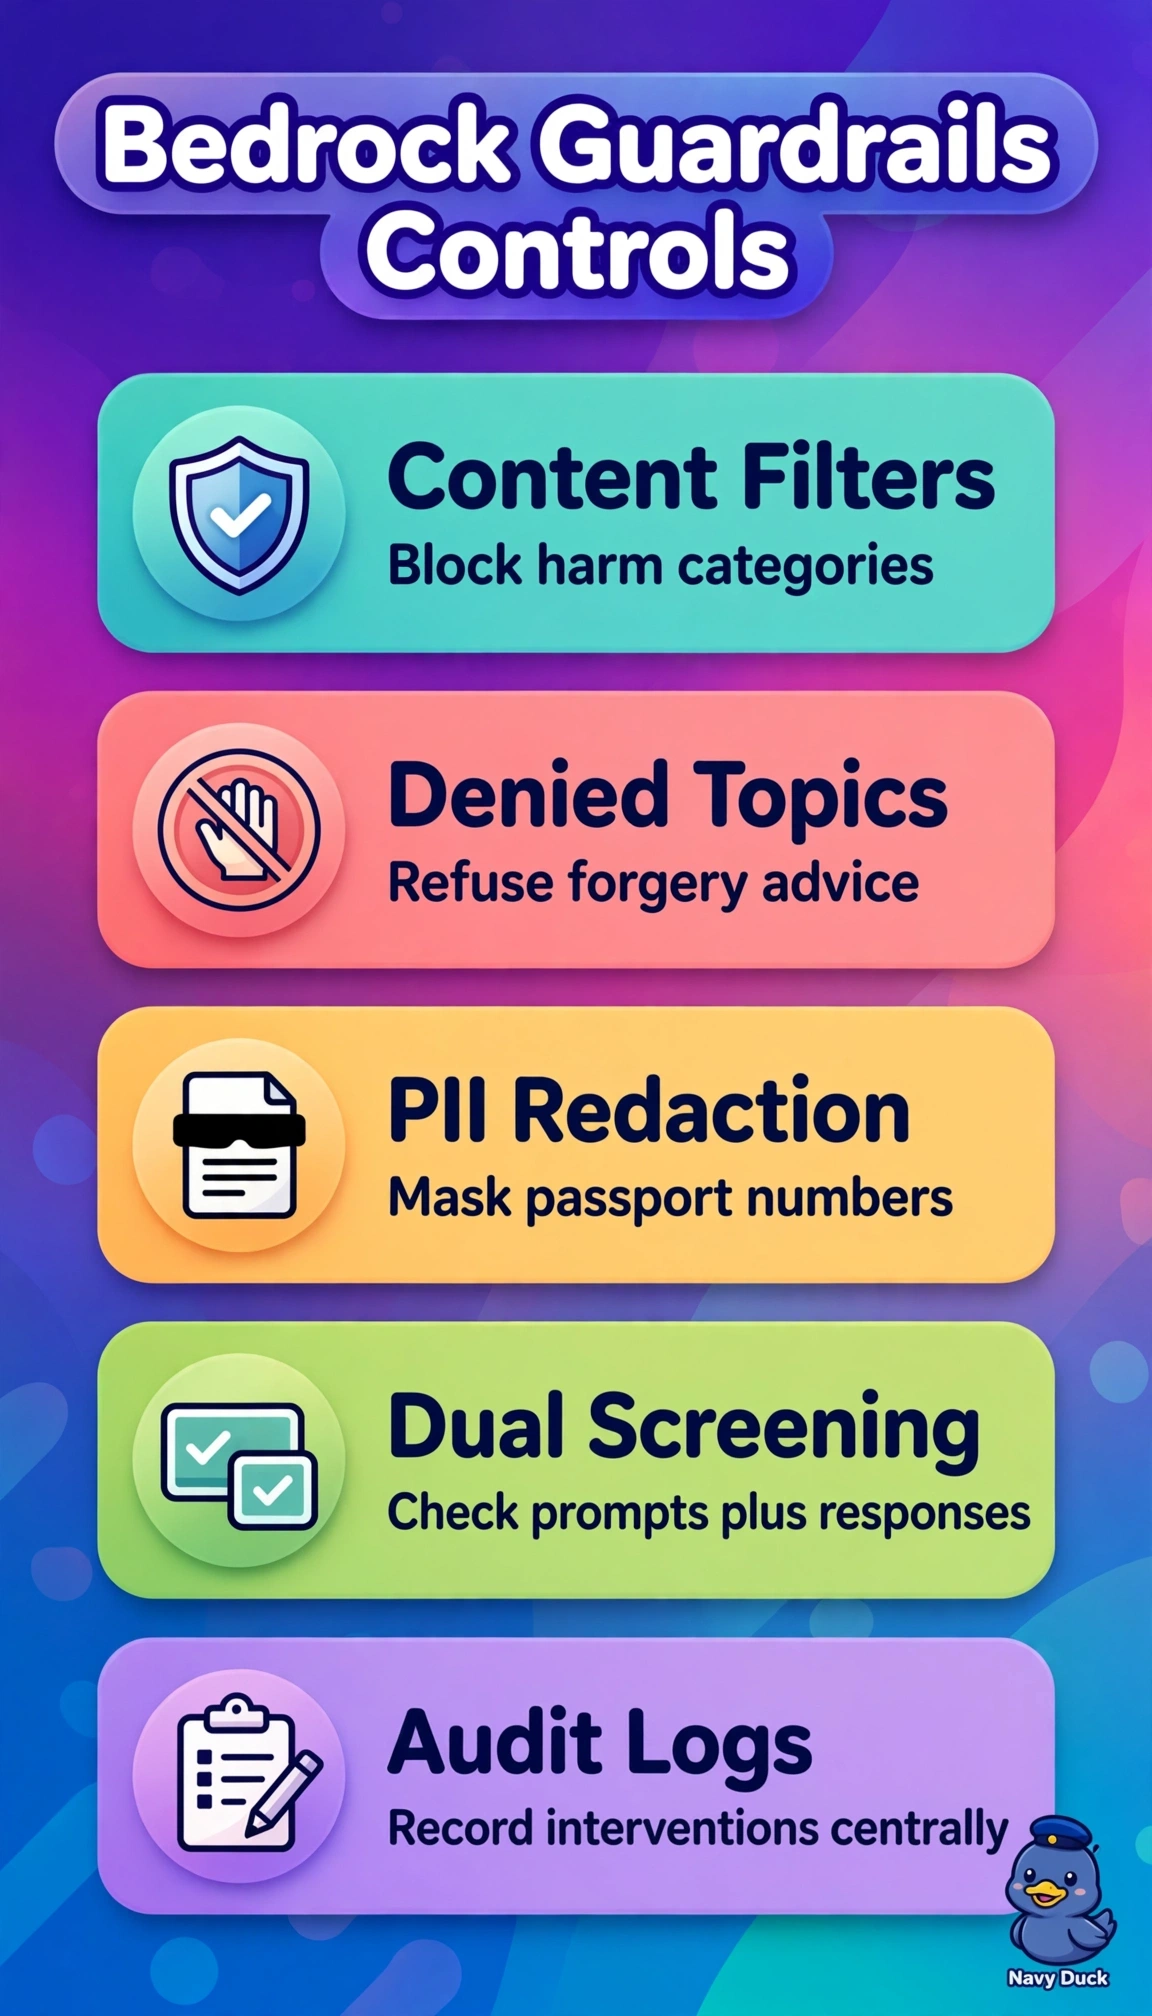
You need a bouncer checking words going in and out. Guardrails filter harm, block banned topics, and mask PII before users ever see it.
Full Explanation
The correct design is right because Bedrock Guardrails enforces inline controls at inference time by combining high-severity content filters to block self-harm advice, denied topics with tailored refusal messages to refuse travel-document forgery requests, PII redaction to mask passport numbers, bidirectional application to both user prompts and model responses to prevent prompt injection and output leakage, and logged interventions to provide auditable evidence for compliance reviews. The alternative using self-harm filters, denied forgery topics, and comprehensive logging without PII controls fails by omission of data protection, leaving passport numbers unmasked in prompts, completions, and traces despite strong safety blocking and auditability. Another alternative using self-harm filters and passport redaction with logging but no denied forgery topic fails by lacking deterministic refusal, since general harm filters alone do not reliably classify and refuse the restricted forgery use case with consistent policy behavior. The alternative applying full filters, denied topics, and redaction only to model responses fails by incomplete directionality, allowing malicious prompts containing self-harm requests, forgery instructions, or embedded passport data to reach the model and persist in upstream logs before any intervention. Exam caveat: do not confuse detective or perimeter controls such as post-hoc transcript scanning, WAF rules, or IAM invocation limits with inline generative filtering, because only Guardrails intercepts and transforms the prompt and completion in real time. Practical check: verify the Guardrail shows enabled harm categories, a defined denied topic for document forgery, passport PII configured to redact, both input and output toggles enabled, and intervention events delivering to logging for audit sampling.