
A fintech launches a Bedrock chat assistant for investment education in two regions. Regulators require blocking disallowed advice topics, filtering hate and violence, and redacting SSNs and account numbers before logging. Prompts alone have leaked PII in testing. Which Bedrock Guardrails design enforces content filtering and compliance controls?
Select an answer to reveal the explanation.
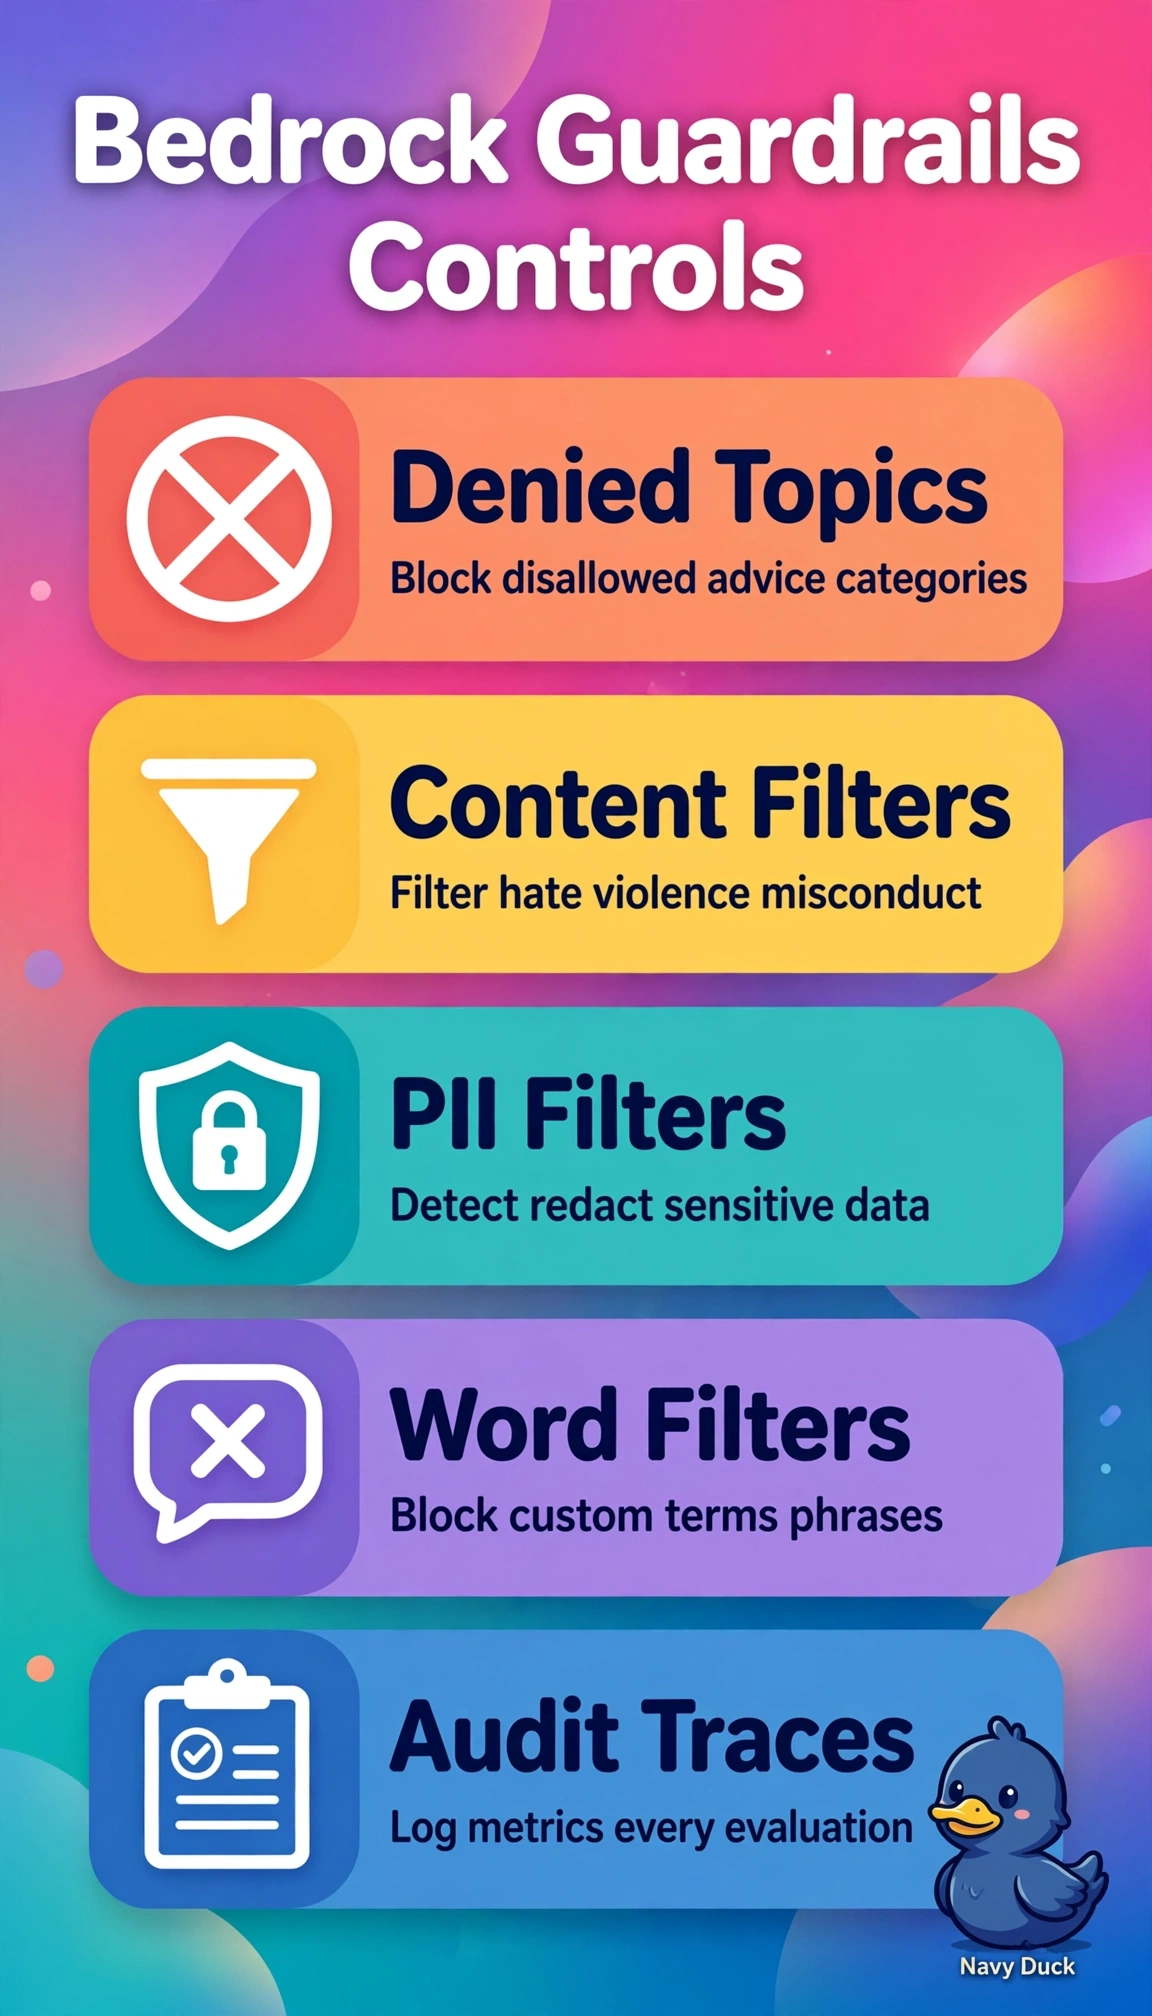
Short Explanation
You get reliable enforcement when guardrails sit outside the model. Guardrails act like a seatbelt that filters topics, toxicity, and PII on every call.
Full Explanation
The correct design is right because Bedrock Guardrails enforces controls outside the prompt with three complementary mechanisms that map directly to the obligations: denied topics deterministically blocks disallowed investment-advice categories, content filters handle hate and violence with consistent thresholds, and sensitive-information redaction on both inputs and outputs removes SSNs and account numbers before transcripts reach logs, which is critical since testing showed prompts alone leak PII. The outputs-only design fails by directionality because PII in the user input would be logged before generation, so redaction must apply at input ingestion rather than only at response time. The single-Region design fails by scope because compliance must hold wherever inference runs, so deploying only in one Region leaves the second Region unprotected during local serving or failover. The prompt-based topic limits design fails by enforcement strength because instructional text is advisory and bypassable, while denied topics provide policy-level blocking with auditability regulators expect. An exam caveat is to separate native content filters for hate and violence from denied topics for custom prohibited advice and from PII redaction for privacy, since scenarios deliberately test that precise mapping. A practical check is to version the same guardrail in both Regions, submit test inputs containing a fake SSN, account pattern, disallowed advice request, and hateful phrase, then confirm blocked or filtered responses and verify stored transcripts show redacted placeholders with no raw values.