
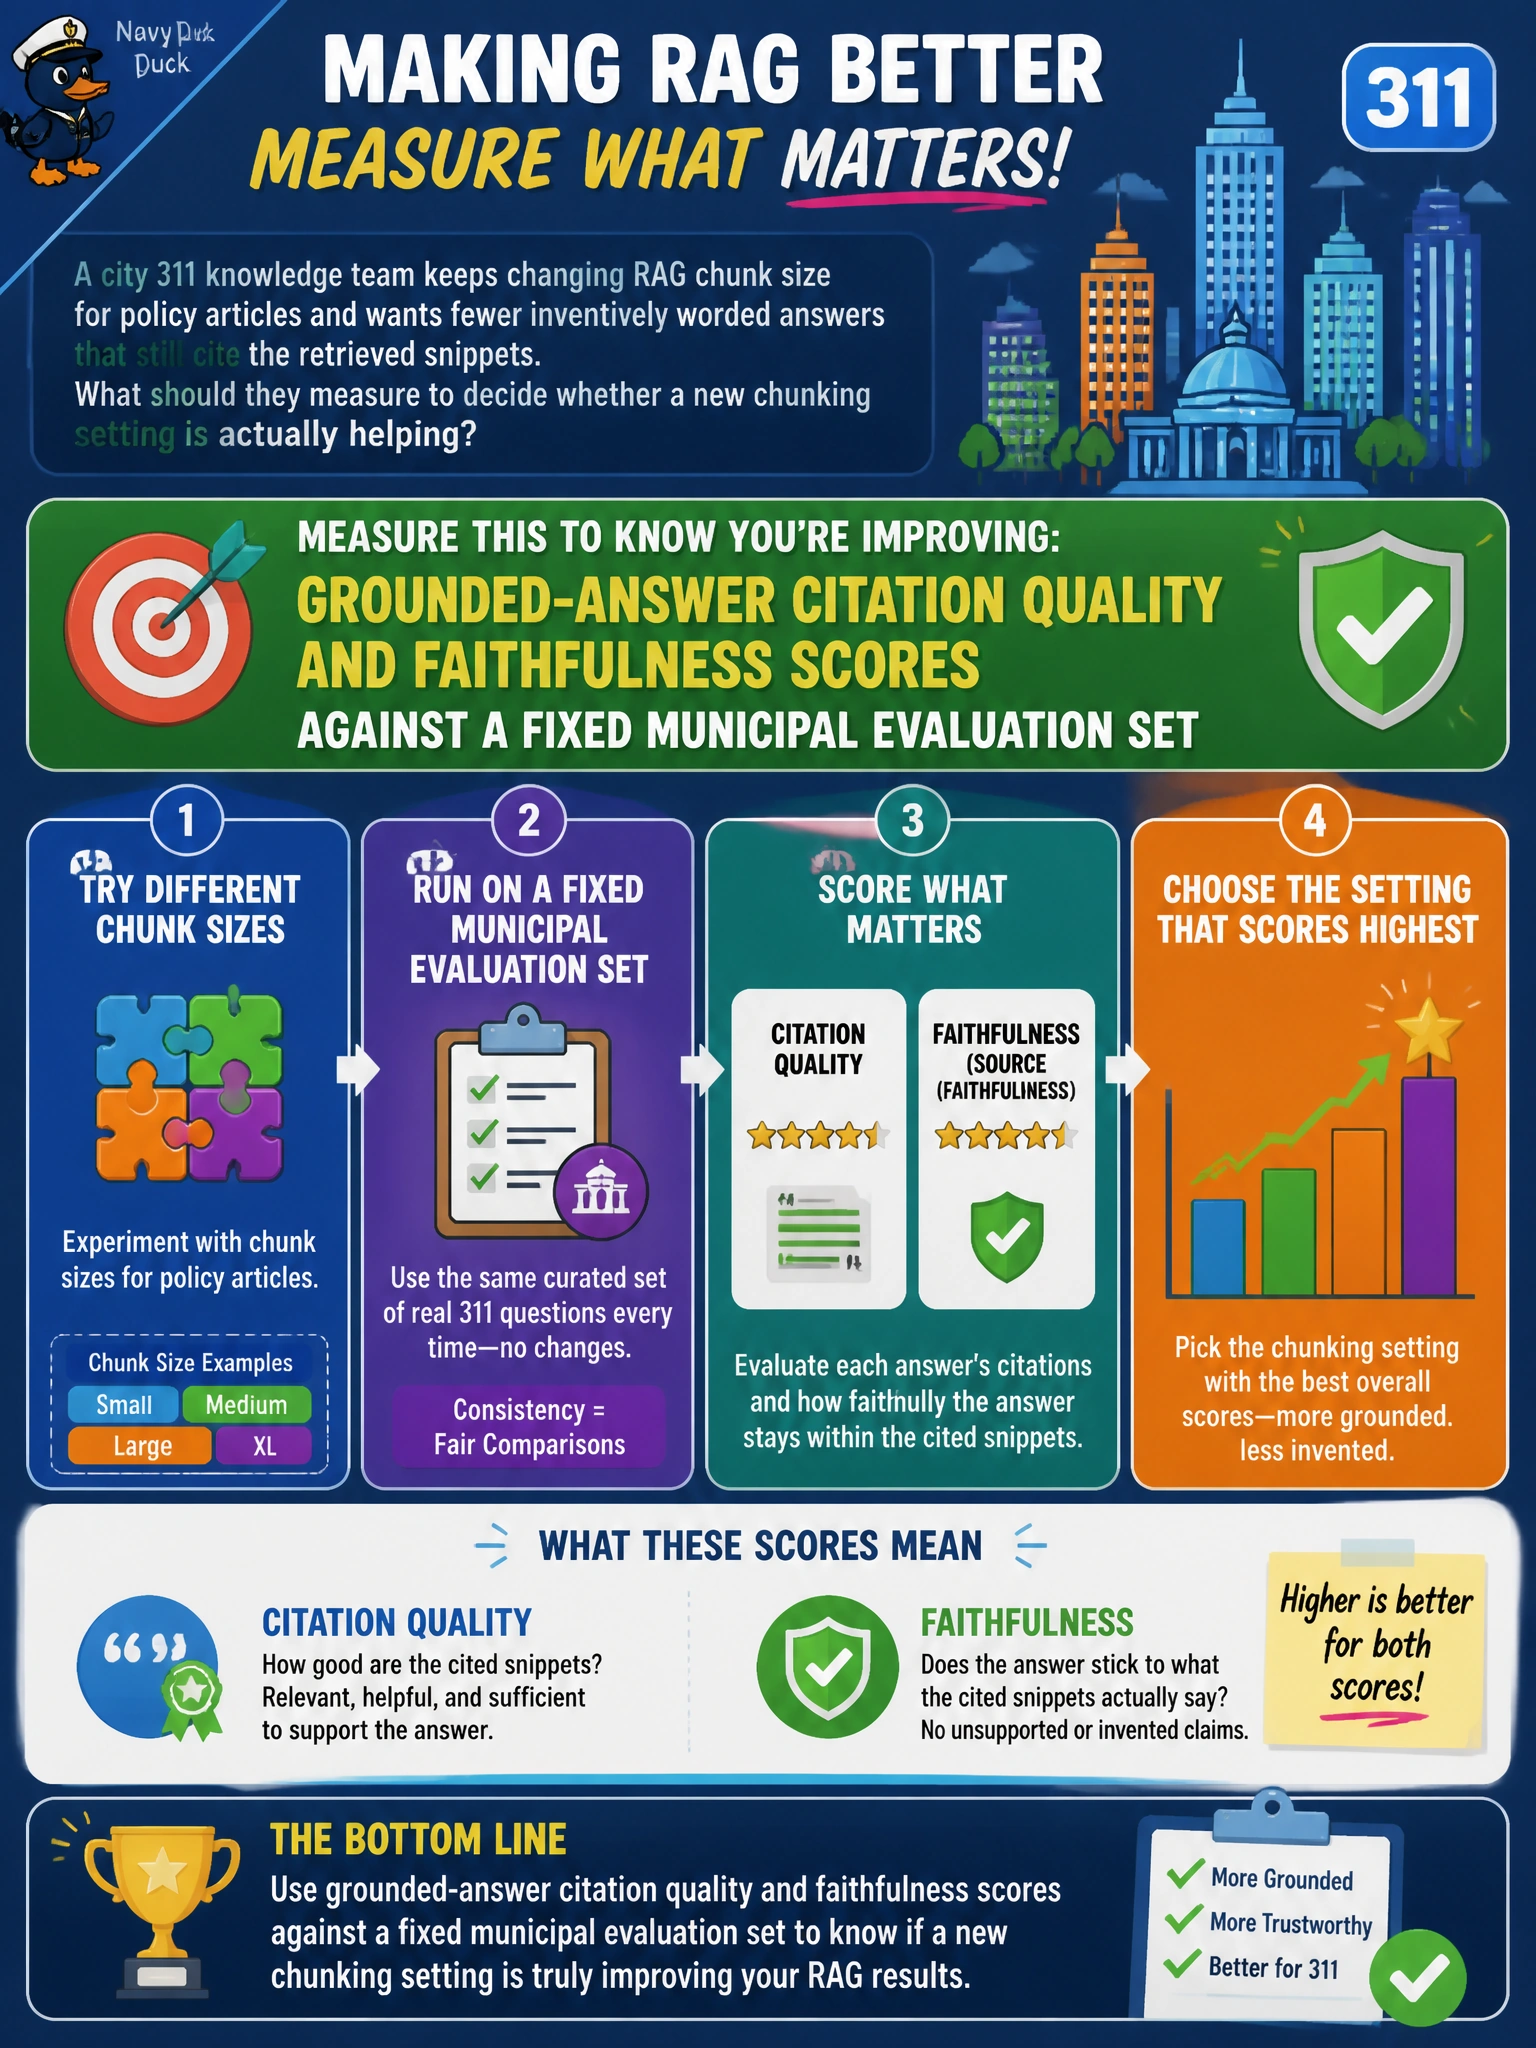
A city 311 knowledge team keeps changing RAG chunk size for policy articles and wants fewer inventively worded answers that still cite the retrieved snippets. What should they measure to decide whether a new chunking setting is actually helping?
Select an answer to reveal the explanation.
Short Explanation
Think of chunk size like how you slice a city code book for a librarian—too big and the quote is mushy, too small and the quote loses the section title. You judge the cut by whether answers still point to the right page, not by how fancy the knife looks. Track citation faithfulness on a fixed 311 eval set when you tweak chunks.
Full Explanation
Chunk size in a municipal RAG pipeline is an evidence-geometry decision: it changes which policy sentences land in each vector, how citations align to ordinance sections, and whether the foundation model can stay faithful to retrieved 311 knowledge snippets. When a city 311 team tunes chunking to reduce inventively worded answers that still cite sources, the decisive measures are grounded-answer citation quality and faithfulness scores on a fixed municipal evaluation set—held queries with known approved snippets and acceptable answer shapes. Compare those scores before and after each chunking change; improvement means fewer unsupported claims and better cite-to-snippet alignment, not merely shorter or longer segments. Bedrock on-demand token price by Region is a cost and capacity signal; it does not tell you whether residents received hallucinated policy. Prompt Management publish counts measure template churn and governance activity, not retrieval faithfulness after a chunk resize. An embedding model’s marketing page listing a larger context window describes vendor capacity, not whether your civic corpus segments retrieve the right article clauses. Exam caveat: items often bait candidates to optimize cost dashboards or vendor brochure metrics when the stem asks whether grounded answers improved—tie evaluation to faithfulness and citation quality on a stable civic test set. Operational check: freeze an eval pack of policy questions with gold snippets, score citation presence and contradiction rates after each chunk experiment, keep chunk parameters versioned with the knowledge index build, and roll back settings that raise inventiveness without raising faithfulness.