
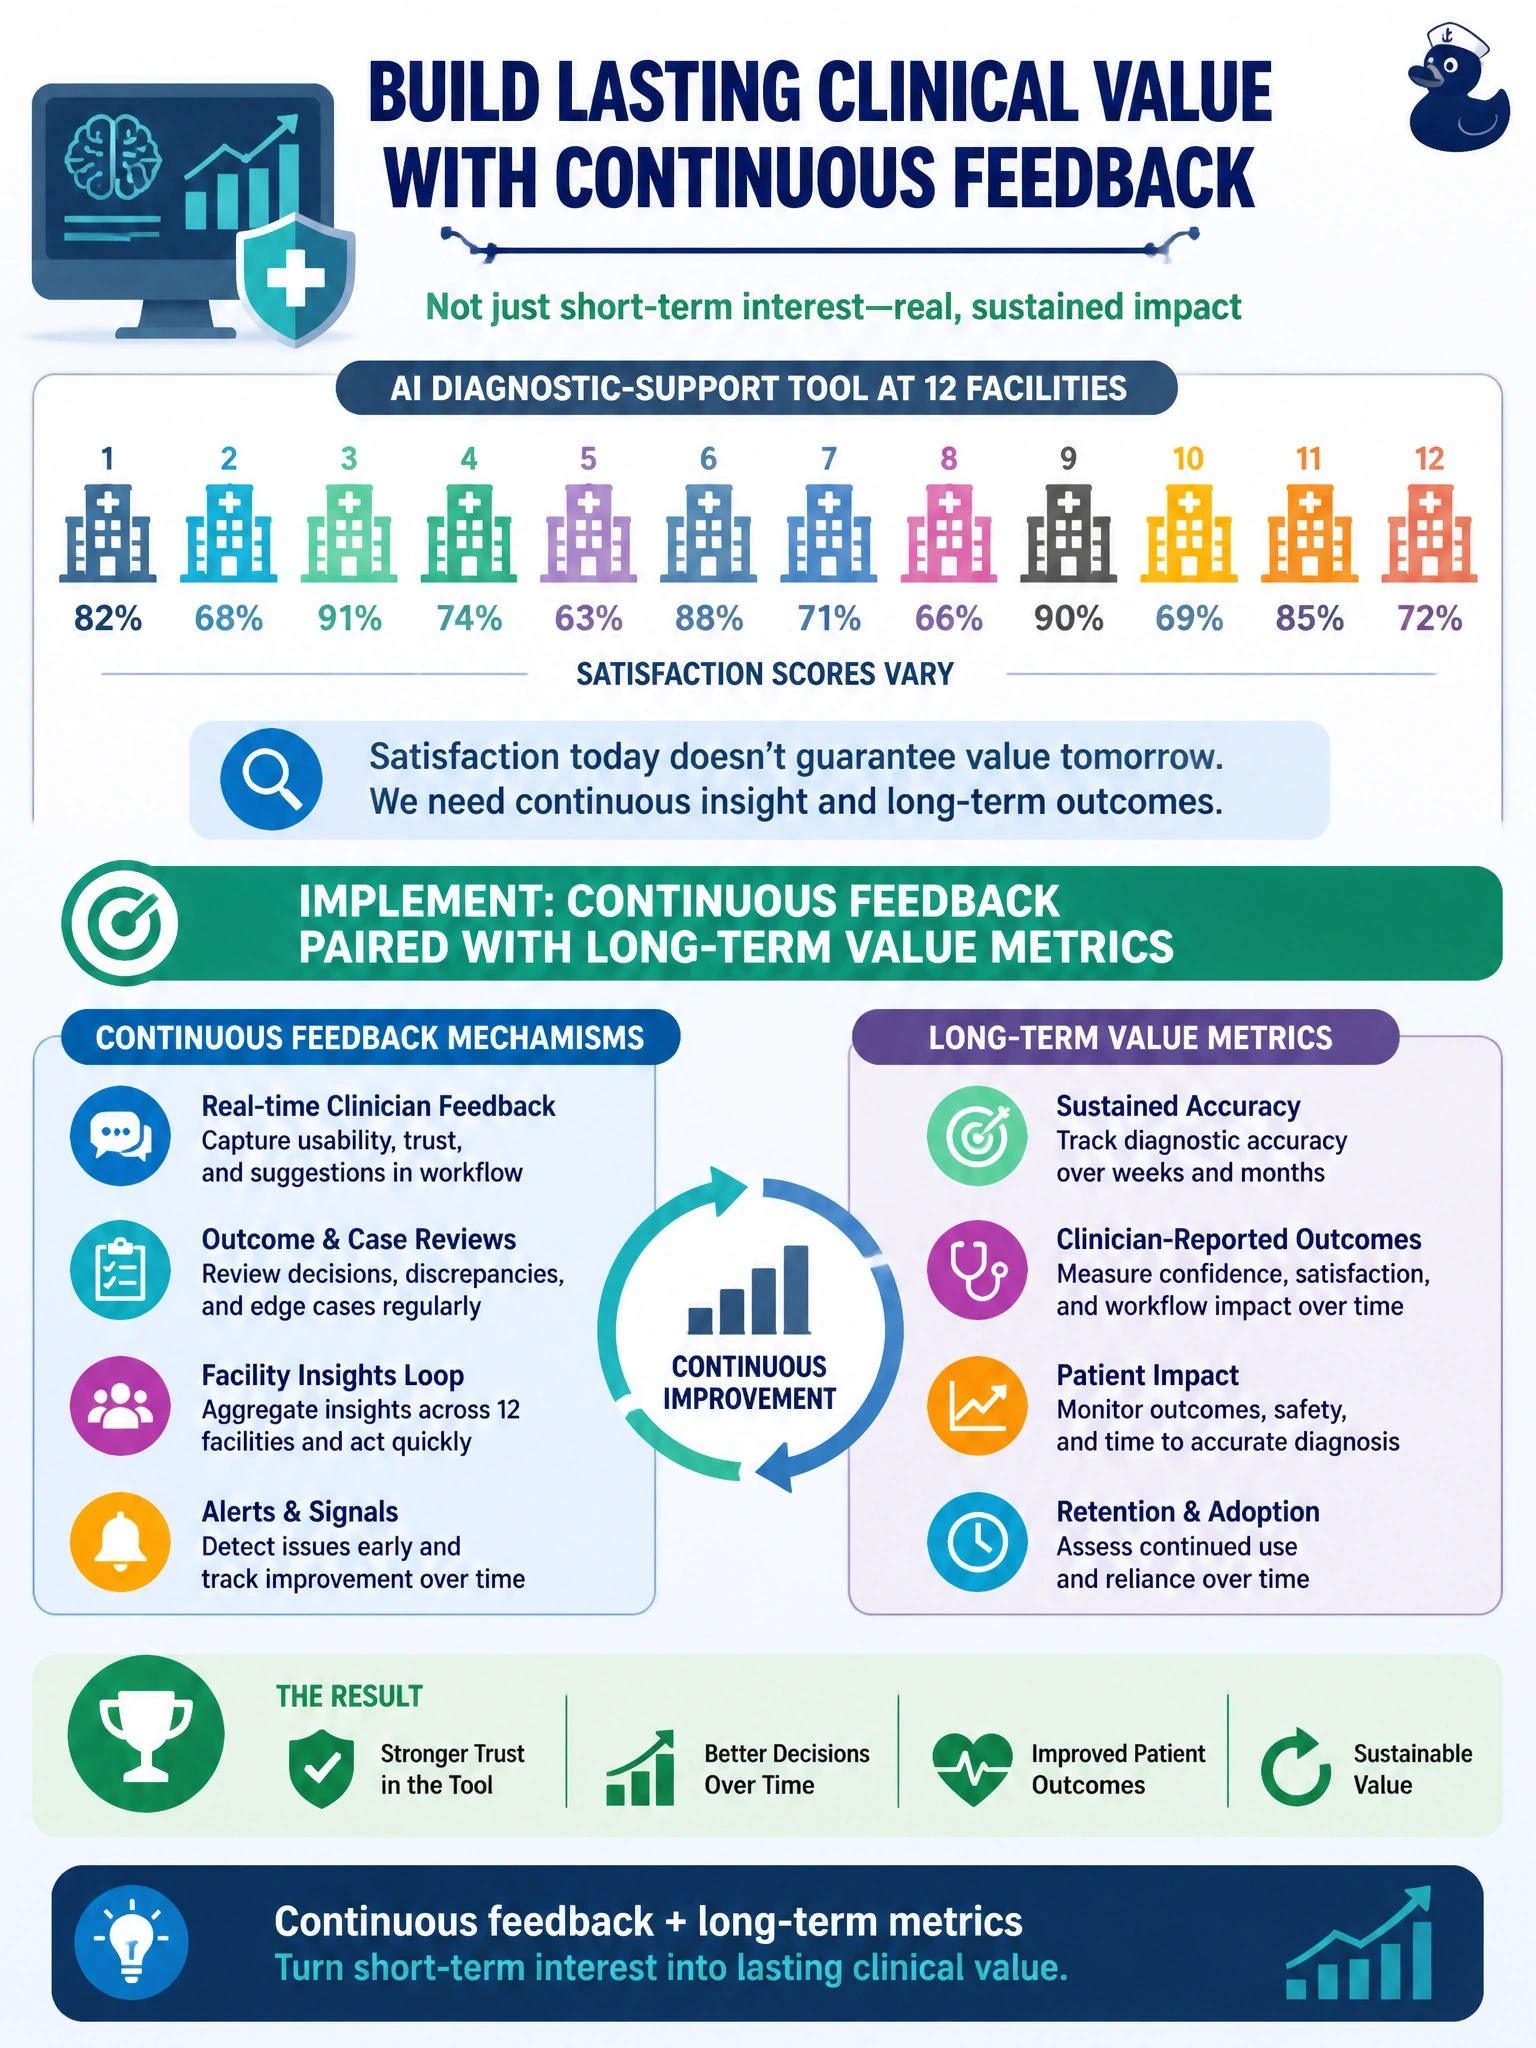
A hospital's AI diagnostic-support tool has scaled to 12 facilities. Each facility reports different satisfaction scores, and leadership cannot tell whether the tool is creating long-term clinical value or just generating short-term novelty interest. What should the transformation team implement?
Select an answer to reveal the explanation.
Short Explanation
Think about how excited you get about a new gadget in week one versus whether you're still using it a year later — that gap is exactly what novelty interest hides. Tracking sustained accuracy and clinician feedback over time, not just once at launch, is what separates real clinical value from initial buzz. One survey right after go-live can't tell you that difference.
Full Explanation
Distinguishing sustained clinical value from short-term novelty requires ongoing measurement over time, which is exactly what continuous feedback combined with metrics like sustained accuracy and clinician-reported outcomes provides. A single companywide satisfaction survey conducted right after each facility's go-live captures only the moment when novelty interest is highest, so it can't distinguish a lasting improvement from initial enthusiasm that's likely to fade. Imposing a moratorium on further scaling until every facility reports identical satisfaction scores sets an unrealistic bar; facilities differ in workflows, patient populations, and staff, so expecting uniform scores everywhere would halt progress without ever answering the actual question about value over time. Removing the tool from any facility reporting lower satisfaction without further investigation reacts to a single data point, risking the loss of a genuinely valuable tool based on a factor that might be facility-specific rather than a real problem with the tool itself. The operating principle: distinguishing durable value from initial novelty requires feedback mechanisms and metrics sustained over time, not a single measurement point or an all-or-nothing reaction to variation across sites. Operational check: is the same metric being tracked at multiple points in time, well past the initial go-live period, before any conclusion is drawn?