
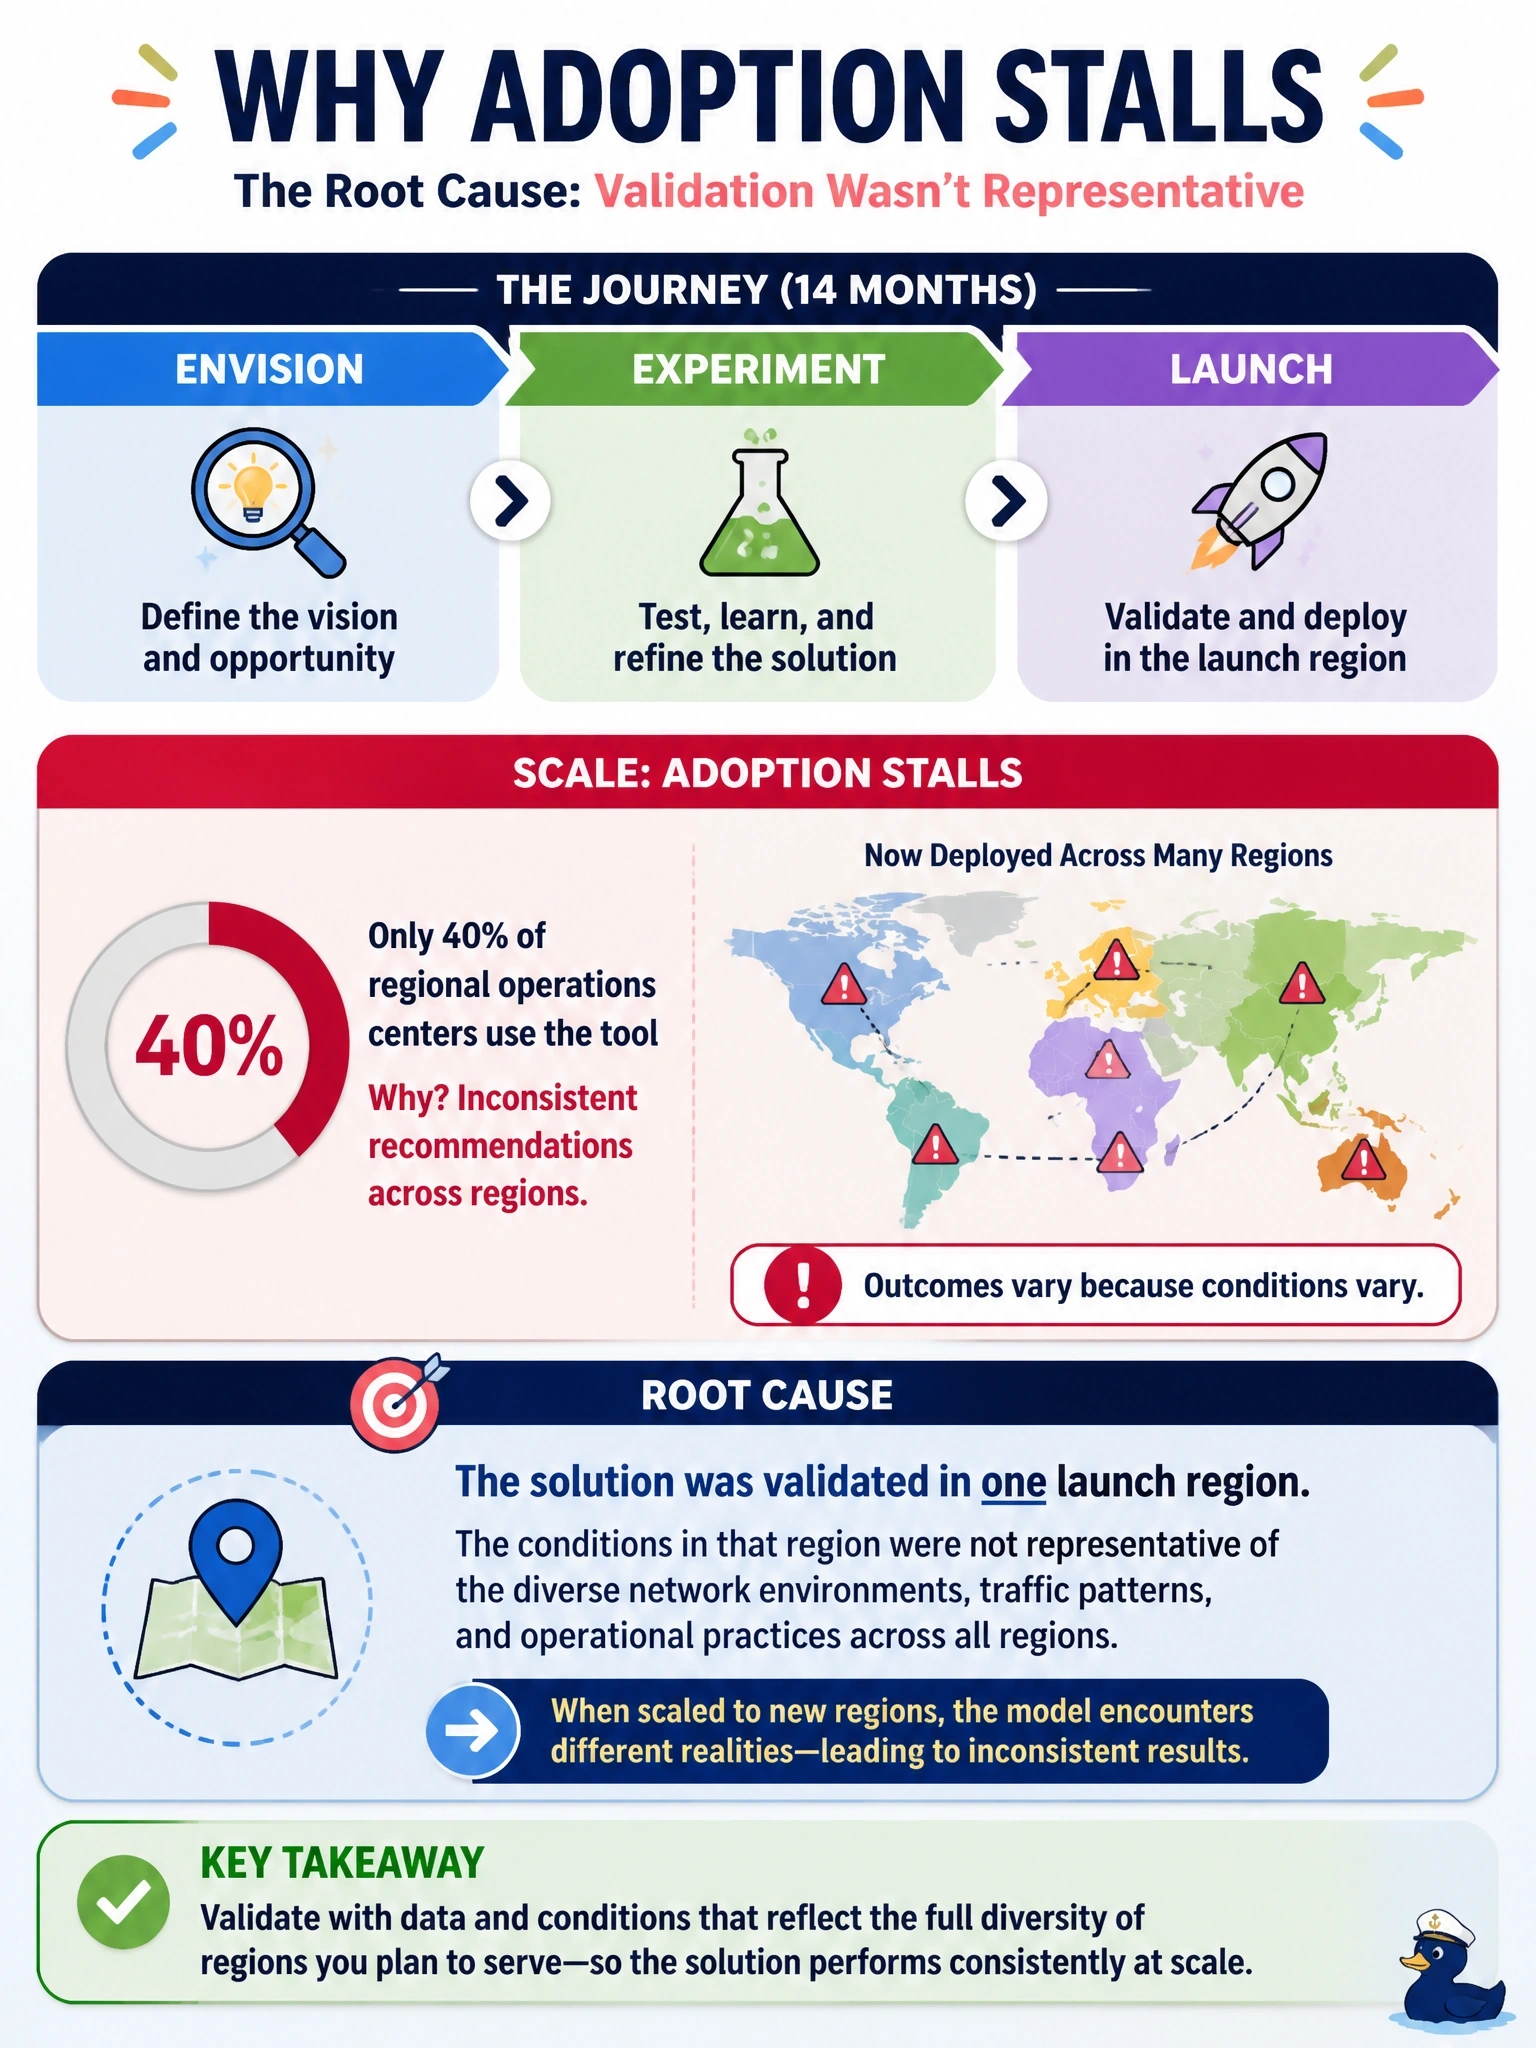
A telecom provider's network-fault-prediction AI moved through envision, experiment, and launch phases over 14 months. During scale, adoption stalls: only 40% of regional operations centers use the tool, citing inconsistent recommendations compared to the original launch region. What is most likely the underlying cause?
Select an answer to reveal the explanation.
Short Explanation
A recipe that nails it in one kitchen can flop in another — different ovens, different ingredients, and you'd expect that. Here, launch only proved the model against one region's network conditions, and now you're seeing regions with different conditions get inconsistent results, which is a validation gap, not staff resistance or a swapped-out model.
Full Explanation
The specific complaint — inconsistent recommendations compared to the original launch region — points directly at unrepresentative validation: launch proved the model against one region's network conditions, and scale is now exposing regions where those conditions don't hold. A general claim that new regional staff are resistant to changing established habits doesn't fit the evidence; the complaint is specifically about recommendation quality, not reluctance to try the tool at all, so resistance to change is a generic distractor that doesn't match what's described. Blaming unrealistic objectives set during envision doesn't fit the timeline either — an unrealistic business objective set that early would typically show up as an inability to get approval to launch in the first place, not as inconsistency appearing later, after regions with different conditions get added during scale. A claim that the underlying AI service was quietly swapped for a different model is pure speculation with nothing in the scenario to support it. The operating principle: inconsistency that appears specifically at scale, right after a successful launch, is a strong signal that the conditions validated during launch weren't representative of the full enterprise footprint. Operational check: when scale reveals inconsistent results, compare the new regions' operating conditions against those of the original launch region first.