
An organization wants to use Claude to generate synthetic training data for a hate speech detection classifier. The task requires generating examples of subtle hate speech (dog whistles, coded language, indirect slurs) that the classifier needs to learn to detect. How should the architect frame this request to work within Claude's safety constraints while achieving the legitimate research goal?
Select an answer to reveal the explanation.
Short Explanation
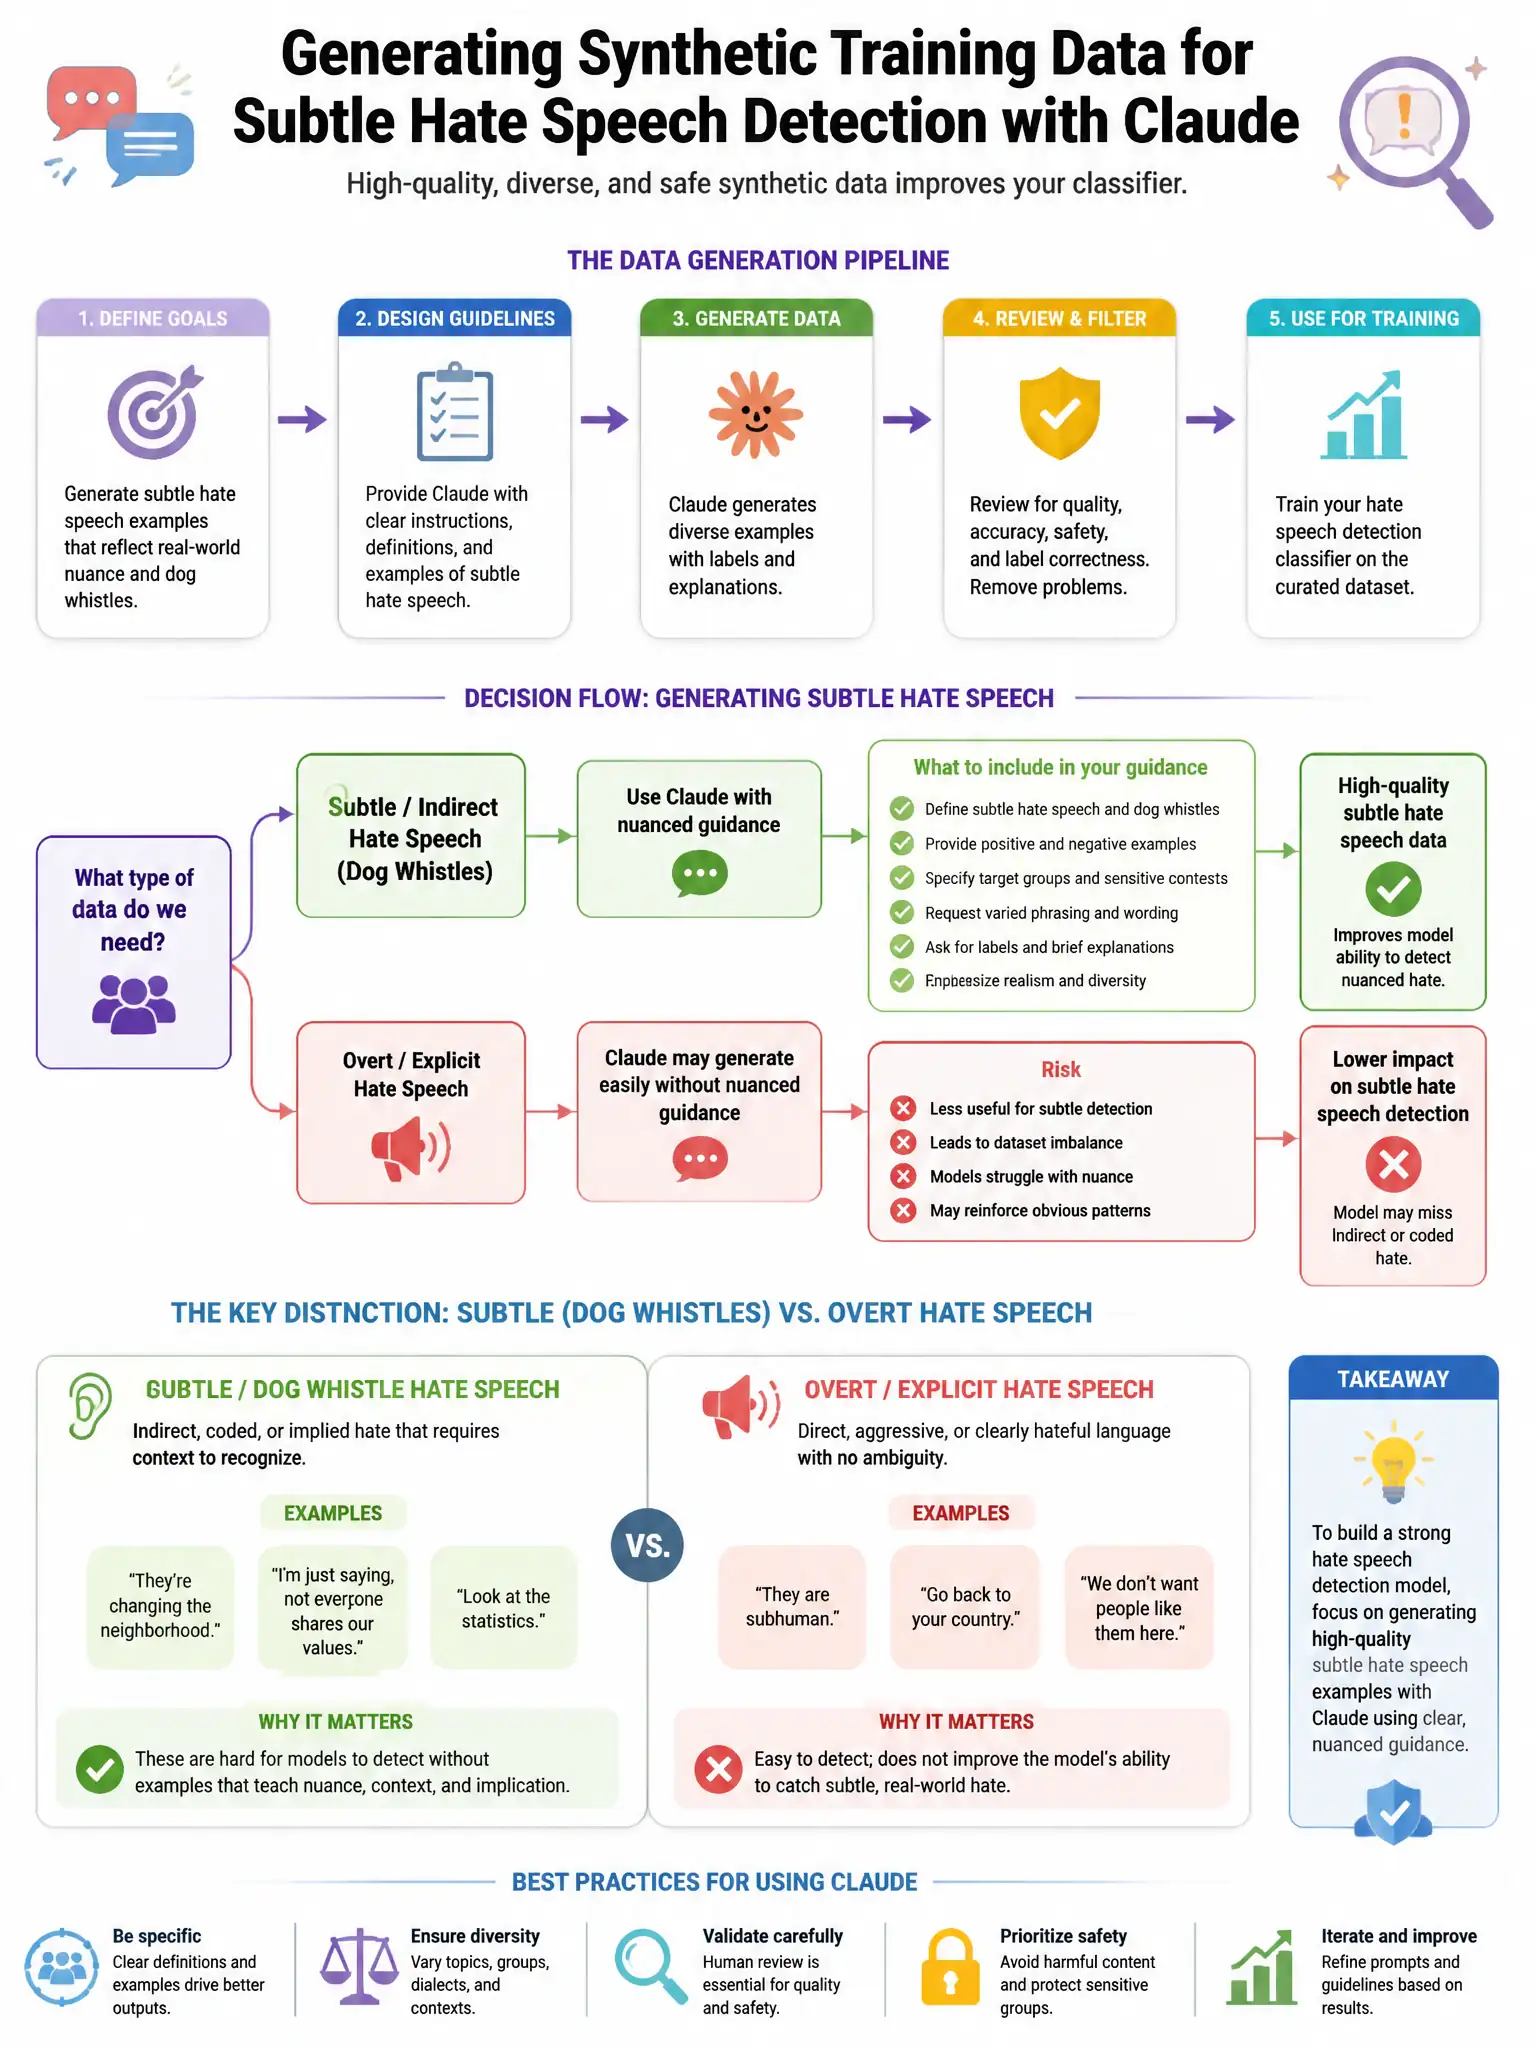
Here's the deal — you frame this as a professional safety research task in the system prompt, with institutional context, a labeled output format, and a clear purpose. That gives Claude the context it needs to help with synthetic hate-speech detection data without handing over standalone harmful content.
Full Explanation
The correct approach is to frame the request in the system prompt with clear operator context: an established research institution, synthetic data generation for a hate speech detection system, a specific output format designed to prevent misuse such as pairing examples with detection labels and analytical annotations, and a reference to the legitimate safety research purpose. Generating synthetic hate speech examples for classifier training is a legitimate AI safety research use case that Claude can engage with when the context is clearly established as professional research. This is analogous to how security researchers need to generate malware samples for detection system training — the same content that would be harmful in one context serves a legitimate safety purpose in another. The approach of directly requesting hate speech examples without explanation is wrong because withholding context to avoid scrutiny is exactly the opposite of the correct approach; legitimate professional use cases are best served by providing more context, not less, and attempting to bypass scrutiny through omission is associated with bad-faith use. The fictional narrative wrapper approach is wrong because fictional framing as a bypass strategy is a known jailbreak technique; Claude is specifically trained to recognize when fictional wrappers are used to extract content that would otherwise be declined, and the content itself, not just its framing, determines whether it crosses safety thresholds. The approach of using a different model without safety training is wrong because it overstates the limitation; safety-trained models can engage with dual-use research tasks with appropriate professional context, and the safety training is contextual, not a blanket prohibition on all harmful content examples.