
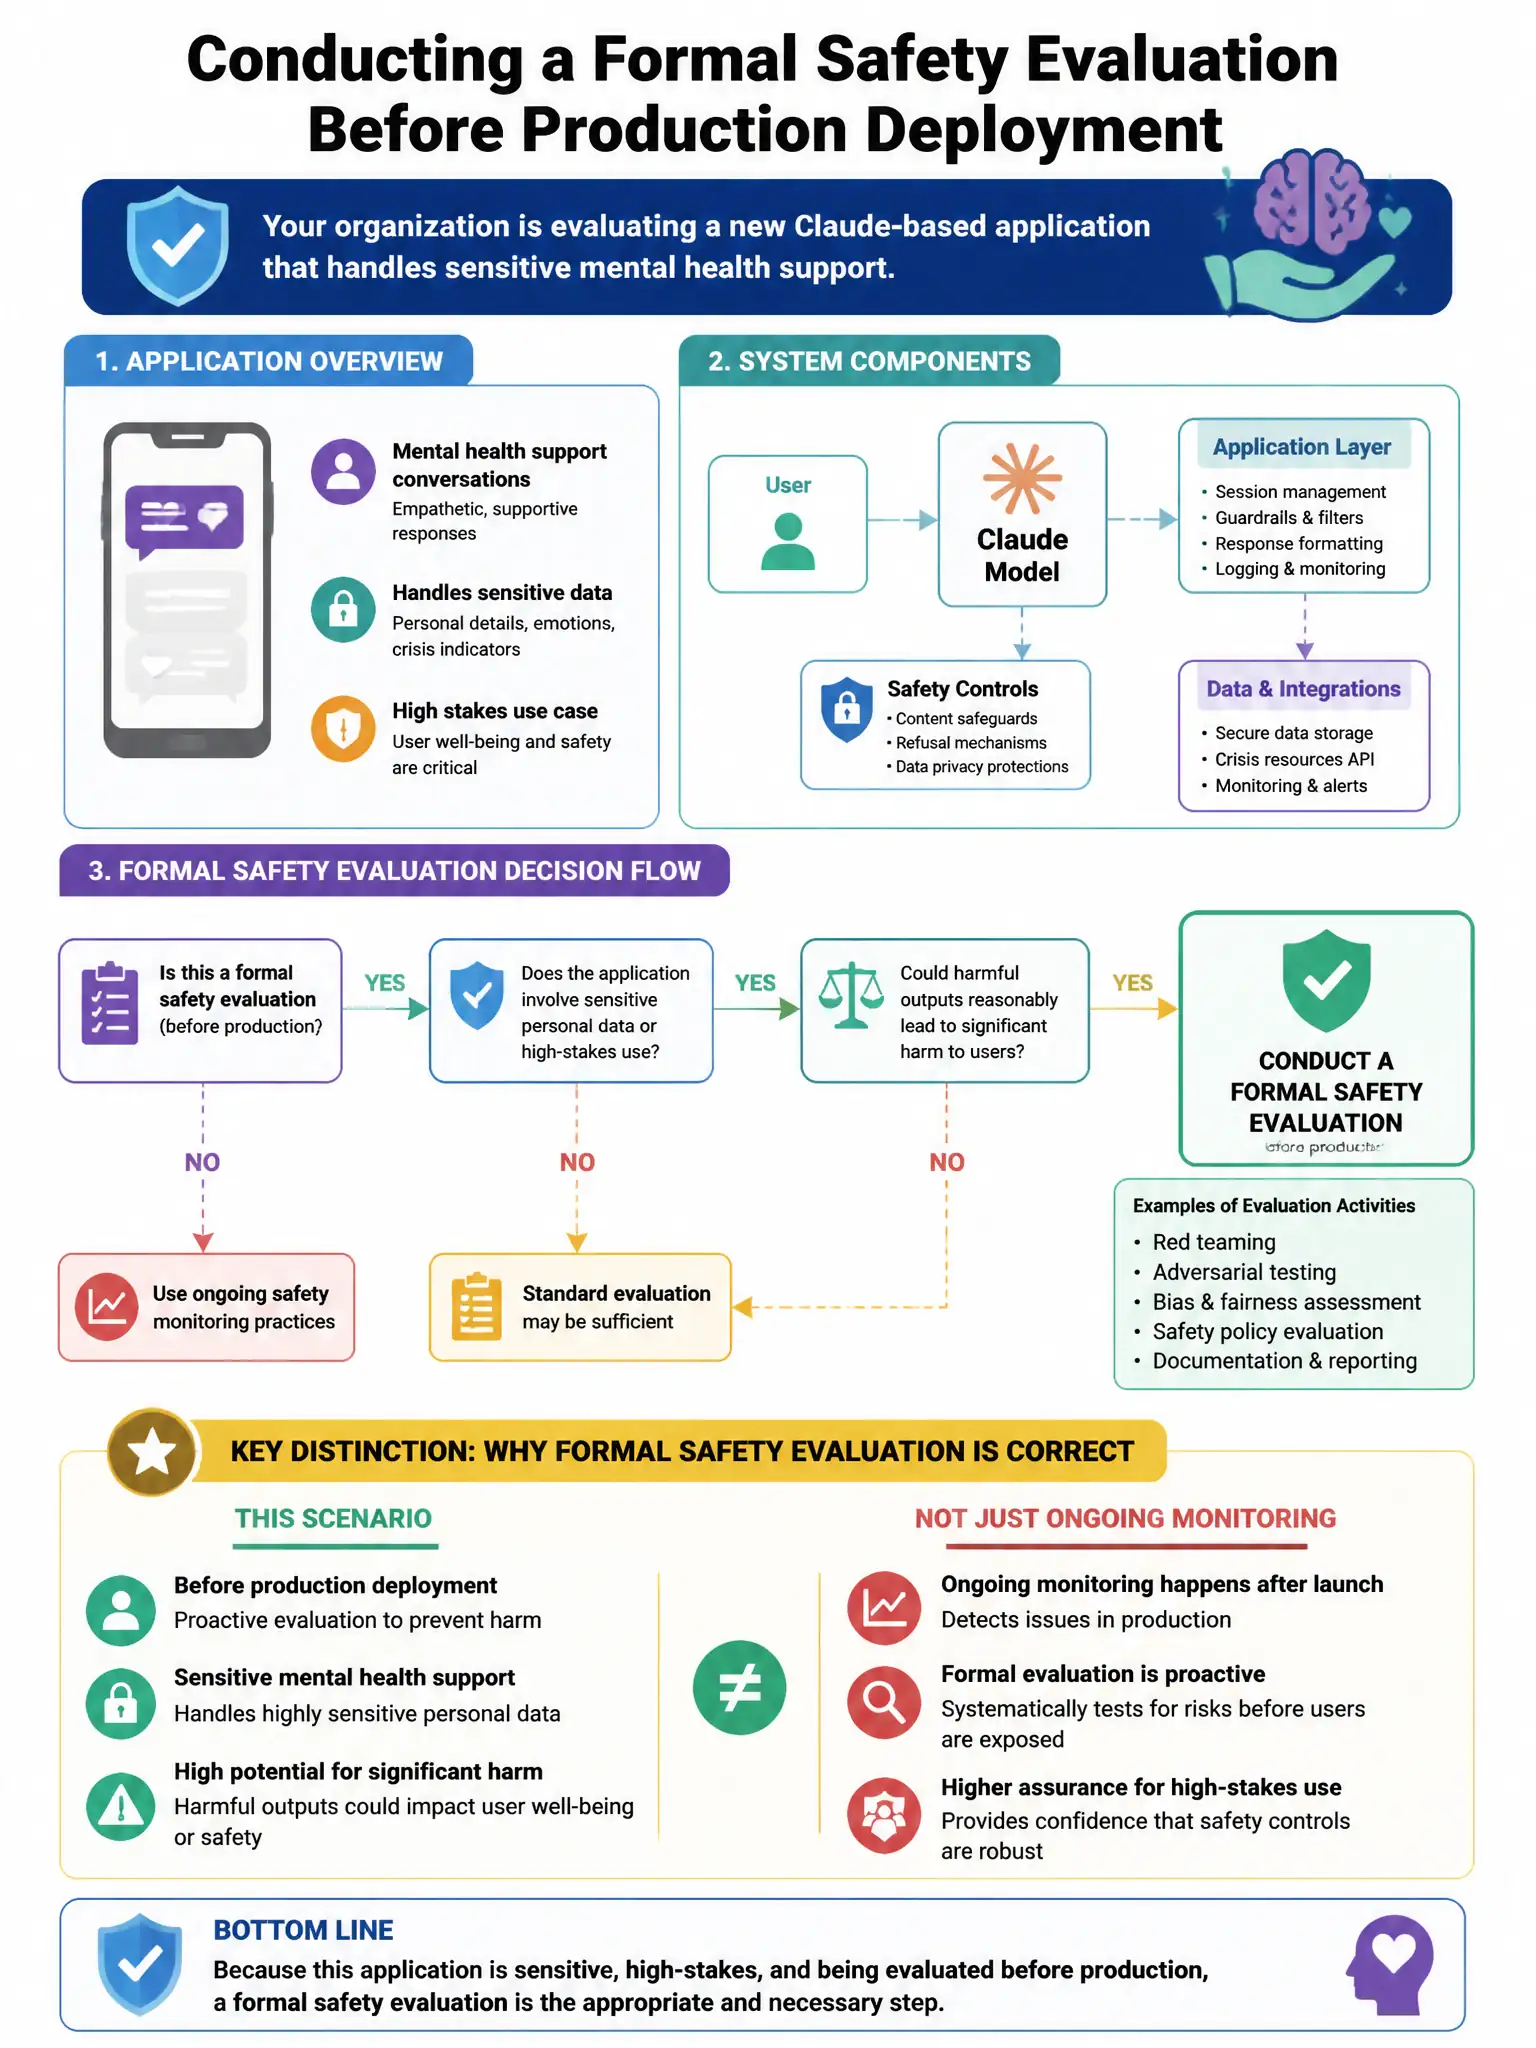
Your organization is conducting a formal safety evaluation of a new Claude-based application before production deployment. The application handles sensitive mental health support conversations. What evaluation framework elements are essential for a rigorous pre-deployment safety assessment?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need a red team evaluation that probes crisis escalation, inappropriate advice or diagnosis, referral triggering, demographic consistency, and unusual emotional states, plus ongoing post-deployment monitoring. Mental health apps can't be certified by functional checks alone, because the dangerous failures are adversarial and context-dependent.
Full Explanation
The red team evaluation covering adversarial probes for crisis escalation handling, tests for inappropriate advice-giving or diagnosis, evaluation of referral-to-professional-help triggering, demographic consistency testing, and model behavior under unusual user emotional states — combined with ongoing post-deployment monitoring — is correct because mental health support applications require adversarial safety evaluation, not just functional testing. The rigorous pre-deployment framework must include red team probing for the specific failure modes in this domain: inadequate crisis response, such as failing to escalate active suicidality, inappropriate clinical advice or diagnosis, failure to route to professional help when warranted, and demographic inconsistency, meaning responses should not vary inappropriately based on perceived user identity signals. Ongoing post-deployment monitoring is essential because red teams cannot exhaustively cover all real-world inputs. The automated safety classifier approach is wrong because no automated classifier provides sufficient coverage for sensitive mental health edge cases; automated tools miss nuanced contextual failures that require human judgment to identify. The user satisfaction survey approach is wrong because user satisfaction measures whether users like the experience, not whether the application is safe; users in mental health crisis may prefer responses that are engaging but harmful. The small expert-reviewed sample approach is wrong because a 100-conversation sample reviewed by one expert is statistically insufficient for a sensitive application and does not cover the adversarial probe space needed to surface edge-case safety failures.