
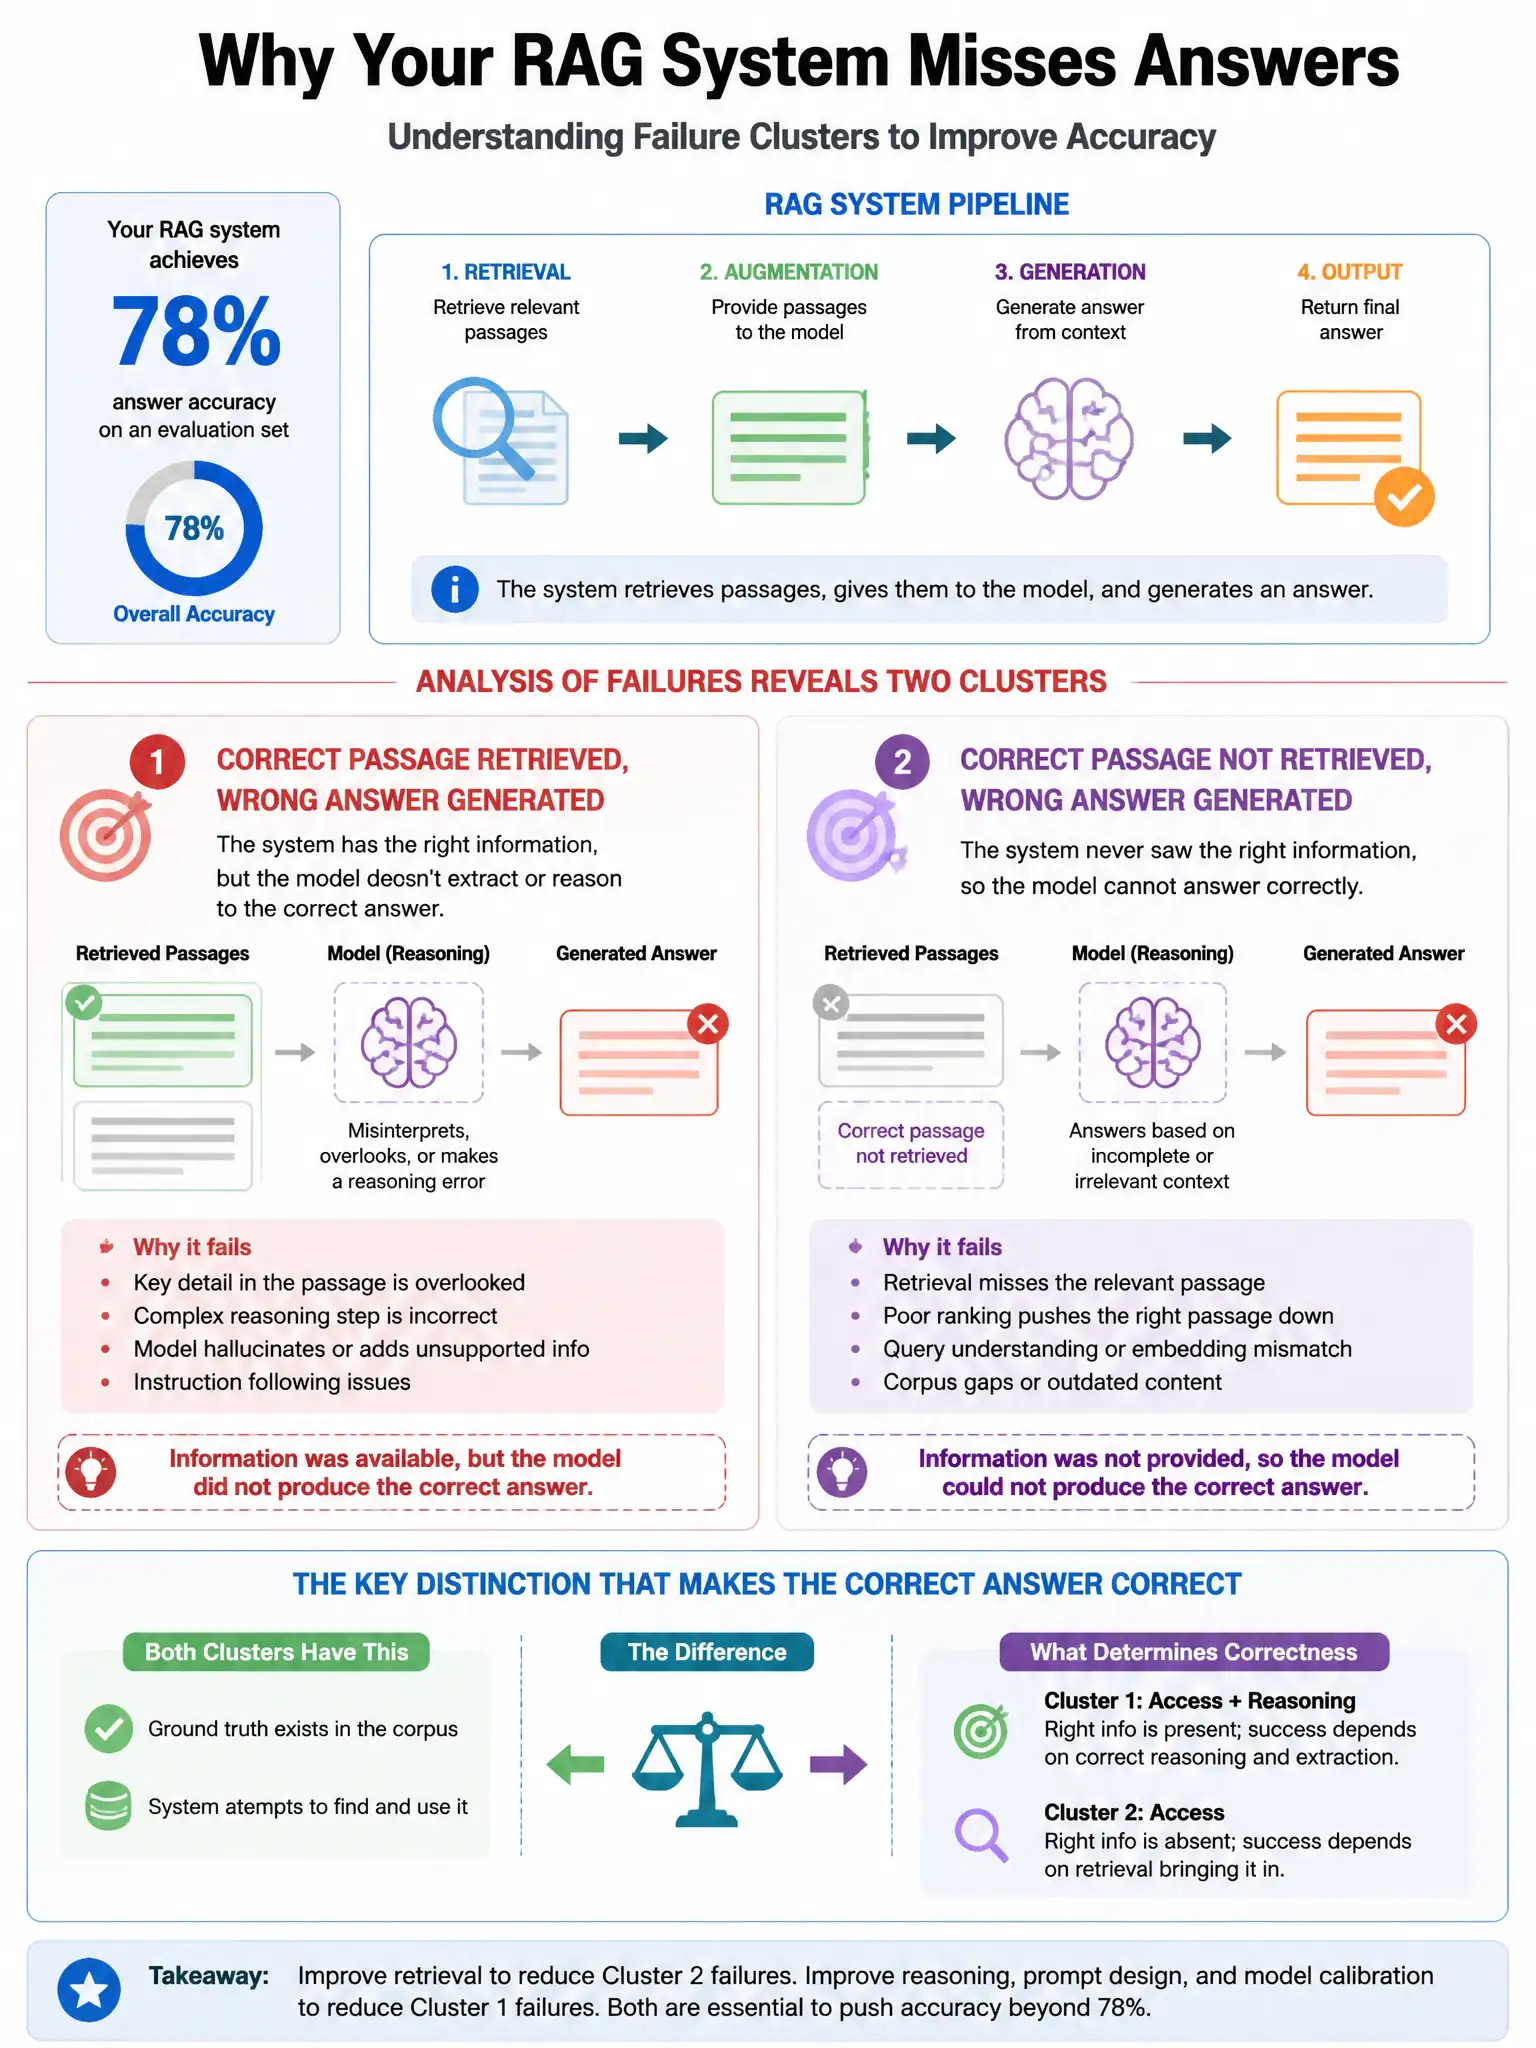
Your RAG system achieves 78% answer accuracy on an evaluation set. Analysis of failures shows two clusters: (1) questions where the correct passage is retrieved but the answer is wrong (generation failure), and (2) questions where the correct passage is not retrieved (retrieval failure). They split roughly 40/60. The team has budget to address only one. Which intervention has higher expected impact?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you should fix retrieval first because it's the bigger failure cluster. If the right passage isn't in the context, even the best LLM can't answer correctly, so improving retrieval unlocks the most accuracy.
Full Explanation
The correct intervention is to address retrieval failures first, because retrieval is the binding constraint in a RAG system. Retrieval failures (60%) represent cases where the correct passage exists in the corpus but is not found — fixing retrieval converts these into generation-tractable cases. Even a perfect LLM cannot produce the right answer when the context window does not contain the right passage. The 60% retrieval failure cluster is the larger failure mode and the higher-ROI fix. The option that proposes improving the generation component by switching to a more capable LLM is wrong because generation failures (40%) are the smaller cluster, and addressing the smaller cluster first while leaving the larger one unaddressed maximizes the remaining error rate; that logic inverts the correct priority. The option that says to address generation failures first because retrieval failures indicate the corpus does not contain the answer is wrong because retrieval failures are explicitly described as cases where the correct passage is not retrieved — this implies the corpus contains the relevant content but retrieval fails to surface it. This is a retrieval system problem, not a corpus coverage problem. The option that proposes improving both simultaneously by fine-tuning the embedding model on the evaluation set is wrong because fine-tuning the embedding model on an evaluation set introduces evaluation leakage — the model trains on its own benchmark — and embedding models do not affect generation quality; they are separate pipeline stages.