
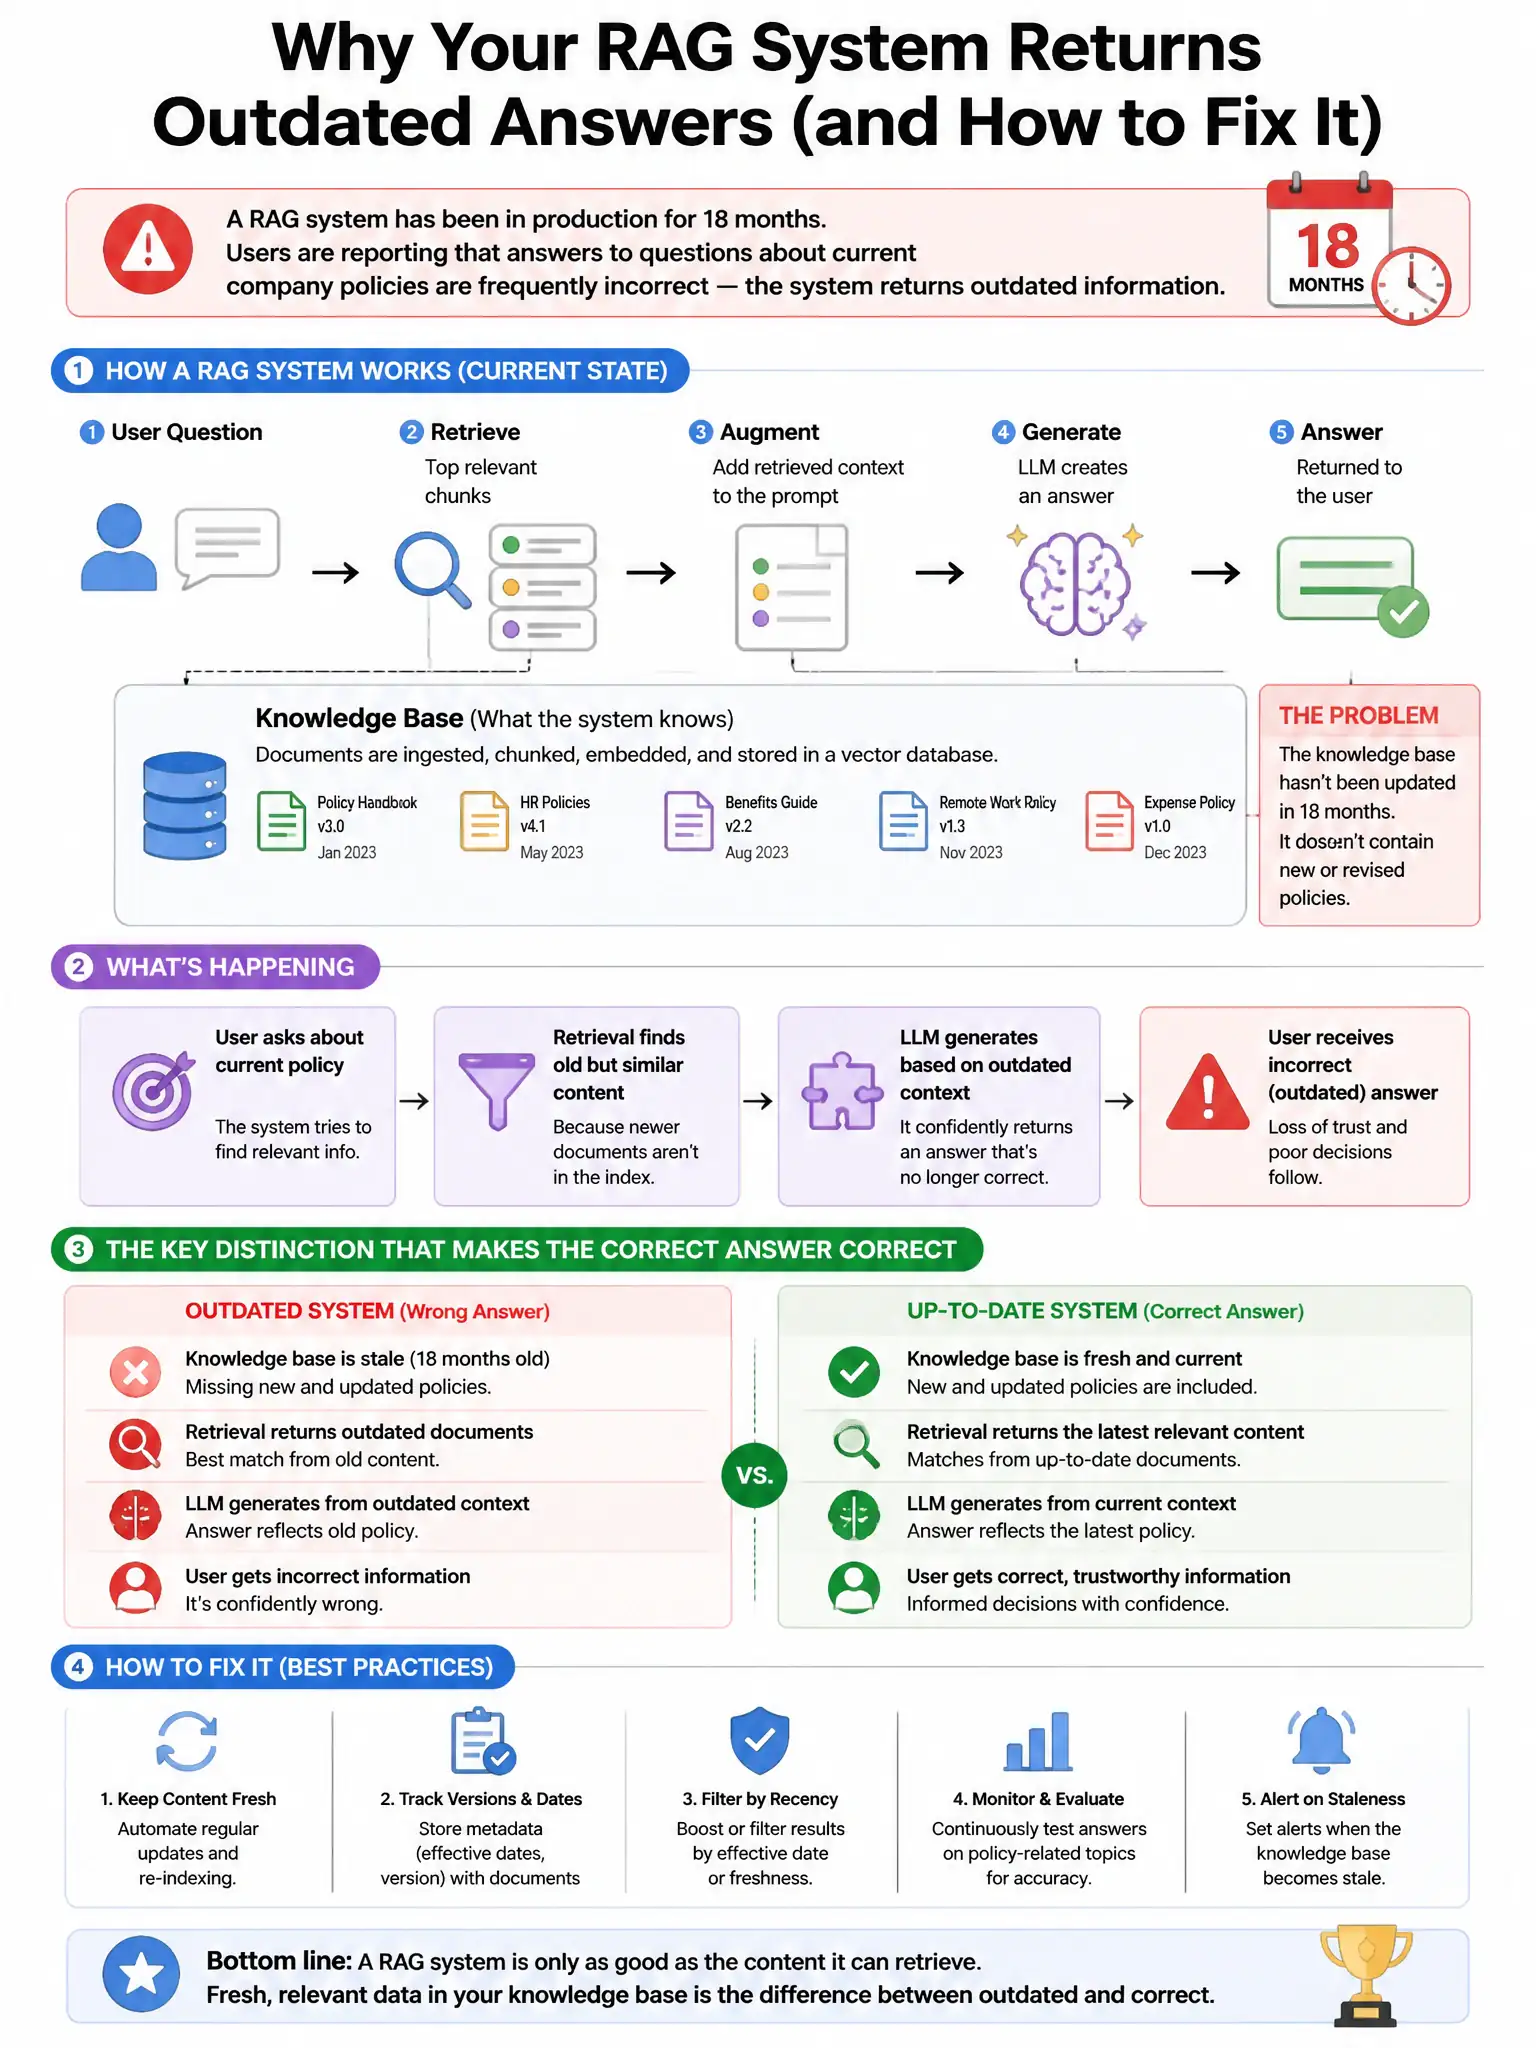
A RAG system has been in production for 18 months. Users are reporting that answers to questions about current company policies are frequently incorrect — the system returns outdated answers confidently. The corpus was indexed 18 months ago and has not been updated. The embedding model was not changed. What is the most likely cause, and what is the remediation?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you're dealing with stale documents, not broken model weights. The index still holds 18-month-old policy text, so it confidently returns outdated answers. Re-index on document changes, add timestamps, and flag answers from docs older than 90 days.
Full Explanation
The stale-corpus answer recommending automated re-indexing on document modification events, metadata timestamps, and flags for documents modified more than 90 days ago is correct because the described problem — stale answers from 18-month-old indexed content — represents corpus-freshness failure. Company policies change, and static indexes return outdated information confidently because retrieved passages were accurate at index time. The remediation requires: (1) keeping the index current via event-driven re-indexing on document changes, (2) surfacing document timestamps in retrieved context so the LLM can reason about recency, and (3) flagging or caveating answers based on stale source material. The embedding-drift answer recommending re-indexing with the current embedding model version is wrong because embedding model weights do not drift after deployment — they are static artifacts. The 'continued training by the provider' claim is incorrect; the deployed embedding model API serves one fixed model version. The index-fragmentation answer recommending optimization/compaction jobs is wrong because vector index fragmentation affects query performance (latency, throughput) but not retrieval accuracy — vector similarity scores are geometric and do not degrade due to index structure. The LLM-drift answer attributing degradation to Anthropic's continuous training updates is wrong because the symptom (confident outdated policy answers) points directly to stale indexed content, not to the generation model — the LLM faithfully generates answers from stale retrieved passages.