
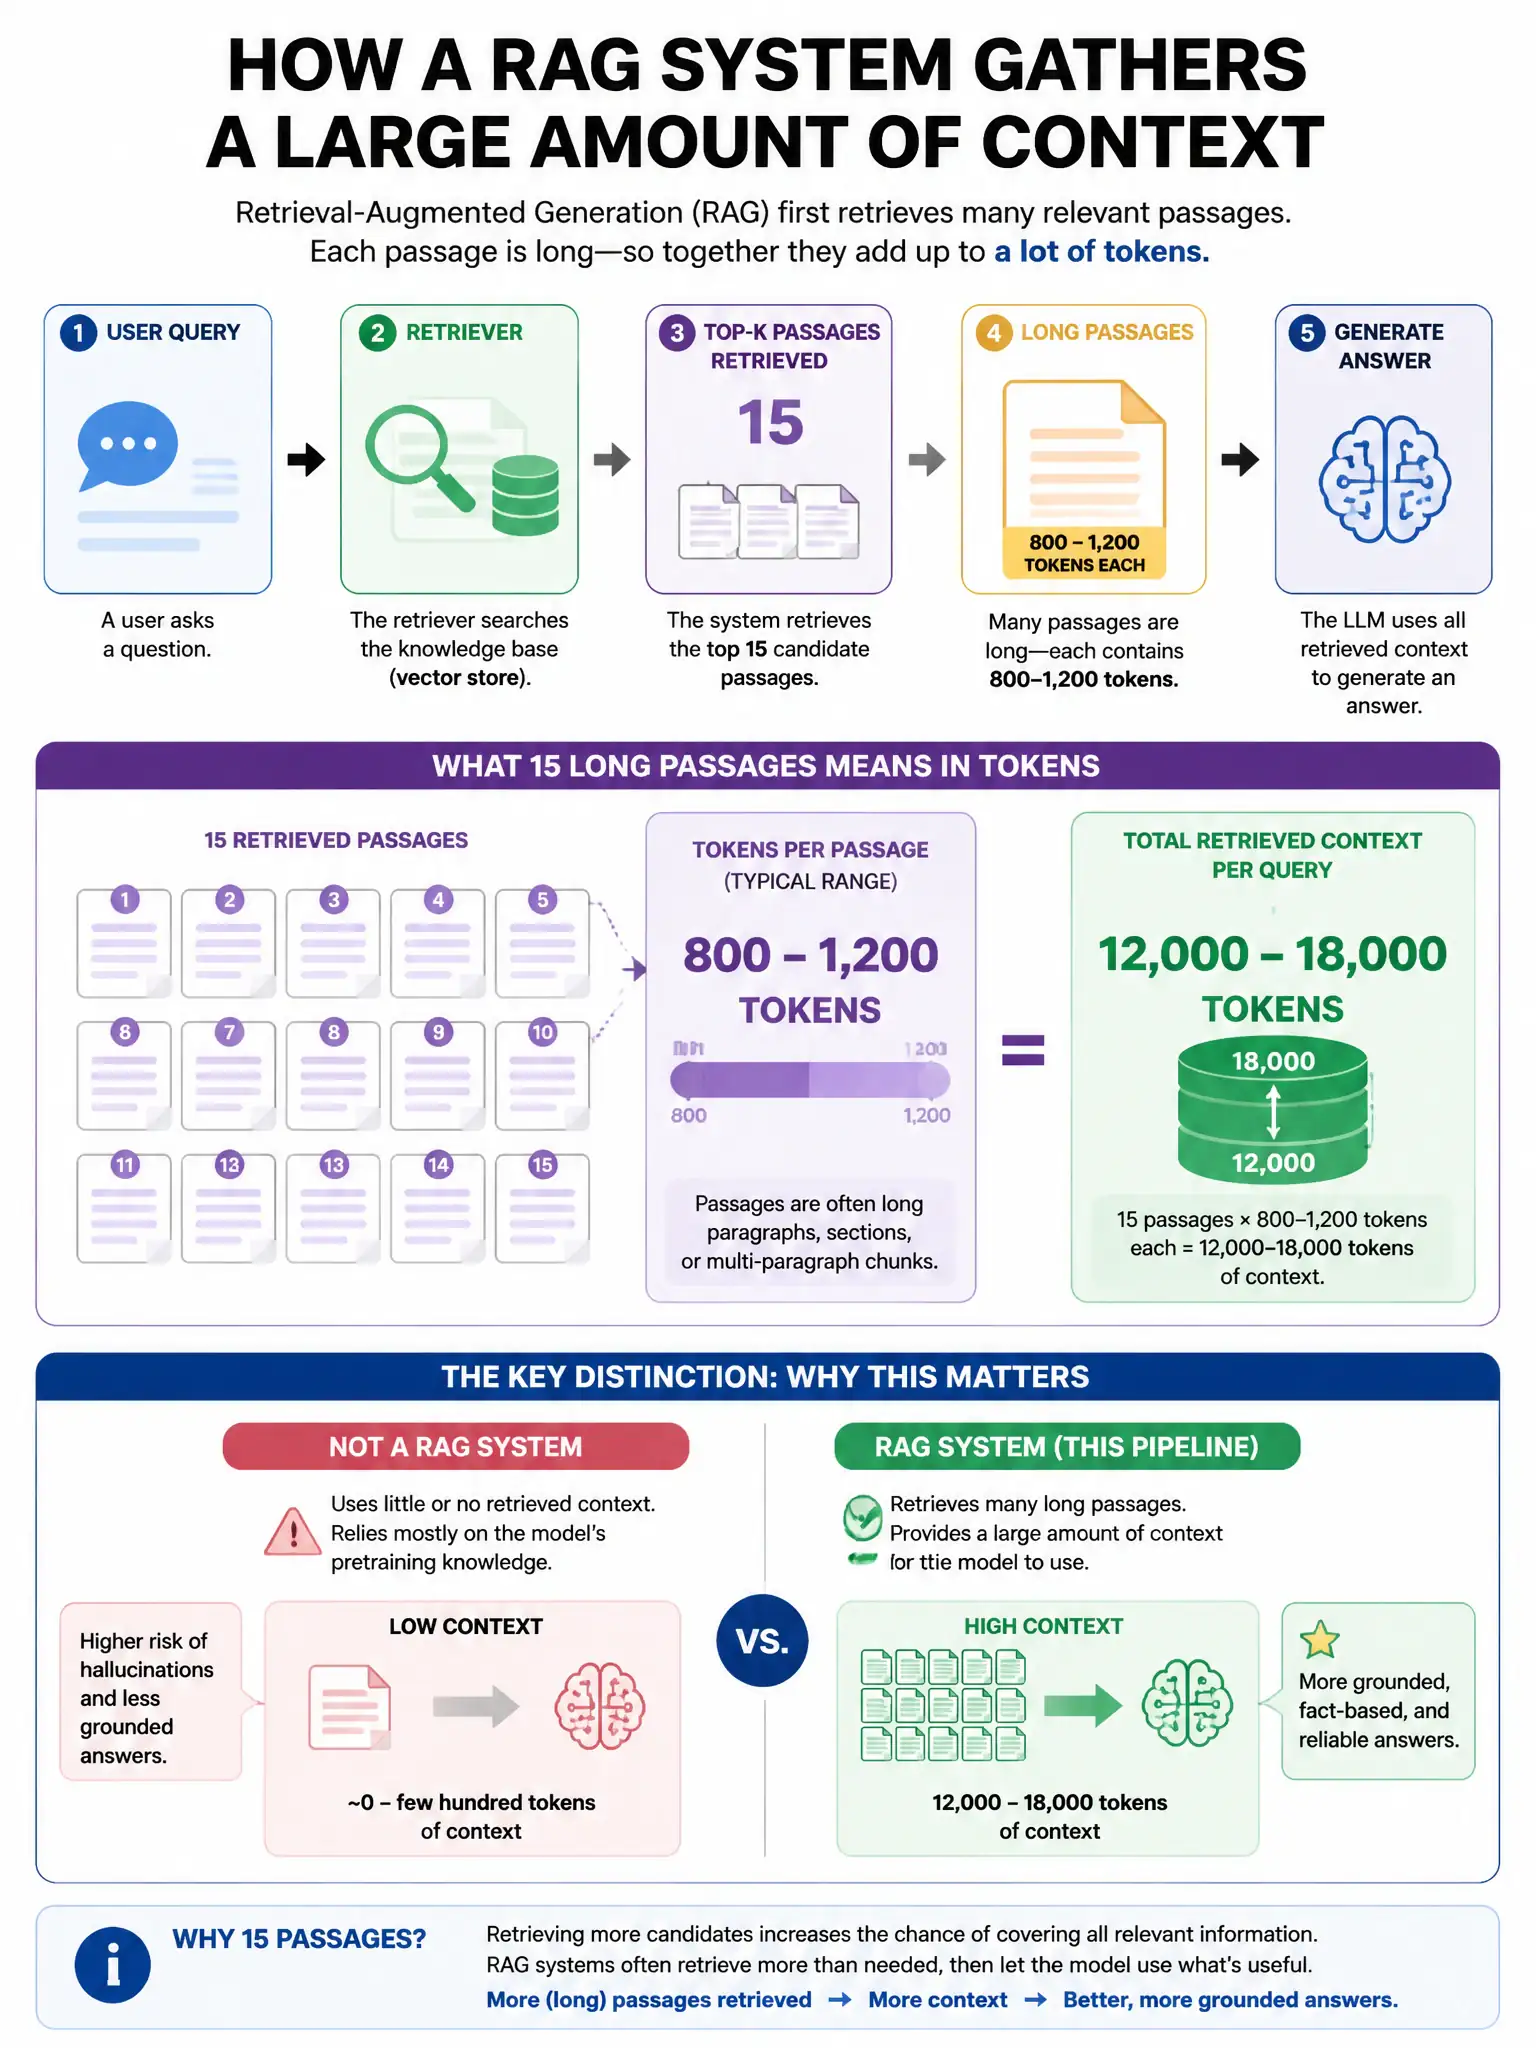
A RAG system retrieves 15 candidate passages for each user query. Many passages are long (800-1,200 tokens each), resulting in 12,000-18,000 tokens of retrieved context per query. The retrieved context is often relevant but repetitive, with multiple passages covering the same topic with slight variations. How should the architect apply contextual compression to improve both efficiency and answer quality?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want to compress the retrieved context after retrieval by using a smaller, cheaper model to pull only the query-relevant sentences, then deduplicate near-identical spans. That cuts token bloat while keeping the useful parts, and it removes repetitive noise that can hurt answer quality.
Full Explanation
The correct approach is to apply an LLM-based contextual compression step after retrieval: use a smaller, cheaper model (for example, Haiku) to extract only the sentences from each passage that are directly relevant to the query, then deduplicate near-identical extracted spans before assembling the final context. This directly addresses both the token efficiency problem and the quality problem. The smaller model can perform extraction efficiently, and deduplication removes redundant coverage that adds noise without adding information. This is a well-established RAG optimization pattern. Truncating each retrieved passage to its first 200 tokens is wrong because it assumes document structure that does not hold across all document types — the relevant information for a given query may appear anywhere in the passage, not only at the start. Increasing chunk size during indexing is wrong because it actually worsens the repetition problem by making chunks less topically focused, and it does not address existing indexed content. Reducing the number of retrieved passages from 15 to 5 is wrong because it addresses token consumption by retrieving less, but also reduces recall — relevant passages at positions 6-15 would be missed. This trades an efficiency problem for a coverage problem.