
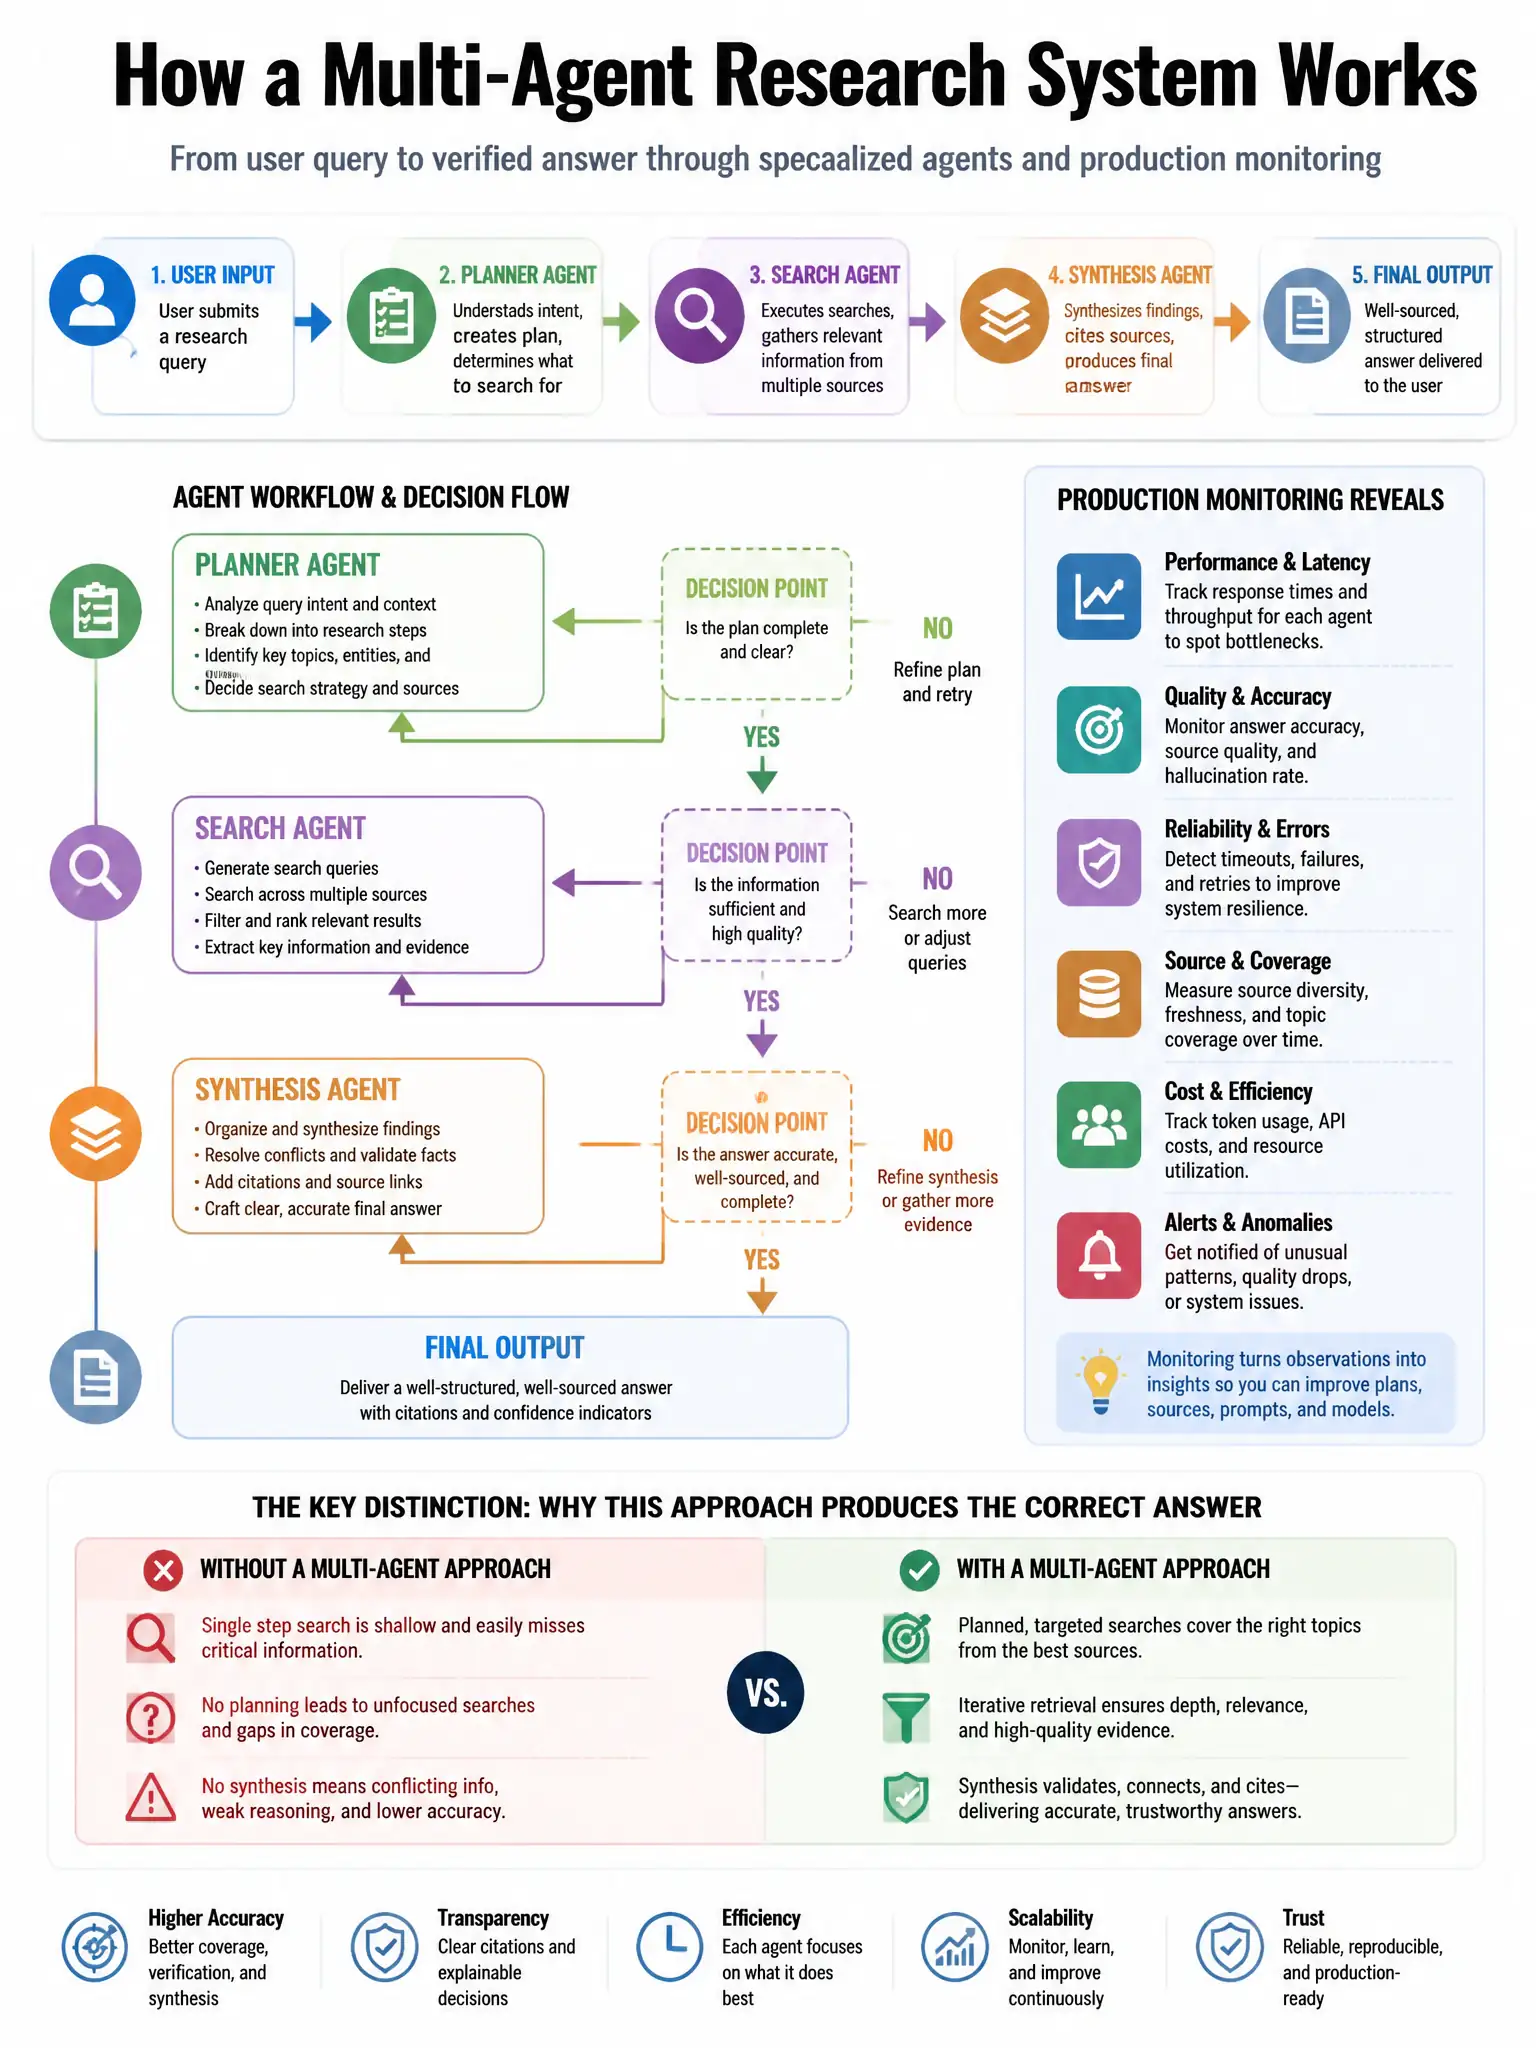
Your multi-agent research system processes user queries by routing them through a planner agent, a search agent, and a synthesis agent in sequence. Production monitoring reveals that the search agent occasionally takes 45+ seconds and sometimes times out entirely. How should the system implement graceful degradation for this failure mode?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal - you want a circuit breaker with a degraded fallback. When search fails or times out, synthesis keeps going with internal knowledge and planner context, clearly marking the answer as unverified or potentially outdated. That gives you value without pretending the result is fully verified.
Full Explanation
The circuit-breaker fallback approach is correct because a circuit breaker with a degraded fallback mode is the standard pattern for resilient multi-agent systems. When the search agent fails, rather than collapsing the entire pipeline, the synthesis agent can provide a response using only its internal knowledge and the planner's decomposition context - clearly labeled as unverified or potentially outdated - which provides value while being transparent about its limitations. This maintains system availability at a reduced quality level rather than complete unavailability. The timeout-and-retry approach is wrong because waiting up to 360 seconds (120 seconds times 3 retries) on a slow search agent creates unacceptable user-facing latency, and treating persistent timeouts as manual-intervention events is not a scalable operational model. The terminate-pipeline approach is wrong because for research queries, a partial response with caveats is generally more valuable than a null response - users can evaluate incomplete information and decide whether to re-query. The synchronous external search service approach is wrong because the latency characteristic of the search agent is an operational problem, not an architectural reason to eliminate agent-based components from the pipeline entirely.