
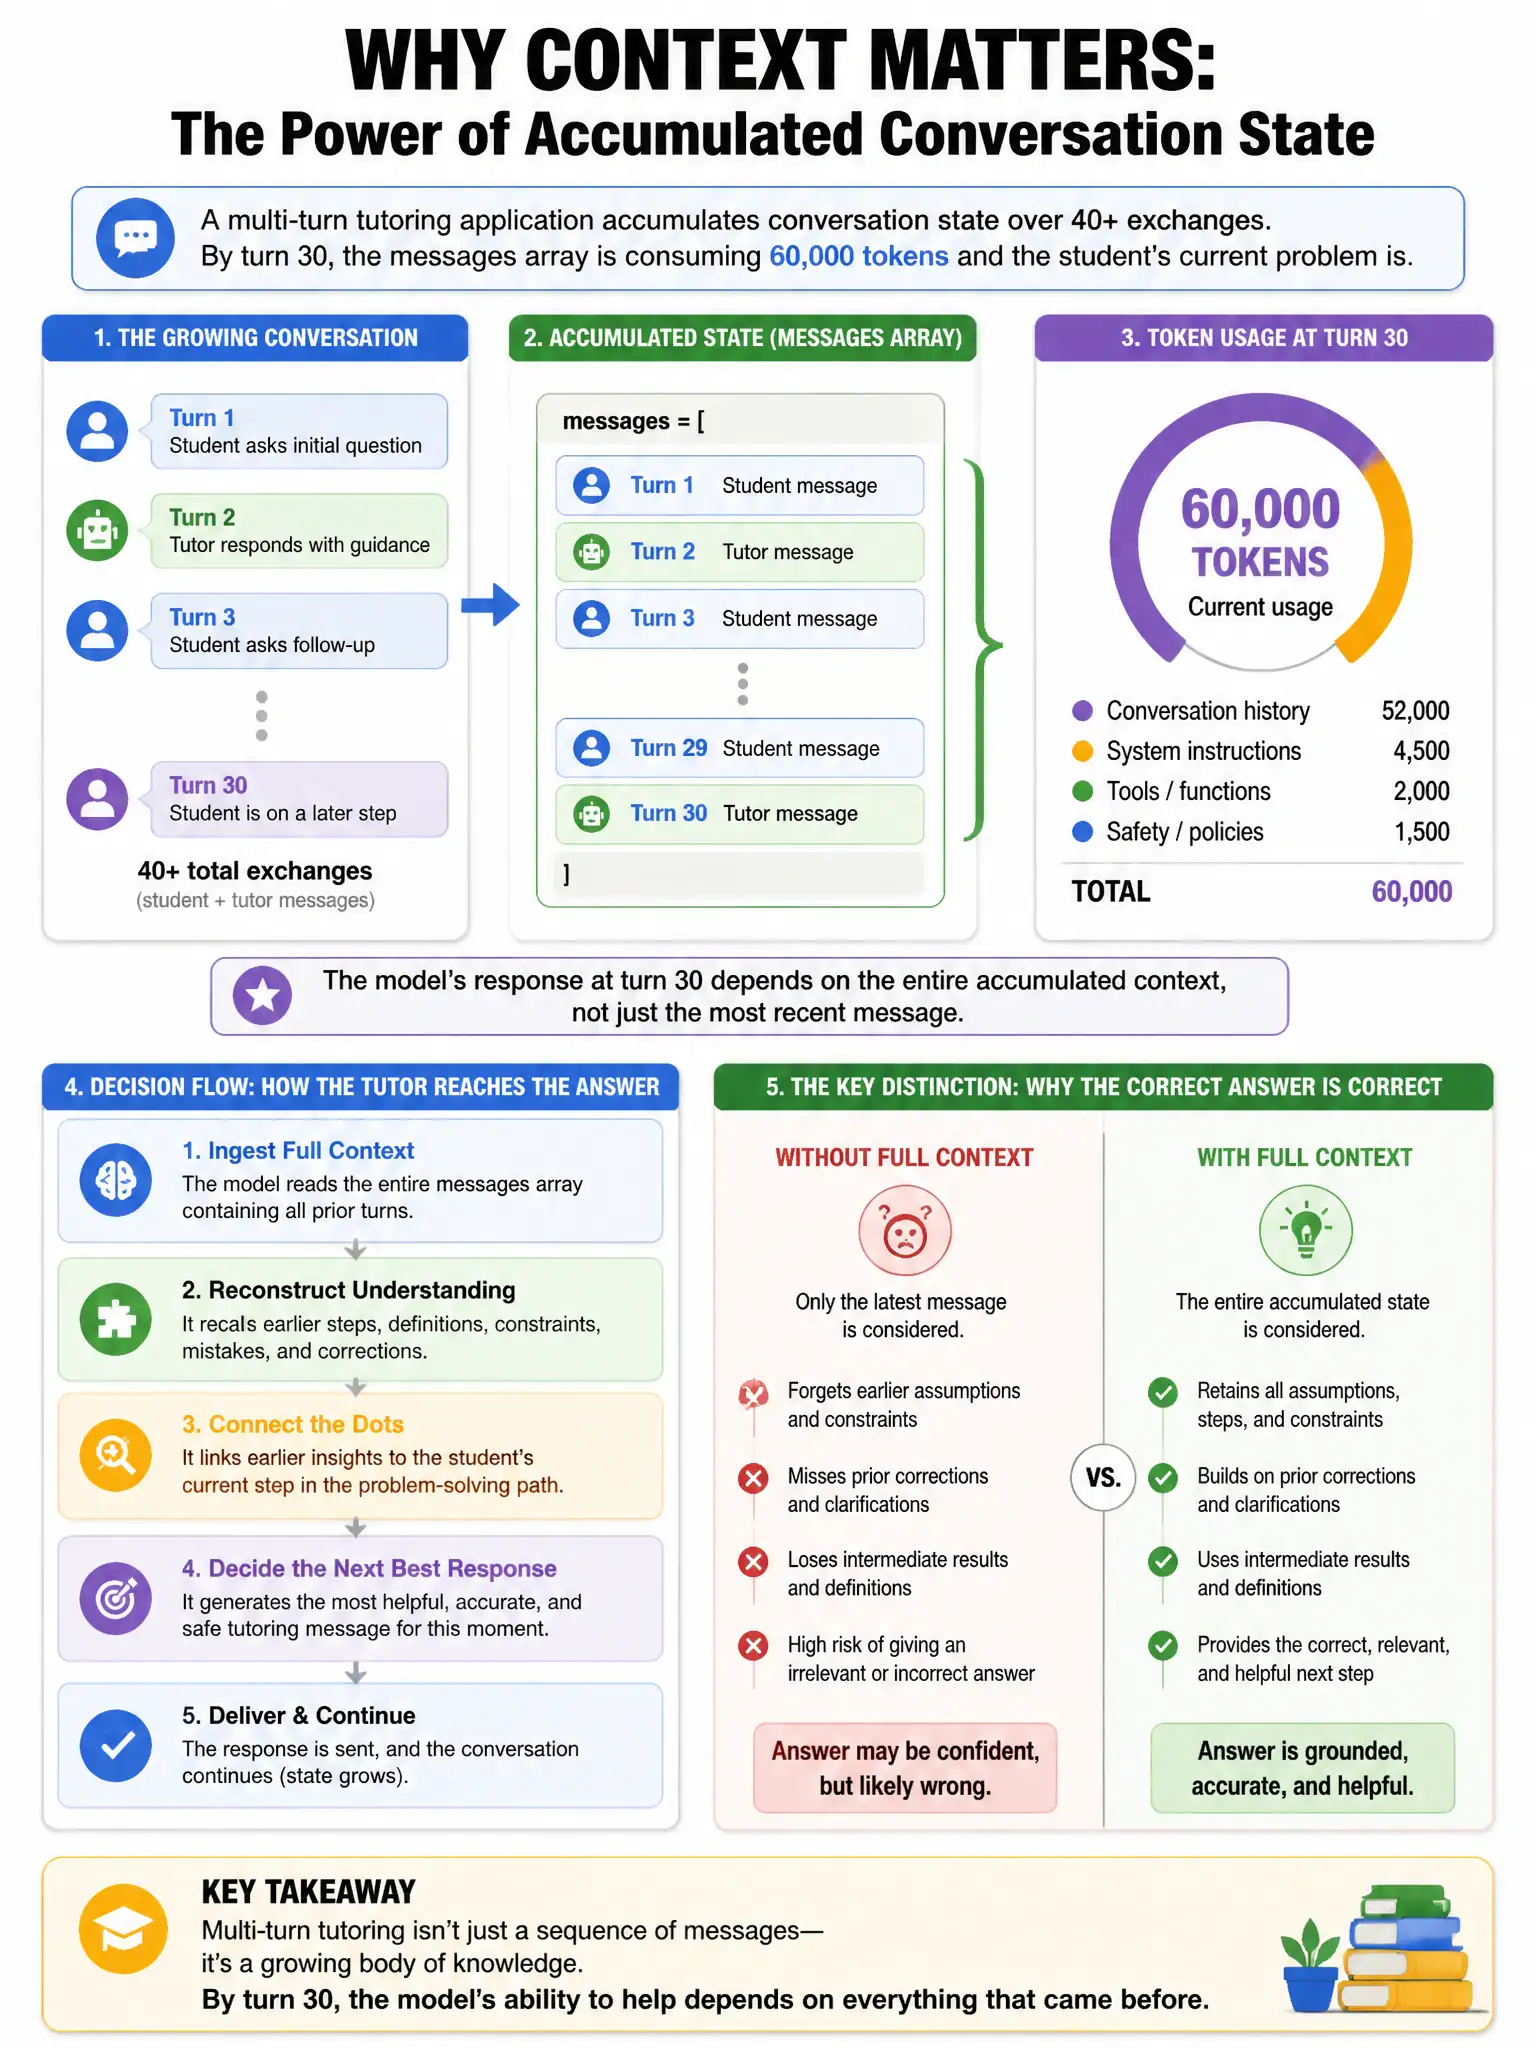
A multi-turn tutoring application accumulates conversation state over 40+ exchanges. By turn 30, the messages array is consuming 60,000 tokens and the student's current problem is only 5 turns old. The architect wants to compress old conversation state without losing pedagogically important context (student mistakes, misconceptions corrected, concepts mastered). What is the optimal compression strategy?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — semantic compression is right because it turns old tutoring history into a compact 'student model' summary that keeps mastered concepts, persistent errors, and current problem state. You replace stale raw messages with that structured summary while keeping recent exchanges, so the context stays bounded without losing pedagogically important detail.
Full Explanation
The optimal strategy is semantic compression: have Claude produce a structured 'student model' summary after every 10 turns, capturing mastered concepts, persistent errors, and current problem state, then replace the compressed messages with this summary block while retaining only recent raw exchanges. This preserves the pedagogically critical information — what the student has learned, what errors they persistently make, and where they currently are — in a compact structured format, while keeping the messages array bounded and actionable for the next tutoring step. The fixed compression approach that removes every other historical message is wrong because it breaks the logical flow of multi-turn reasoning; questions can lose their answers and explanations can lose their context, producing an incoherent conversation history. The approach that discards all messages older than the last 10 turns is wrong because earlier turns often contain the origin of a student's misconception or proof that they mastered a prerequisite concept, so removing them loses valuable diagnostic information. The approach that increases the temperature parameter to 0.9 is wrong because temperature controls output randomness and has no relationship to context dependency or memory compression.