
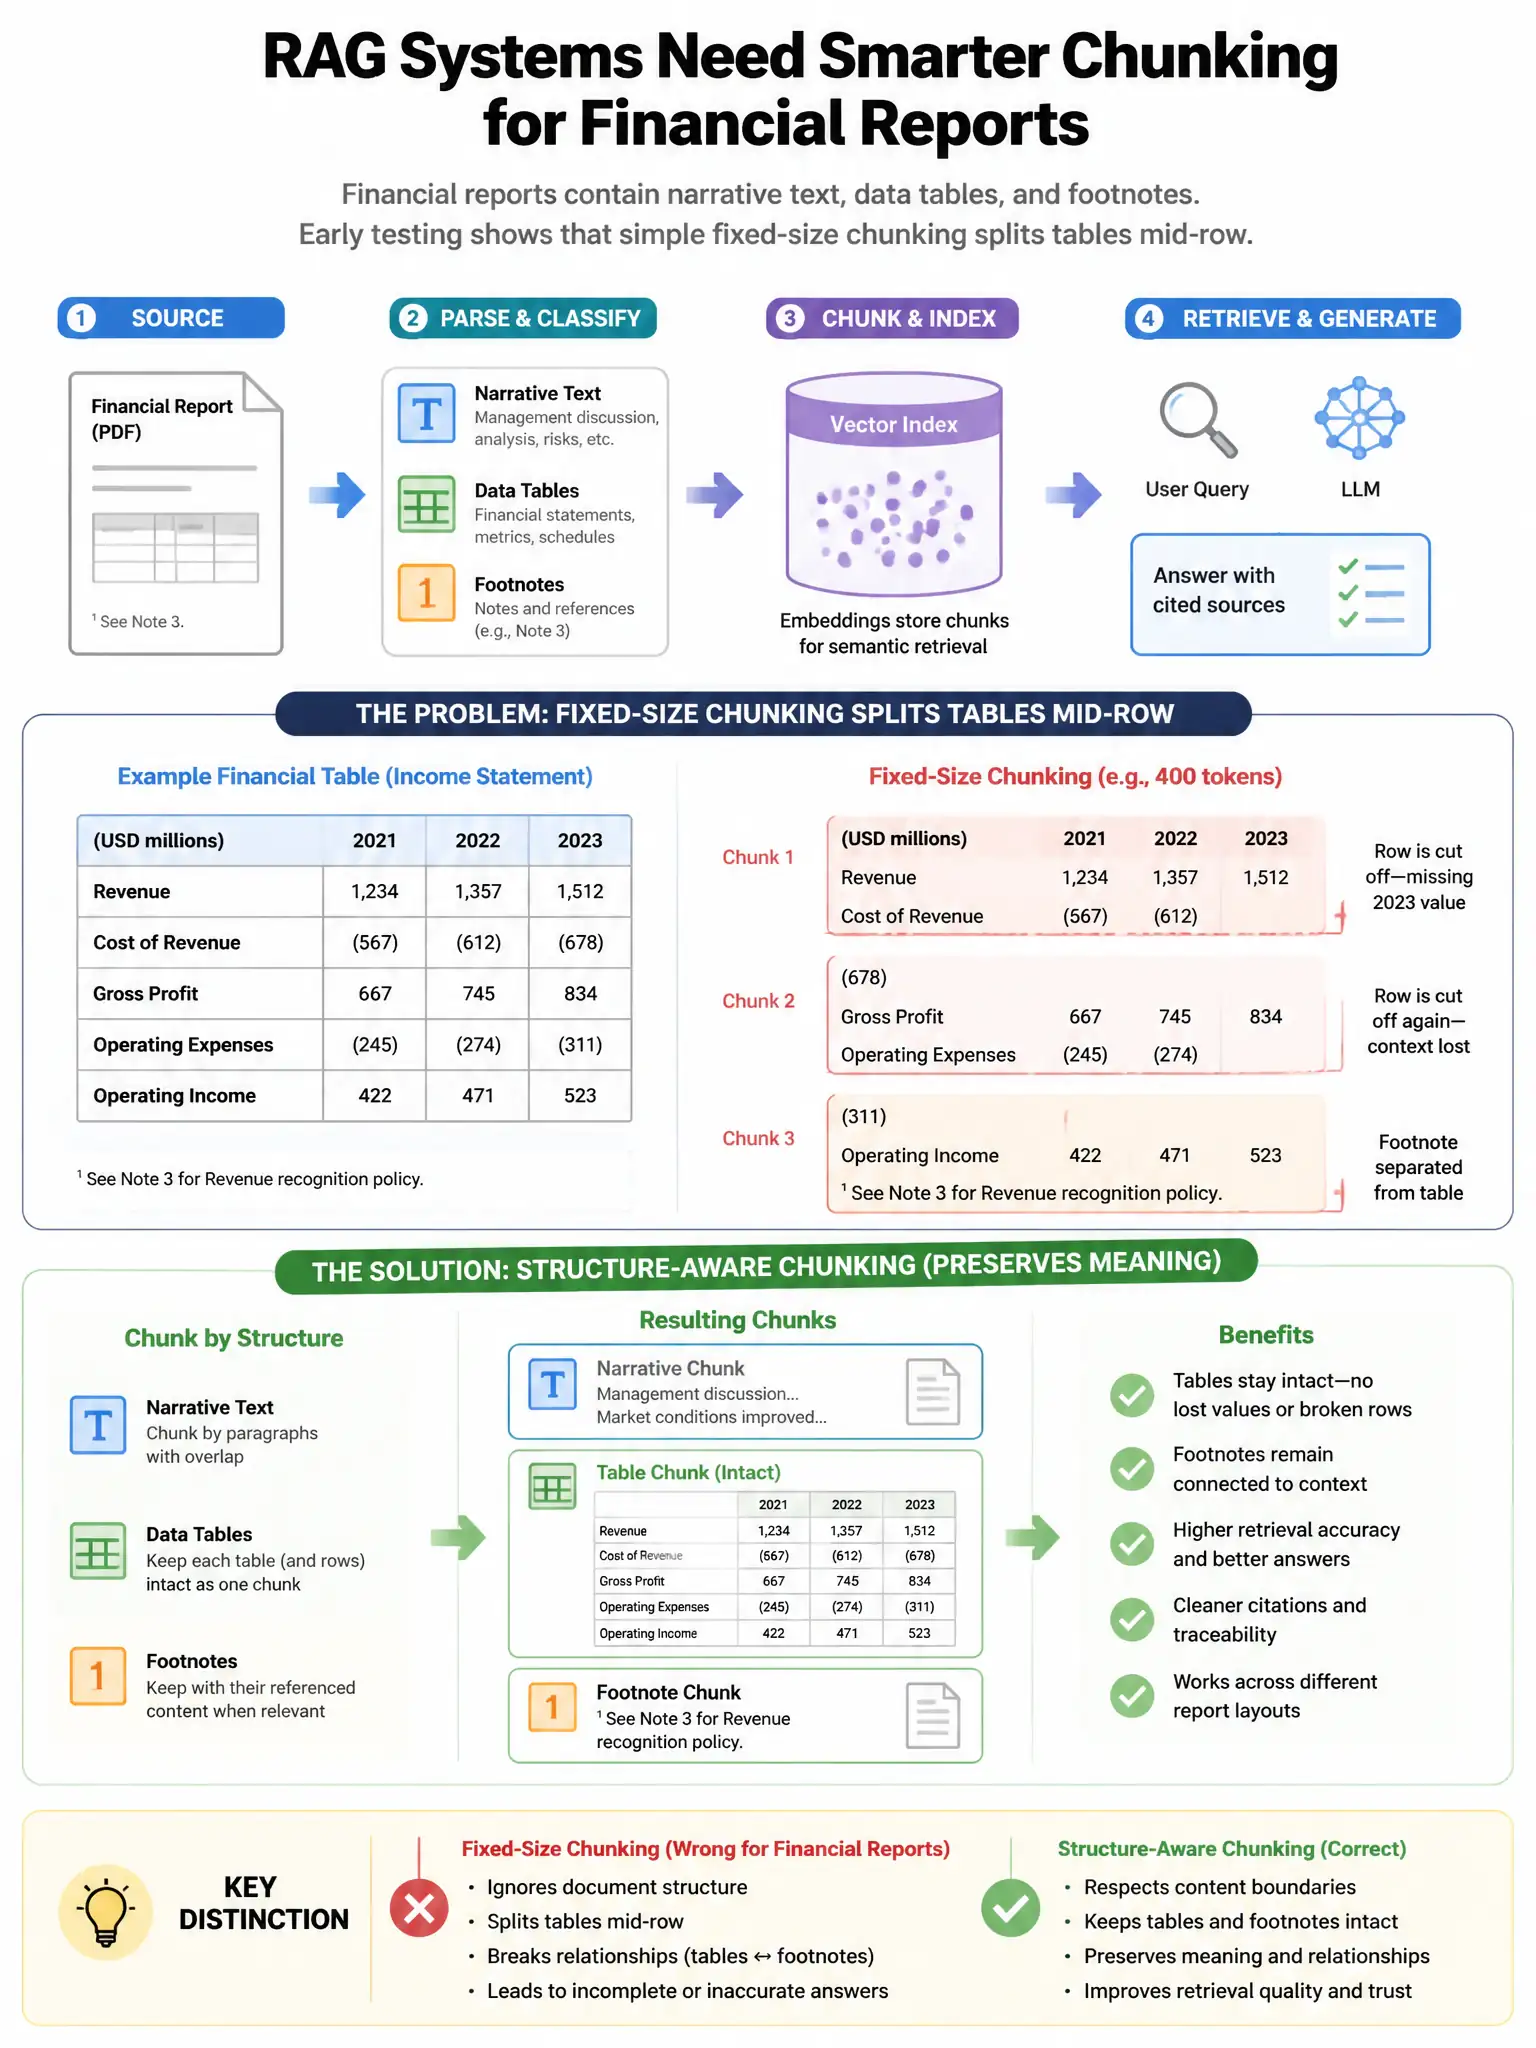
A RAG system indexes financial reports that contain narrative text sections, data tables, and footnotes. Early testing shows that simple fixed-size chunking splits tables mid-row and separates footnotes from the text that references them, causing Claude to misinterpret financial figures. What chunking strategy preserves semantic integrity for this document type?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — structure-aware chunking is correct because financial documents have rich structure that fixed-size chunking destroys. Tables are semantic units where row/column relationships are essential for interpreting figures, and footnotes provide qualifications that change the meaning of the figures they annotate. Parsing boundaries and attaching metadata preserves the semantic integrity you need for accurate financial interpretation.
Full Explanation
Structure-aware chunking is correct because financial documents have rich structure that fixed-size chunking destroys: tables are semantic units where row/column relationships are essential for interpreting figures; footnotes provide qualifications that change the meaning of the figures they annotate. Structure-aware chunking that respects these boundaries and attaches metadata (section headers, table captions) preserves the semantic integrity needed for accurate financial interpretation. The approach of reducing chunk size to 128 tokens is wrong because smaller chunks make table splitting worse, not better — smaller chunks are more likely to split mid-table, not less; and tables may exceed 128 tokens. The approach of using overlapping chunks with 50% overlap is wrong because overlapping chunks duplicate content (increasing index size and retrieval noise) and still split table rows mid-entry — overlap does not create semantic boundaries, only redundant coverage. The approach of converting all tables to natural language descriptions before chunking is wrong because it loses the structured data format that makes table retrieval valuable — Claude can interpret table structure visually or through JSON; prose conversion loses precision and adds ambiguity.