
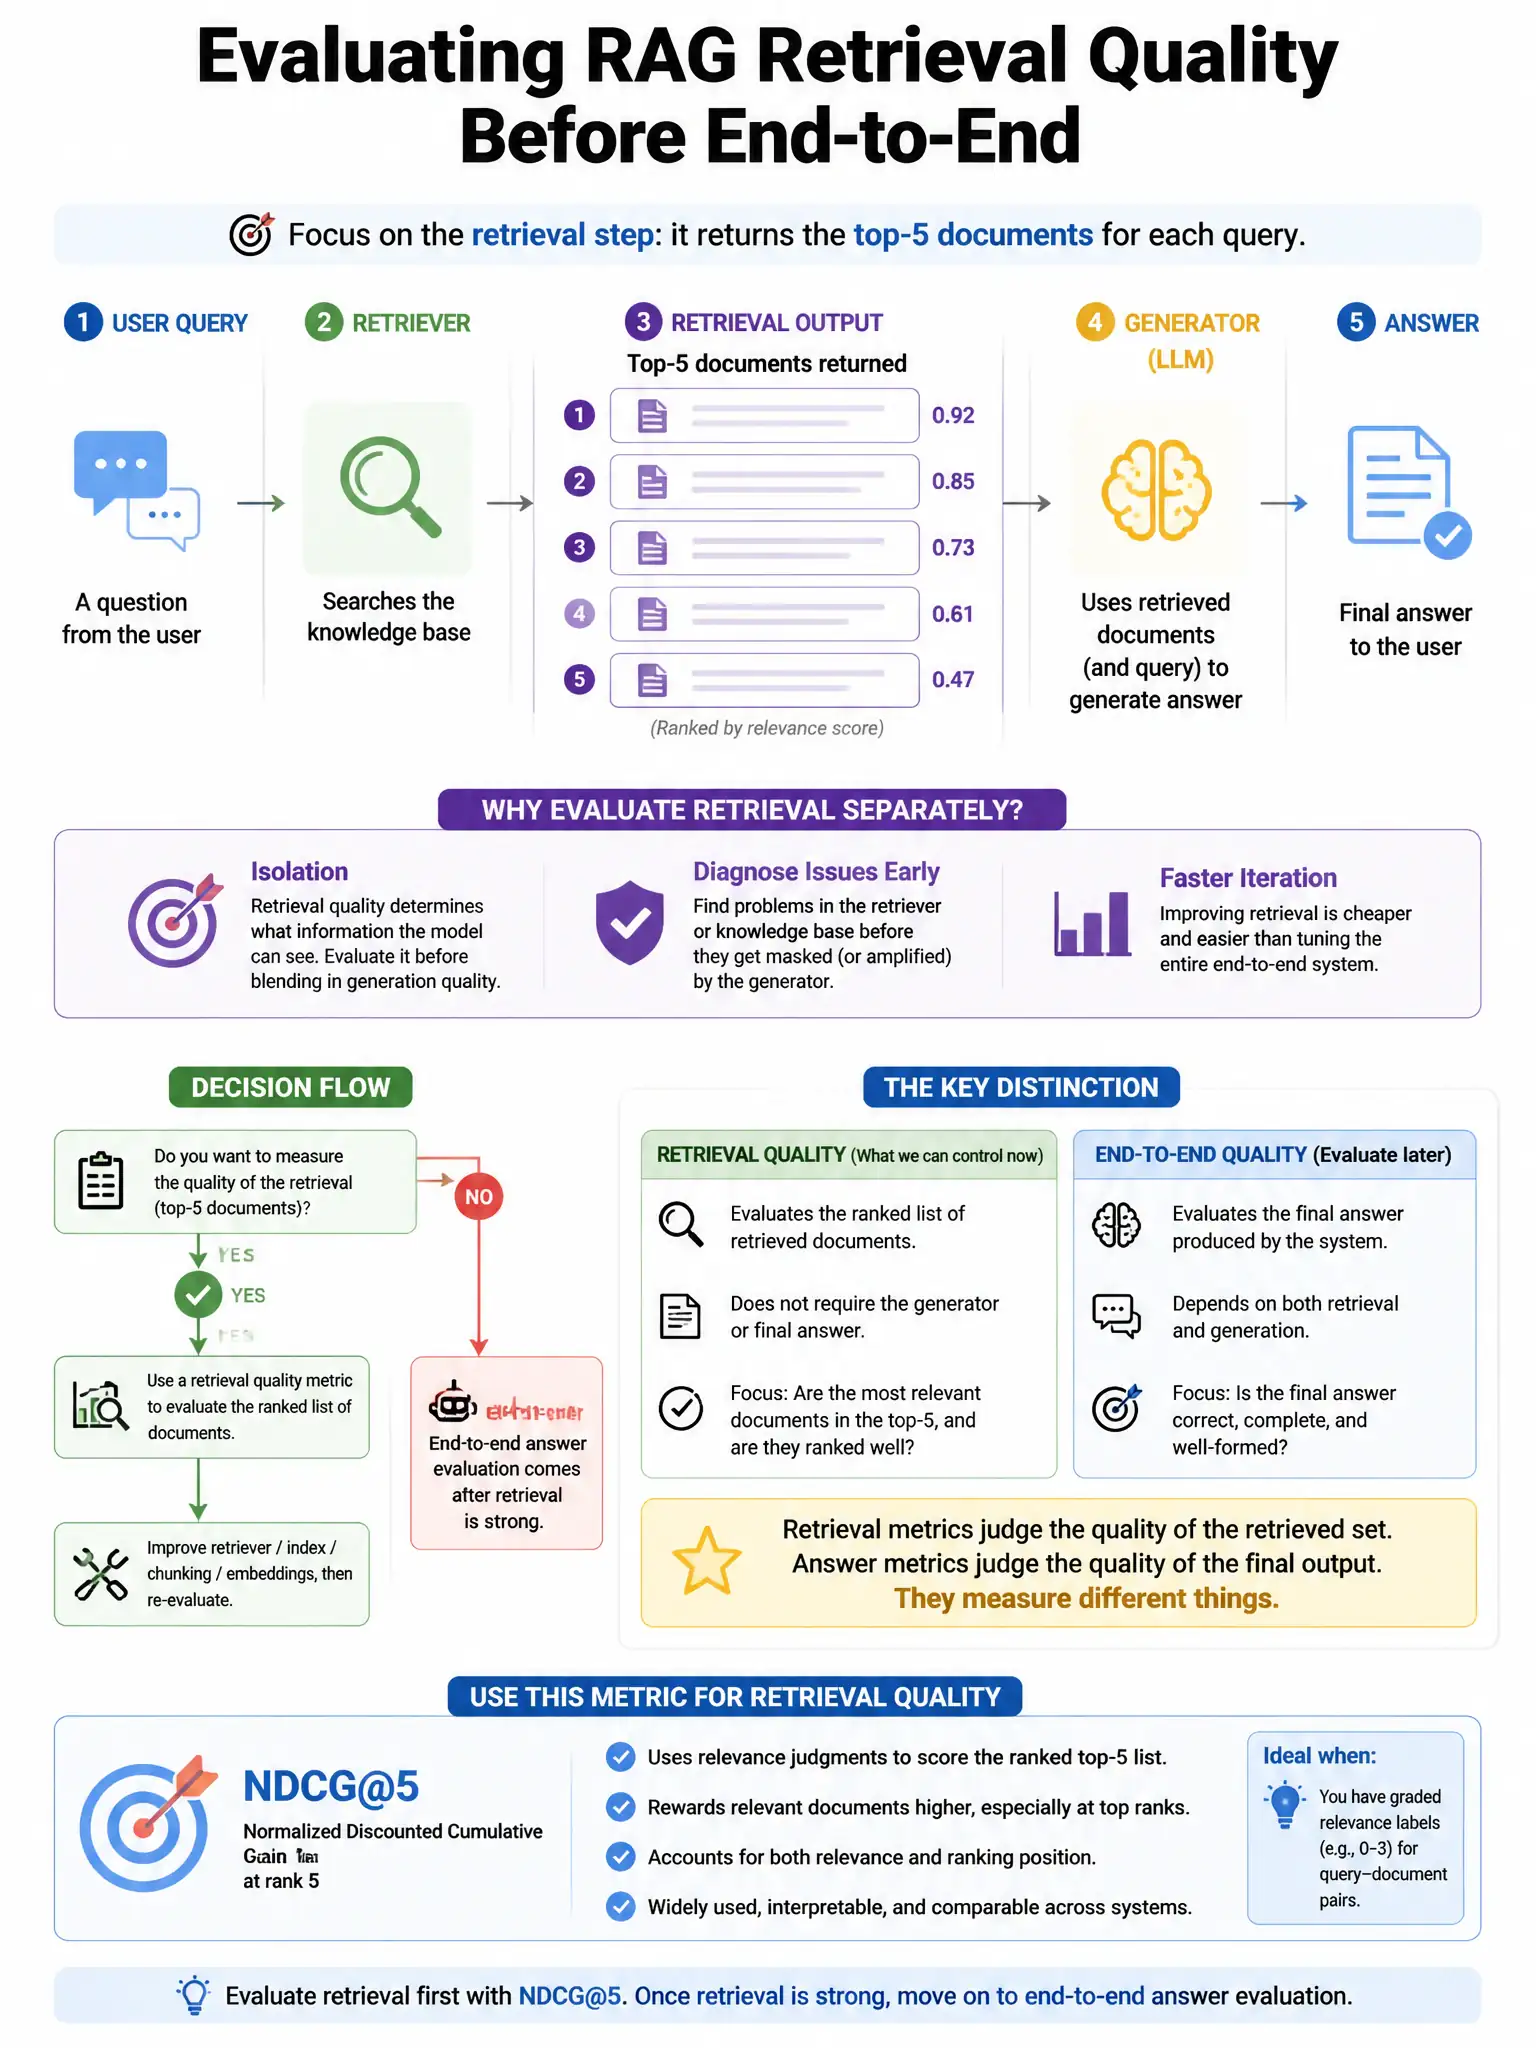
A RAG system's retrieval component returns the top-5 documents for each query. The team wants to measure retrieval quality before evaluating end-to-end answer quality. Which metrics provide the most complete picture of retrieval performance?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want Precision@5 and Recall@5 together, because precision tells you whether the retrieved documents are relevant and recall tells you whether you captured all the relevant information. Manually labeled relevance data gives you ground truth for objective measurement.
Full Explanation
The correct approach is to measure Precision@5 and Recall@5 together, using a manually labeled query-document relevance dataset. Precision@5 measures whether the retrieved documents are relevant, which matters when context length limits the number of documents passed to Claude. Recall@5 measures whether all relevant information was captured, which matters for completeness. Together, they provide complementary signals: precision guards against noisy context, and recall guards against missing context. The manually labeled dataset provides ground truth for objective measurement. The end-to-end answer accuracy option is wrong because it confounds retrieval quality with generation quality — good retrieval with poor prompting can still produce wrong answers, and poor retrieval with very capable generation can sometimes produce correct answers through memorized knowledge. The latency and throughput option is wrong because those metrics measure system performance, not retrieval relevance quality — a fast retriever returning irrelevant documents is worse than a slower one returning relevant documents. The Hit Rate@5 option is wrong because counting queries where at least one relevant document appears in the top-5 is a necessary condition but insufficient — a system returning one relevant and four irrelevant documents scores the same as one returning five relevant documents, masking precision differences.