
An agentic system calls an external REST API as a tool. The API returns HTTP 503 (Service Unavailable). The agent must decide how to proceed. What is the correct error handling pattern in the orchestration layer?
Select an answer to reveal the explanation.
Short Explanation
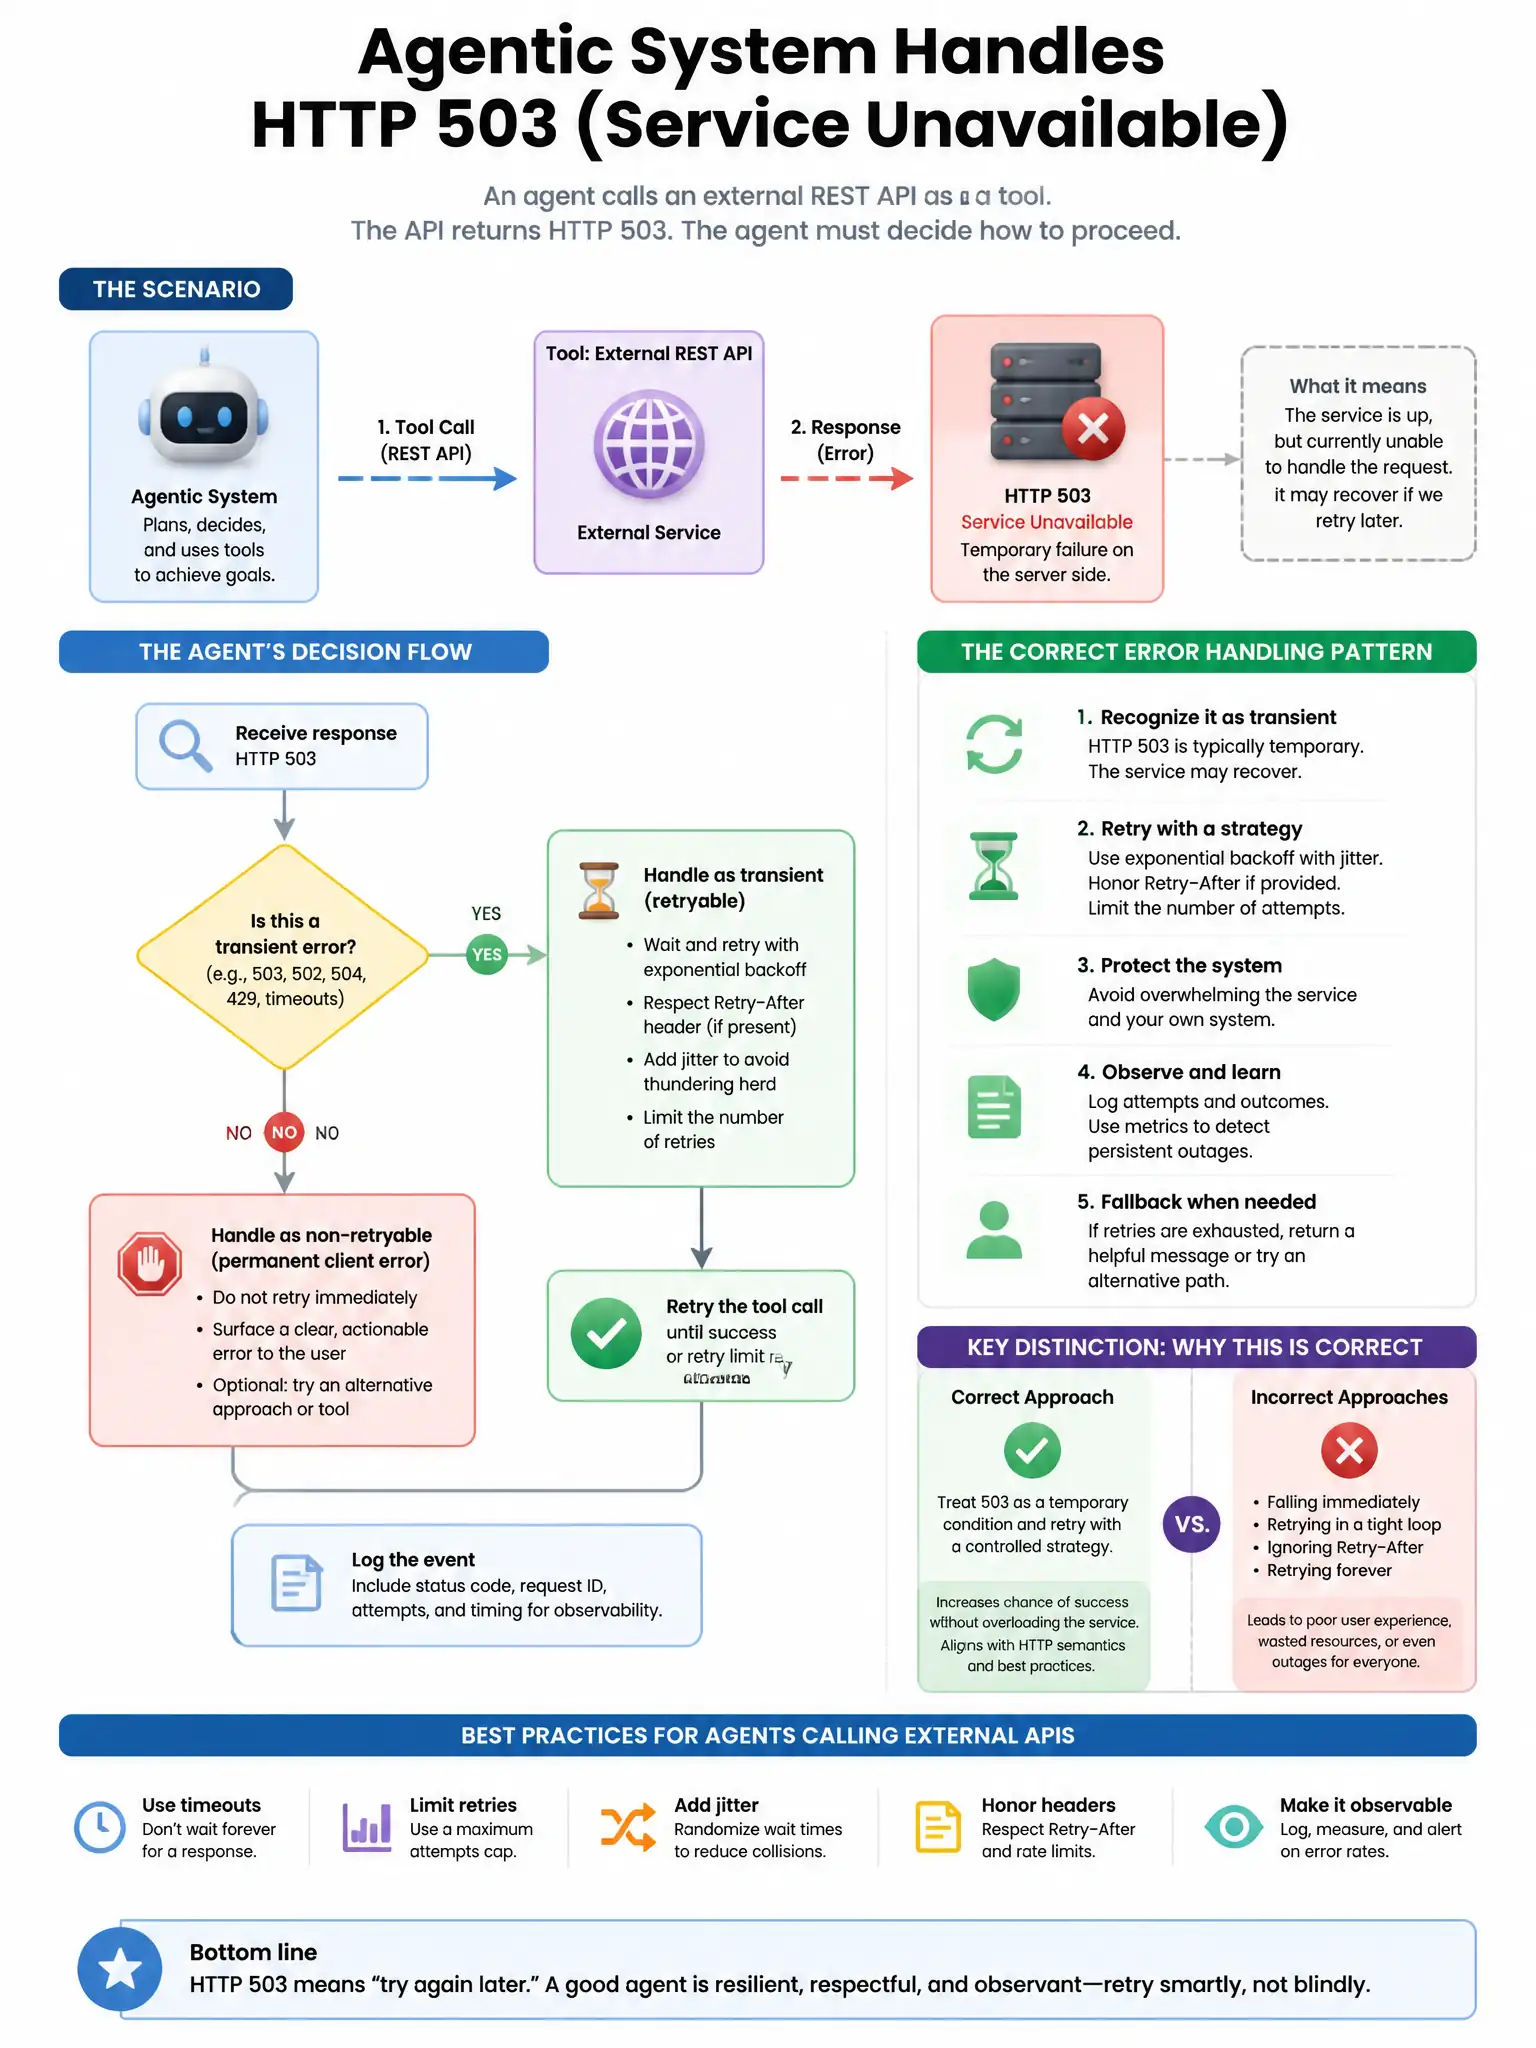
Here's the deal — you should use exponential backoff for 503 and 429, then return a structured error tool_result if retries run out. That gives the service time to recover and gives Claude enough context to choose an alternative, tell the user, or degrade gracefully.
Full Explanation
The correct pattern is exponential backoff retry with delays such as 1s, 2s, and 4s for retriable errors like 503 and 429, plus a maximum retry count and timeout. The 503 status is a retriable transient error, and exponential backoff gives the downstream service time to recover without flooding it with requests. If retries are exhausted, return a structured error tool_result to Claude that includes the error type and retry count, so Claude can make an informed decision about alternatives, inform the user, or gracefully degrade. Retrying immediately three times with no delay is wrong because immediate retries without delay can overwhelm a service that is already under load; the 503 status specifically indicates the service needs time to recover, so immediate retries worsen the situation. Returning the 503 error directly to Claude as a tool_result is wrong because it wastes an opportunity to handle transient failures transparently; many 503s resolve within 1-2 seconds, and discarding them on first occurrence degrades reliability. Marking the tool as unavailable and continuing the agent loop without it, silently skipping the tool call, is wrong because it produces an agent that operates with incomplete information; Claude may generate an answer assuming the tool succeeded, leading to incorrect outputs.