
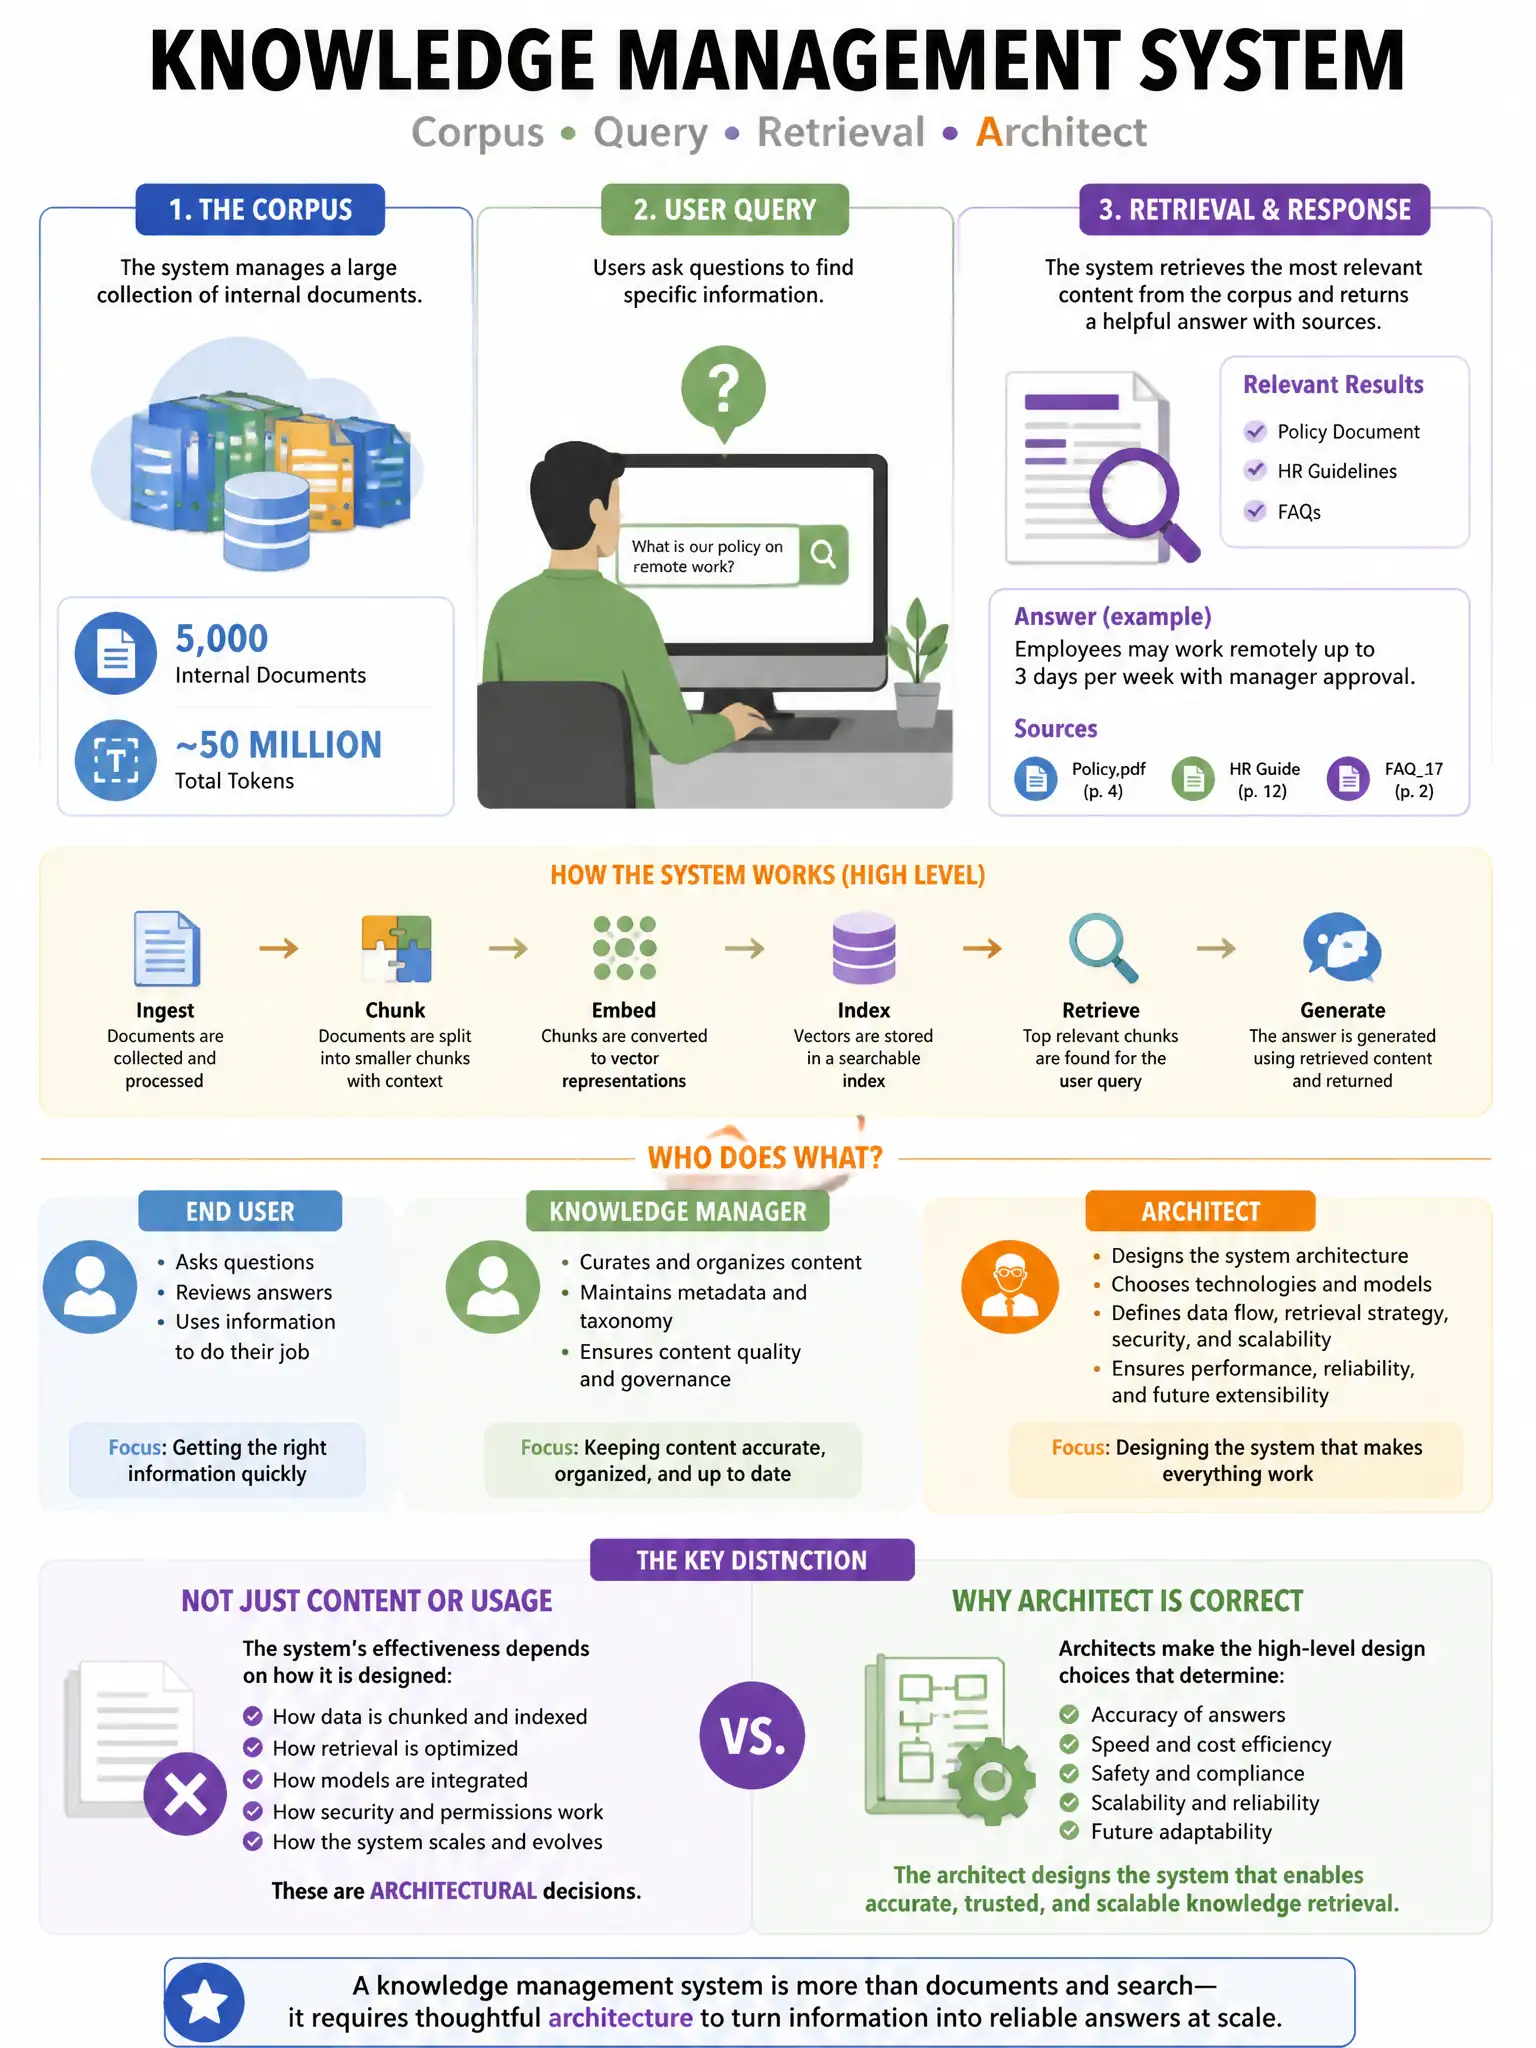
A knowledge management system has a corpus of 5,000 internal documents totaling approximately 50 million tokens. Users query the corpus for specific information. An architect is deciding between two approaches: (A) stuff all documents into Claude's context window using a very large context model, or (B) implement RAG to retrieve the 5-10 most relevant documents before calling Claude. Which factors most strongly favor approach B?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you should favor the retrieval choice that sends only the 5-10 most relevant documents because 50 million tokens blows past practical context windows, sending only relevant passages slashes cost, and focused context avoids attention dilution. Stuffing everything into one giant context is too expensive and can bury the useful passages in noise.
Full Explanation
The retrieval choice that sends only the 5-10 most relevant documents is correct because three factors converge to favor retrieval-augmented generation: first, 50 million tokens vastly exceeds even the largest commercially available context windows, which are commonly in the 200K to 1M token range; second, per-query cost with context stuffing would be catastrophically expensive, because retrieving 5-10 documents reduces input tokens by 99.9%; third, attention dilution is a documented phenomenon where relevant passages buried in massive context receive less attention weight than when they appear in focused context. The always-stuff-everything choice is wrong because even if a context window large enough existed, stuffing irrelevant documents degrades response quality and is economically prohibitive. The structured-versus-unstructured choice is wrong because document structure, whether structured or unstructured, does not determine the appropriate retrieval architecture; token count and cost are the primary factors. The update-frequency-only choice is wrong because while incremental index updates are a benefit of retrieval-augmented generation for frequently updated corpora, the primary reasons to use retrieval-augmented generation, namely token limits, cost, and attention dilution, apply regardless of update frequency.