
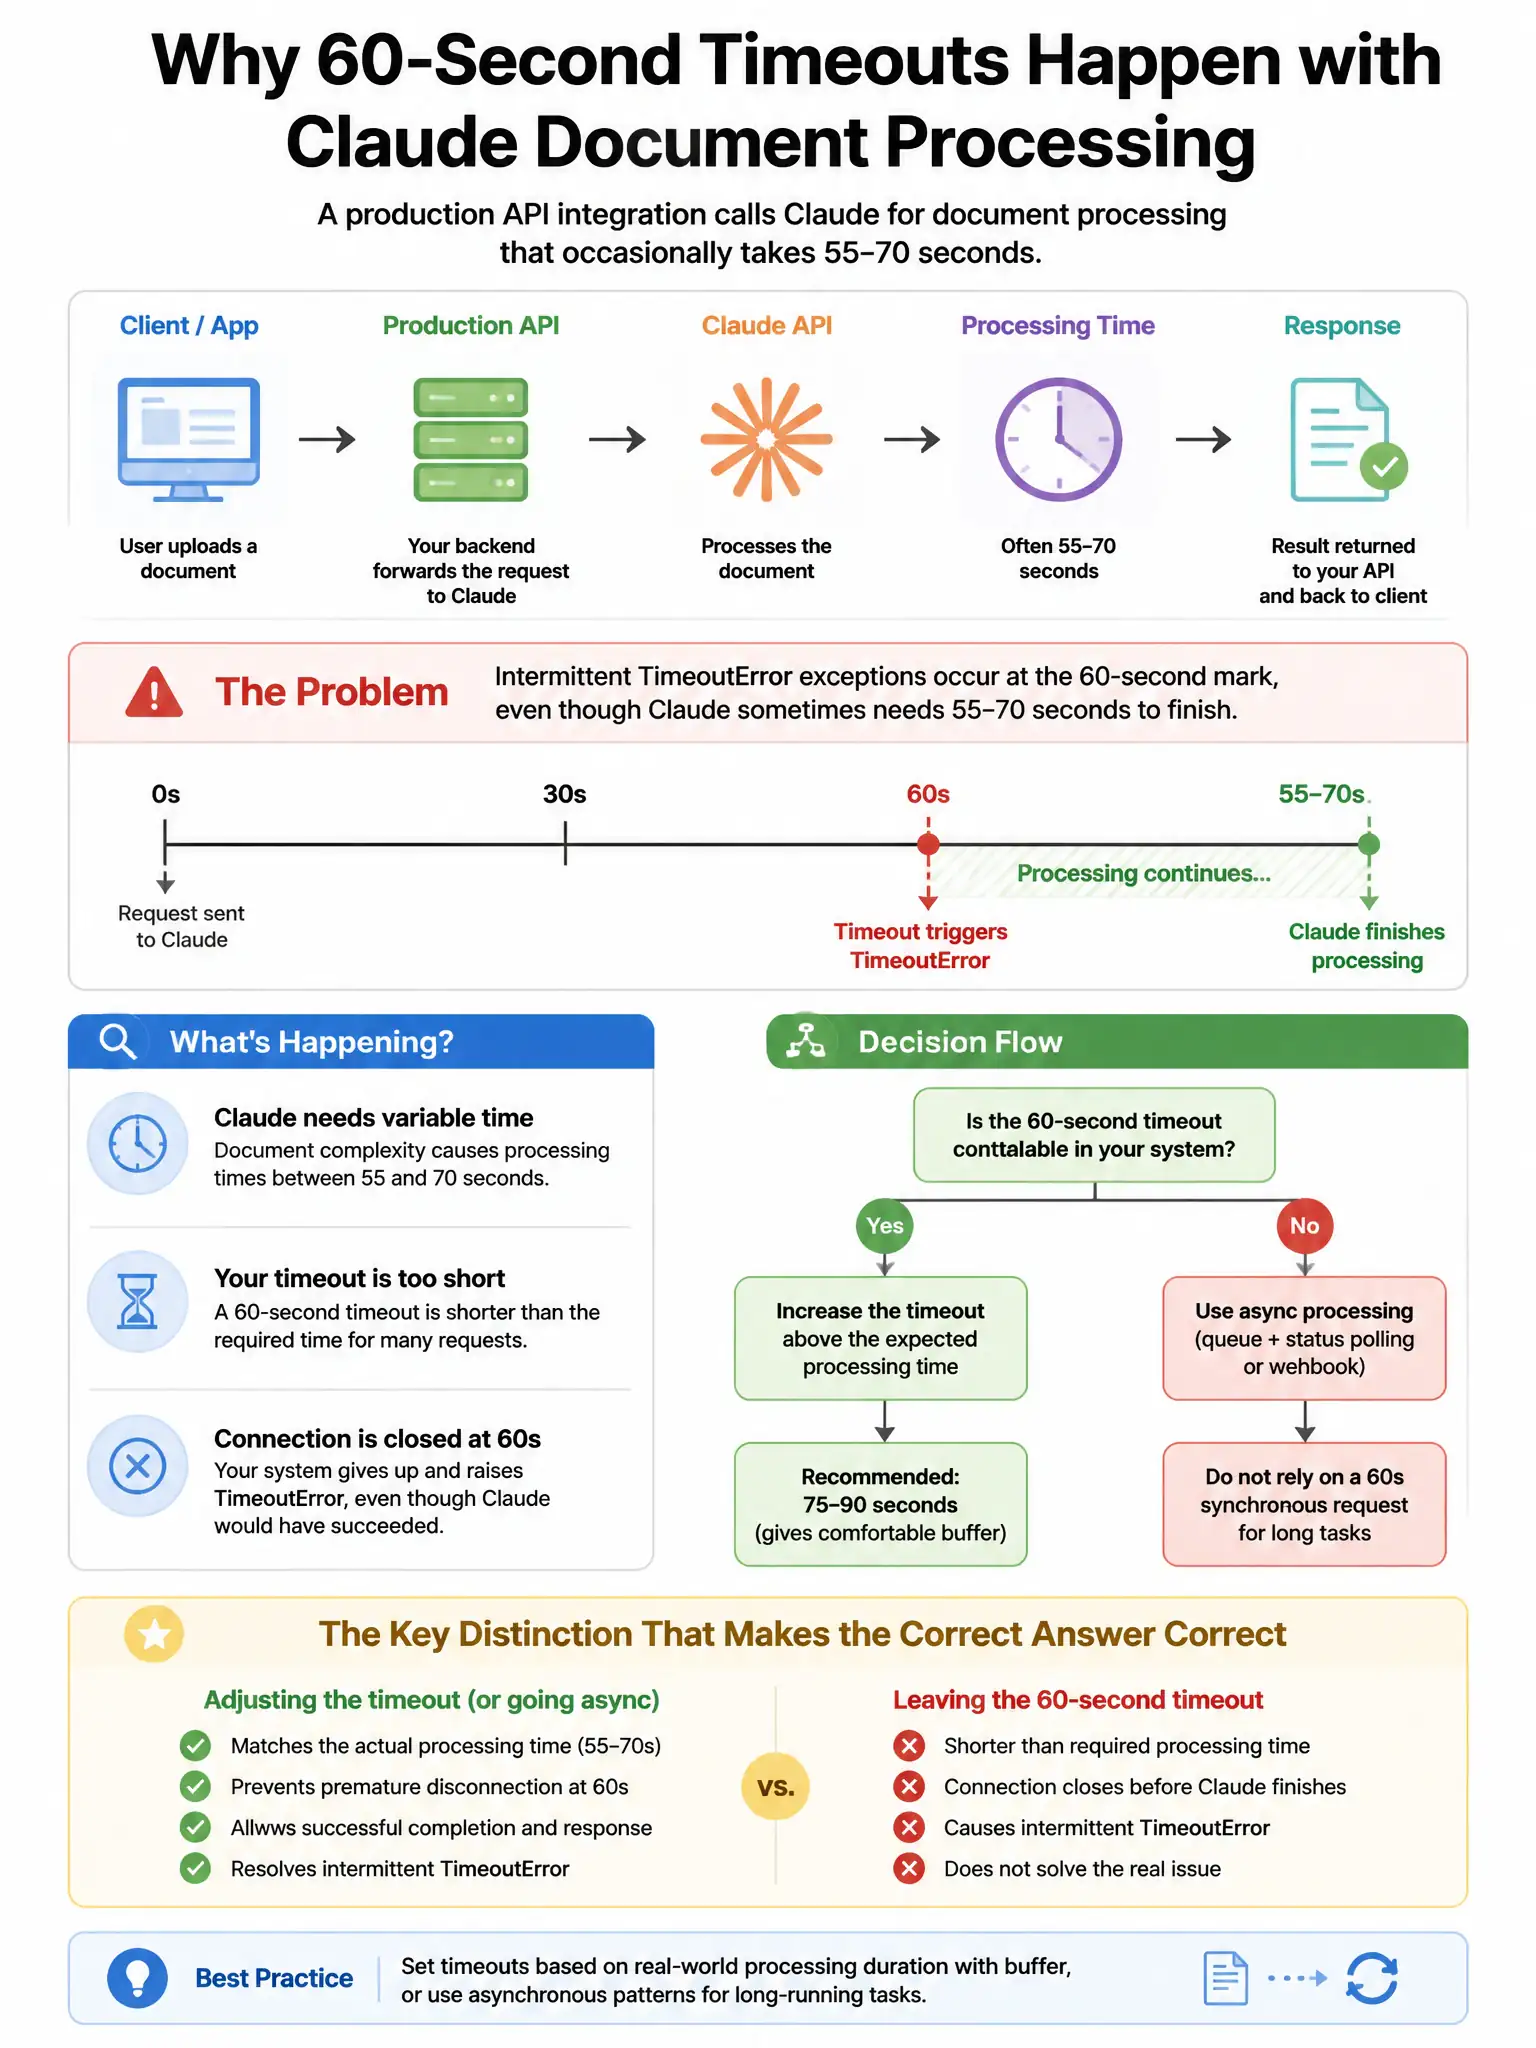
A production API integration calls Claude for document processing that occasionally takes 55–70 seconds. The team reports intermittent TimeoutError exceptions at the 60-second mark. Infrastructure review shows: API gateway timeout = 60s, application server timeout = 90s, HTTP client timeout = 120s. What is the correct fix?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need to refactor to an async pattern: submit requests asynchronously and retrieve results via polling or webhook. That removes the synchronous timeout dependency, so the submit call finishes fast and you get results independently.
Full Explanation
The correct fix is to refactor to an async pattern: submit requests asynchronously and retrieve results via polling or webhook, eliminating the synchronous timeout dependency. The root cause is that synchronous HTTP connections are fundamentally incompatible with processing times that approach or exceed infrastructure timeout limits. With async job submission plus polling or webhook, the connection that submits the job completes in milliseconds, and result retrieval happens independently, so the 55–70 second processing time no longer depends on a single long-lived HTTP connection. The HTTP-client-timeout increase to 180 seconds is wrong because the bottleneck is the API gateway at 60 seconds, not the HTTP client; increasing the client timeout does not affect the gateway. The API-gateway-timeout increase to 90 seconds is wrong because it only shifts the failure point: requests taking 70 seconds would succeed, but any future increase in processing time would hit the new limit, and cascading timeout mismatches across multiple infrastructure layers create maintenance complexity. The retry-logic option is wrong because catching the TimeoutError and immediately retrying the same request starts the entire processing from scratch, doubling or tripling cost and latency without fixing the underlying timeout architecture problem.