
An AI product team is debating when to use claude-3-opus versus claude-3-5-sonnet. A senior architect is asked to define the decision criteria. Which set of criteria correctly identifies use cases that genuinely benefit from Opus over Sonnet?
Select an answer to reveal the explanation.
Short Explanation
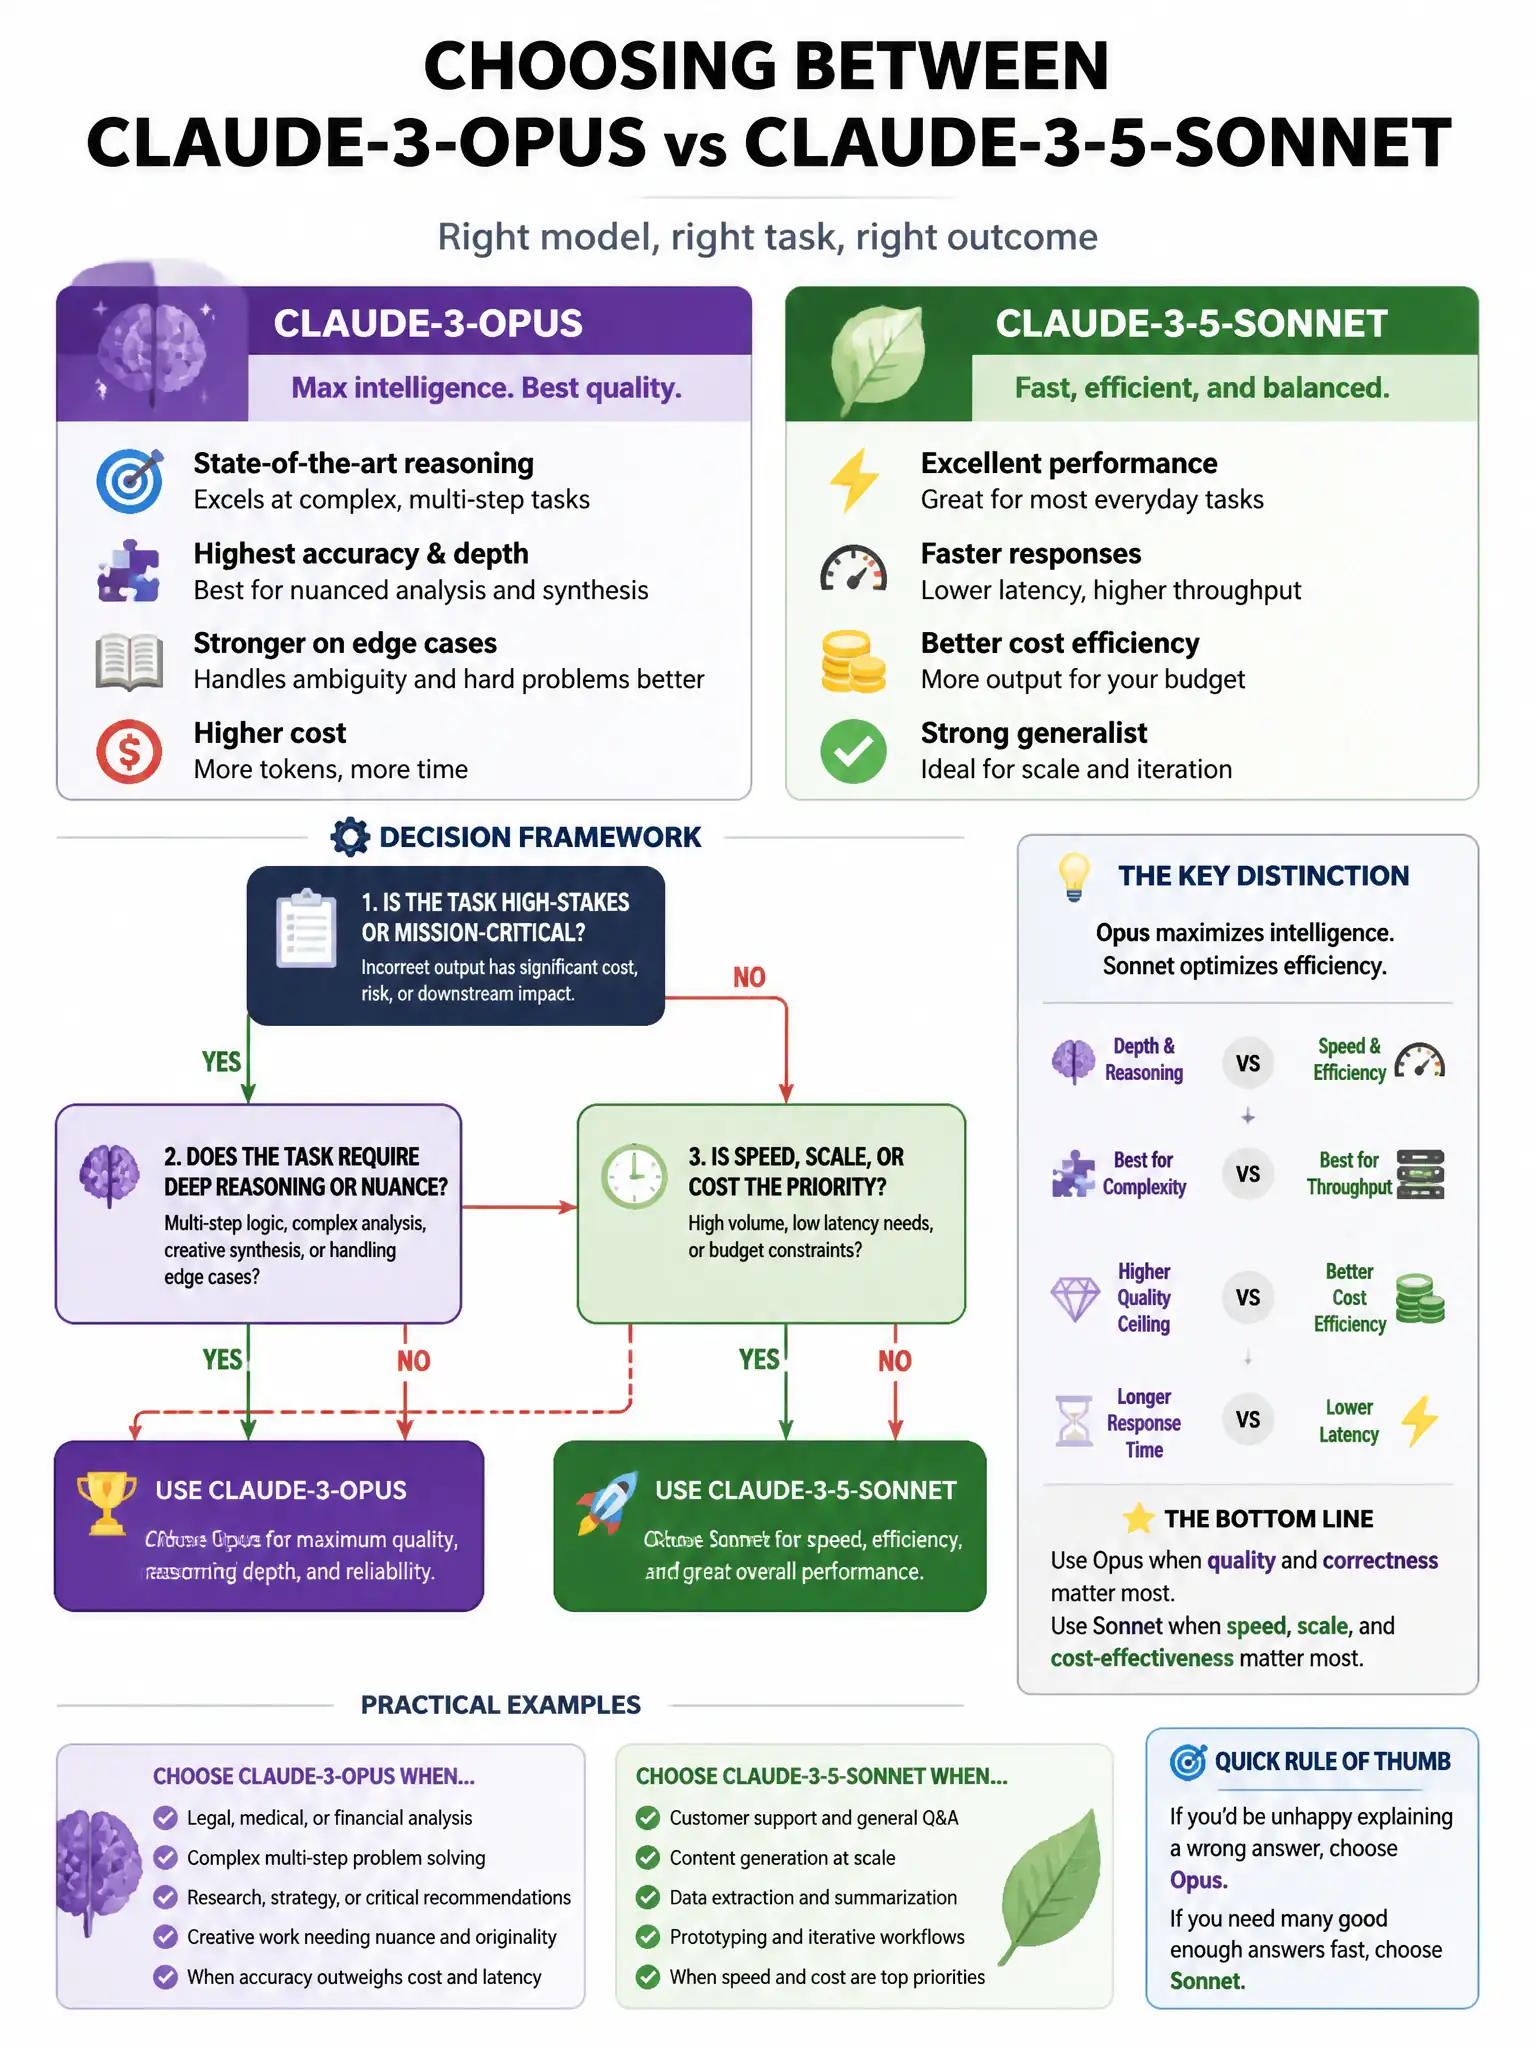
Here's the deal — you should use Opus when the task needs deep, multi-step reasoning over ambiguous inputs and the reasoning chain directly affects whether the final answer is correct. Sonnet is often just as good on many common tasks, so don't pay for Opus unless that reasoning depth is the real bottleneck.
Full Explanation
The correct criterion is tasks involving novel multi-step reasoning over ambiguous inputs where intermediate reasoning quality materially affects output correctness, such as research synthesis and complex code architecture analysis. Opus's primary differentiation is on tasks requiring deep, multi-step reasoning over ambiguous or complex inputs — research synthesis, complex architectural decisions, and novel problem solving where reasoning chain quality cascades to final answer quality. The user-facing feature option is wrong because Sonnet produces outputs that are indistinguishable from or superior to Opus on many common tasks — 'quality perception' is not a reliable criterion without task complexity analysis. The long-context option is wrong because Sonnet and Opus share similar context window sizes; context length alone is not the distinguishing factor. The high-volume classification option is wrong because classification tasks are typically well-suited to Haiku or Sonnet; they involve pattern matching over well-defined categories, not novel reasoning — using Opus wastes cost without quality gain.