
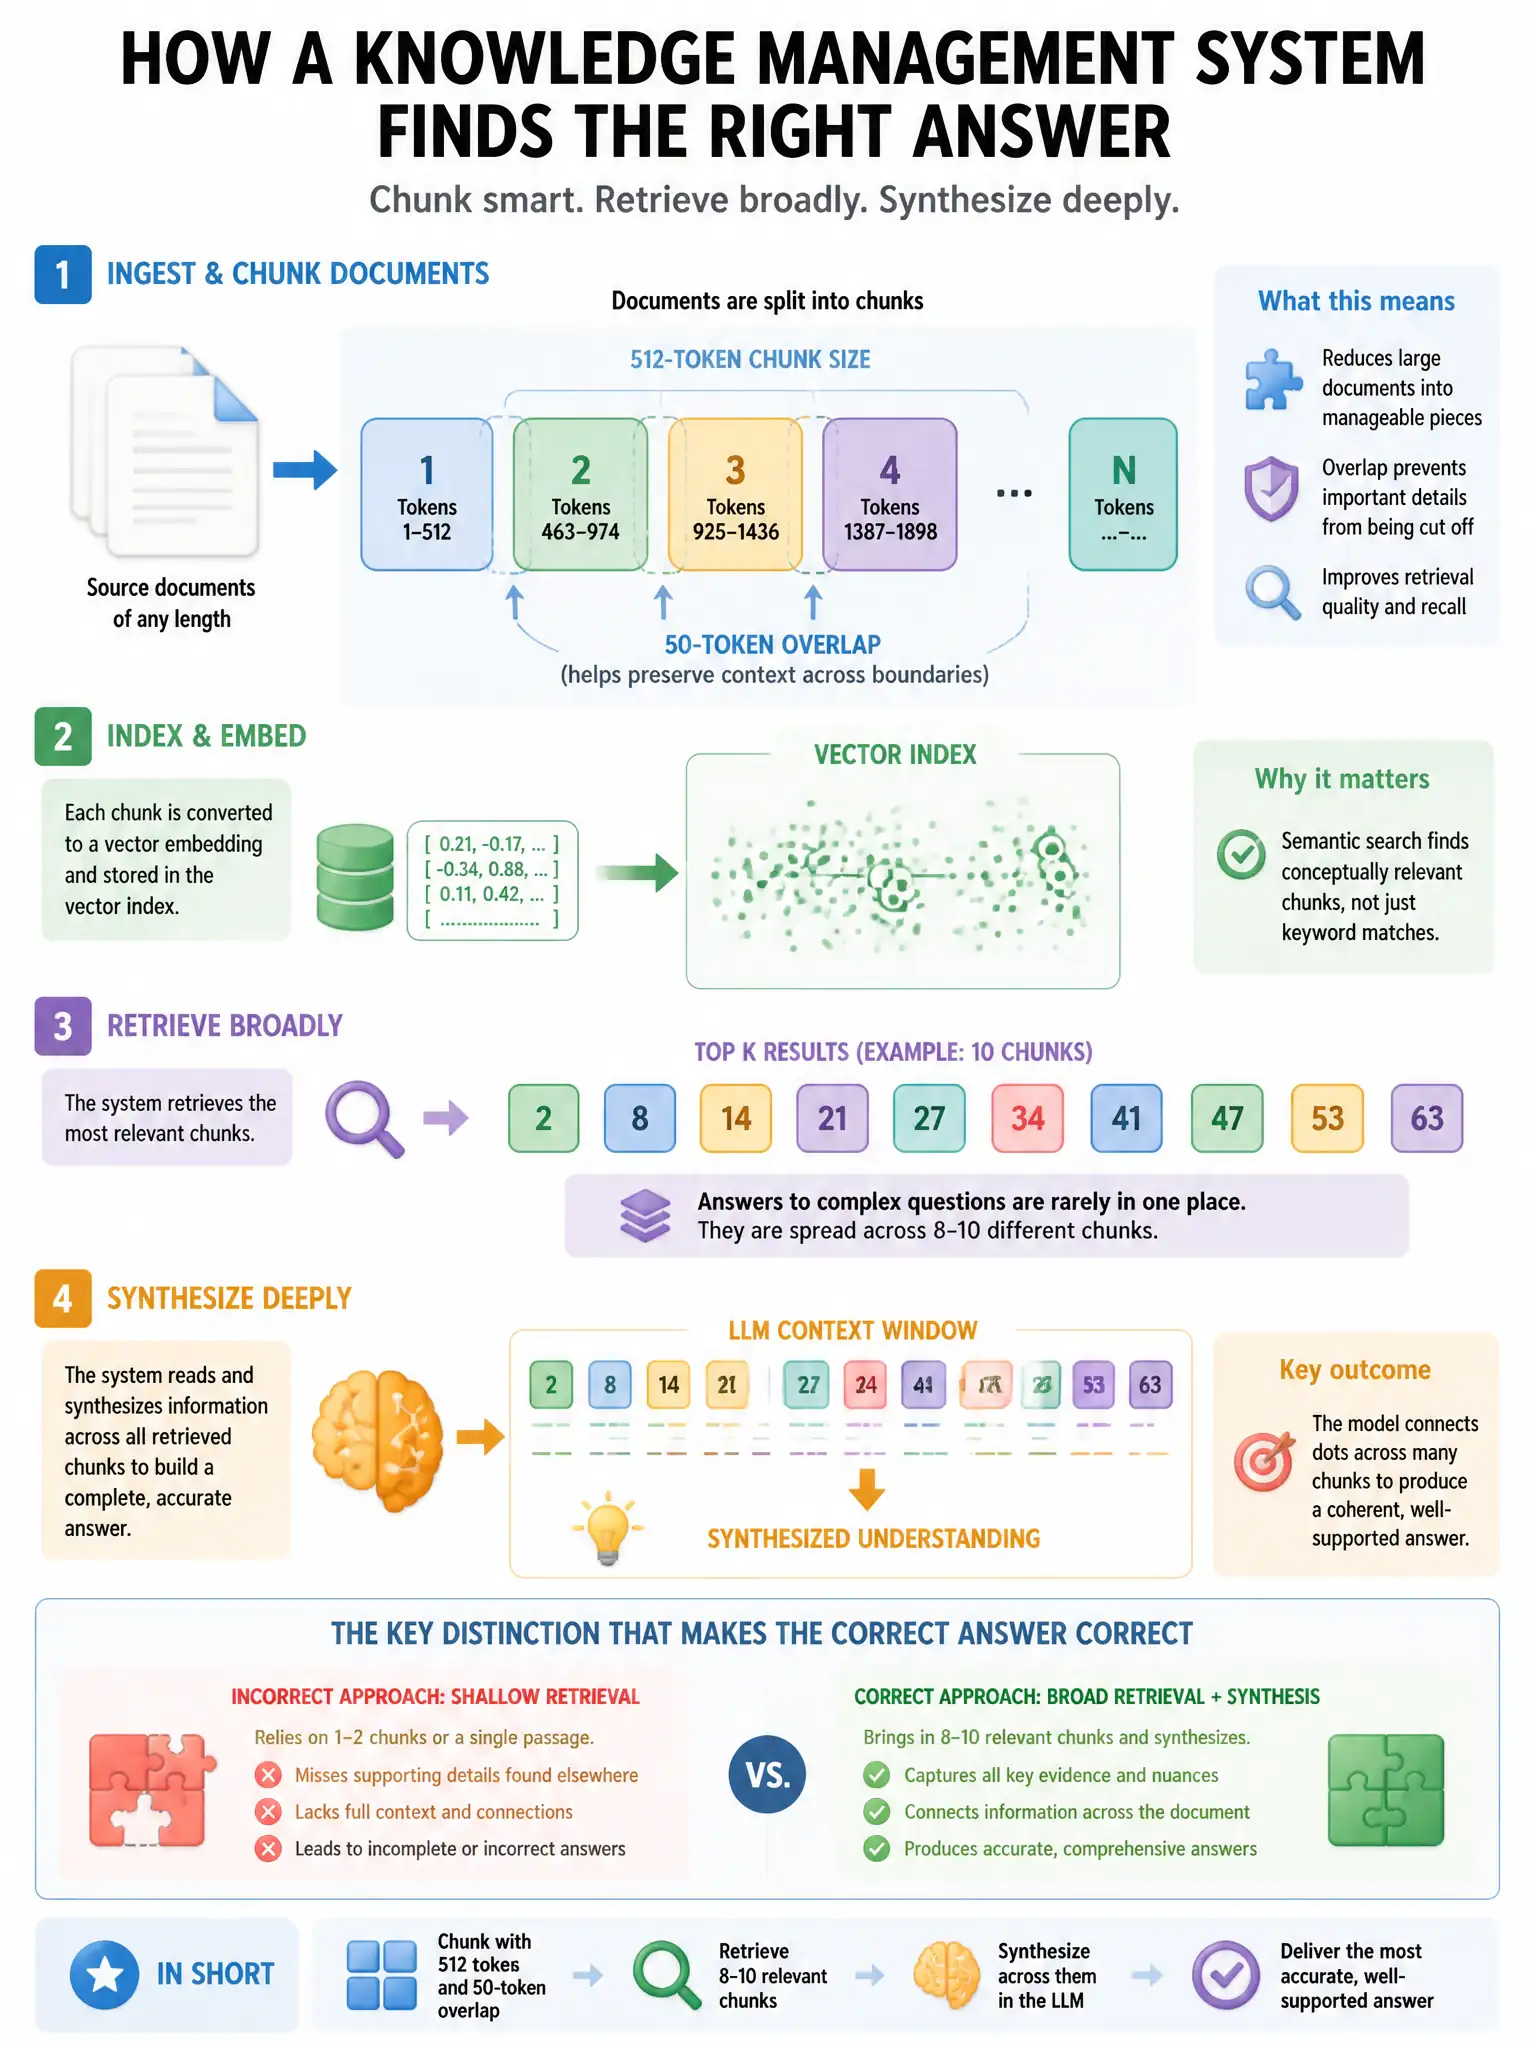
A knowledge management system chunks documents into 512-token chunks with 50-token overlap. Users ask questions that require synthesizing information spread across 8-10 chunks. Retrieved chunks are limited to top-5 by default. Engineers increase top-k to 20 to capture more chunks but find answer quality degrades because the LLM context is now full of marginally relevant chunks. What retrieval architecture addresses this more effectively?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need the two-stage retrieval pipeline because the real issue is precision, not just volume. First, pull the wider candidate set with approximate nearest-neighbor search, then rerank candidates with the cross-encoder and send only the strongest chunks to the language model.
Full Explanation
The two-stage retrieval pipeline is correct because the problem is retrieval precision: approximate nearest-neighbor vector search retrieves semantically plausible candidates but lacks the fine-grained relevance discrimination needed to distinguish essential chunks from marginally relevant ones. The cross-encoder reranker evaluates query-document relevance with full attention over both, producing much higher precision scores. Running it over 50 first-stage candidates and passing only the top-10 reranked chunks to the language model gives the model the high-precision, high-coverage set. The option that reduces chunk size to 256 tokens is wrong because each chunk holds less information; the system would need even more chunks to capture the same content, not fewer, and the precision problem is unchanged. The option that increases the language model's max_tokens parameter is wrong because max_tokens controls output length, not input processing; the problem is that marginally relevant input degrades synthesis, which is not addressed by allowing longer output. The option that pre-generates the 200-token meta-chunk summary for each document is wrong because meta-chunk retrieval is useful for document-level selection but does not solve the within-document chunk precision problem; it also requires pre-generating summaries for every document, adding ingestion overhead.