
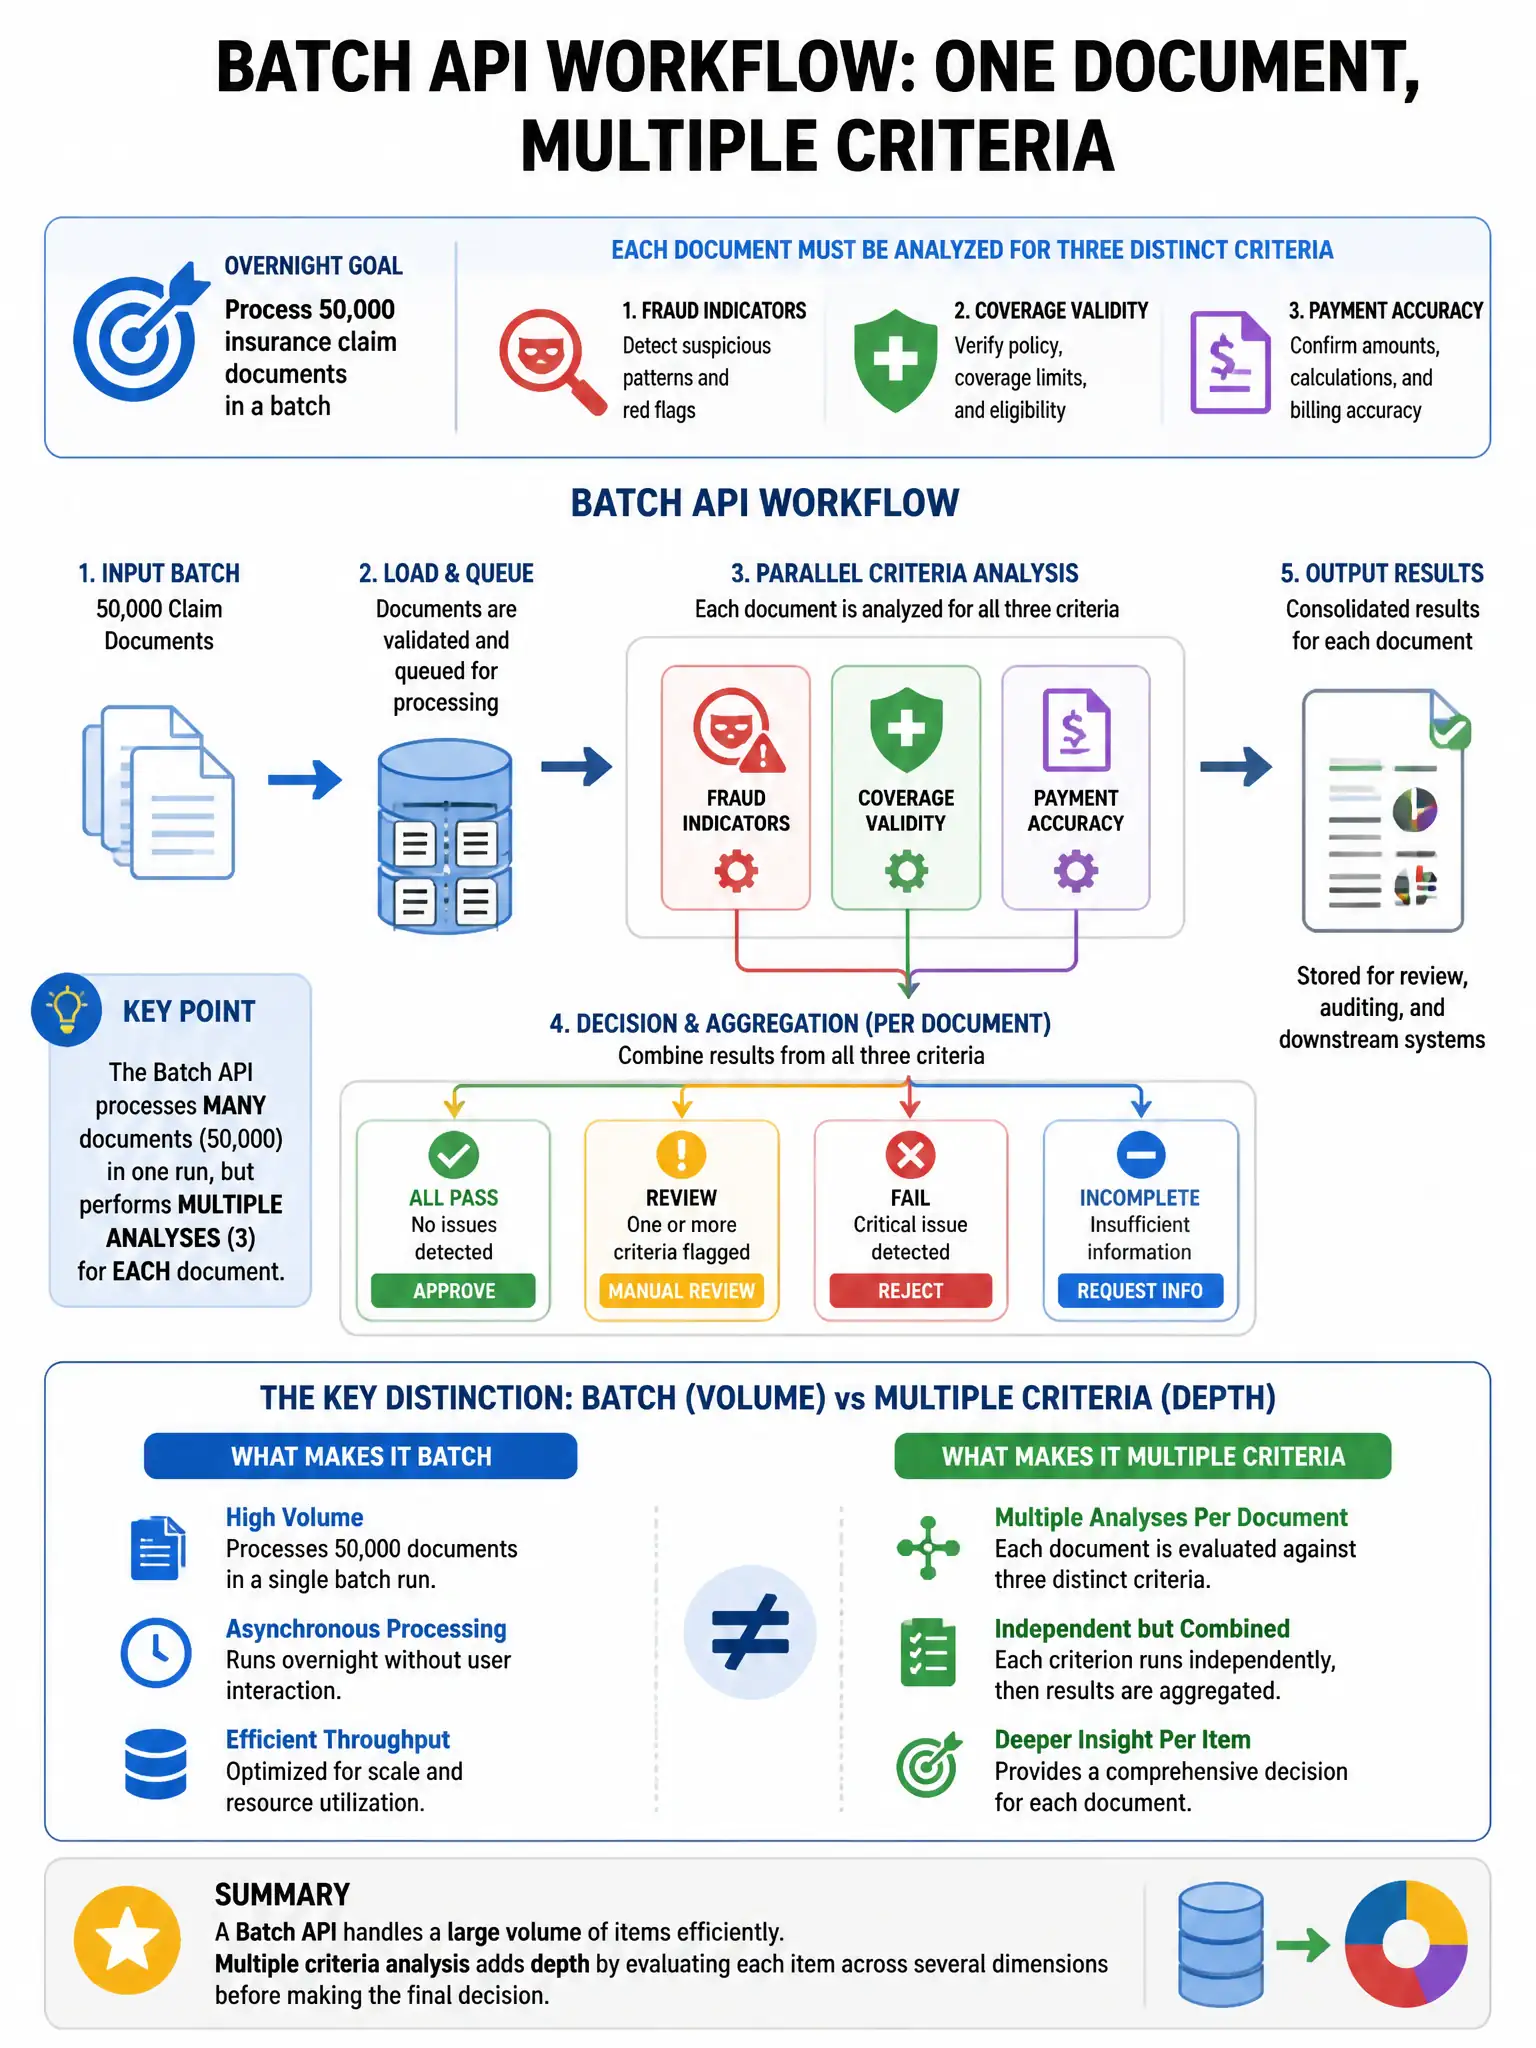
A team is designing a Batch API workflow that processes 50,000 insurance claim documents overnight. Each document must be analyzed for three distinct criteria (fraud indicators, compliance flags, and summary generation), producing three separate outputs per document. What batch architecture minimizes total API round-trips and cost?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want one batch of 50,000 requests, with each prompt asking Claude to analyze fraud indicators, compliance flags, and summary in one structured JSON object. That cuts API calls from 150,000 to 50,000, reads each document once, and lowers batch overhead and cost.
Full Explanation
The single-batch architecture, where each request asks Claude to analyze all three criteria and return a structured JSON object with three top-level keys, is correct because combining all three analysis criteria into a single prompt per document reduces the total number of API requests from 150,000 (3 criteria × 50,000 documents) to 50,000. This reduces batch management overhead, input token processing for the document (which is read once, not three times), and total cost. Structured JSON output with three keys allows downstream systems to parse each criterion independently. The three-separate-batches approach, submitting three batches of 50,000 requests each and joining results client-side, is wrong because it triples the number of requests and the cost of processing each document's context, since the document itself must be sent three times. The 50,000-small-batches approach, submitting 50,000 batches of three requests each, is wrong because it is operationally complex, requiring 50,000 separate batch submissions and status polls, and offers no advantage over the single-batch architecture; criterion isolation can be maintained within a single multi-key JSON response. The synchronous Messages API approach is wrong because the Batch API fully supports JSON-structured output; there is no such limitation, and using the synchronous API for 50,000 documents would be slower and potentially more expensive without the batch discount.