
A RAG system serves a Fortune 500 company's internal Q&A platform with strict access control: employees should only receive answers grounded in documents they are authorized to access. The document corpus has 50,000 documents across 200 access control groups. Current architecture: all documents share a single vector index; access control is enforced by post-retrieval filtering (retrieve k=50, filter to authorized, pass top-5 to Claude). Security audit finds that with k=50 retrieval and heavy access filtering, Claude occasionally synthesizes information from filtered-out documents that appeared in earlier sessions and were cached in Claude's context window. What is the correct architectural fix?
Select an answer to reveal the explanation.
Short Explanation
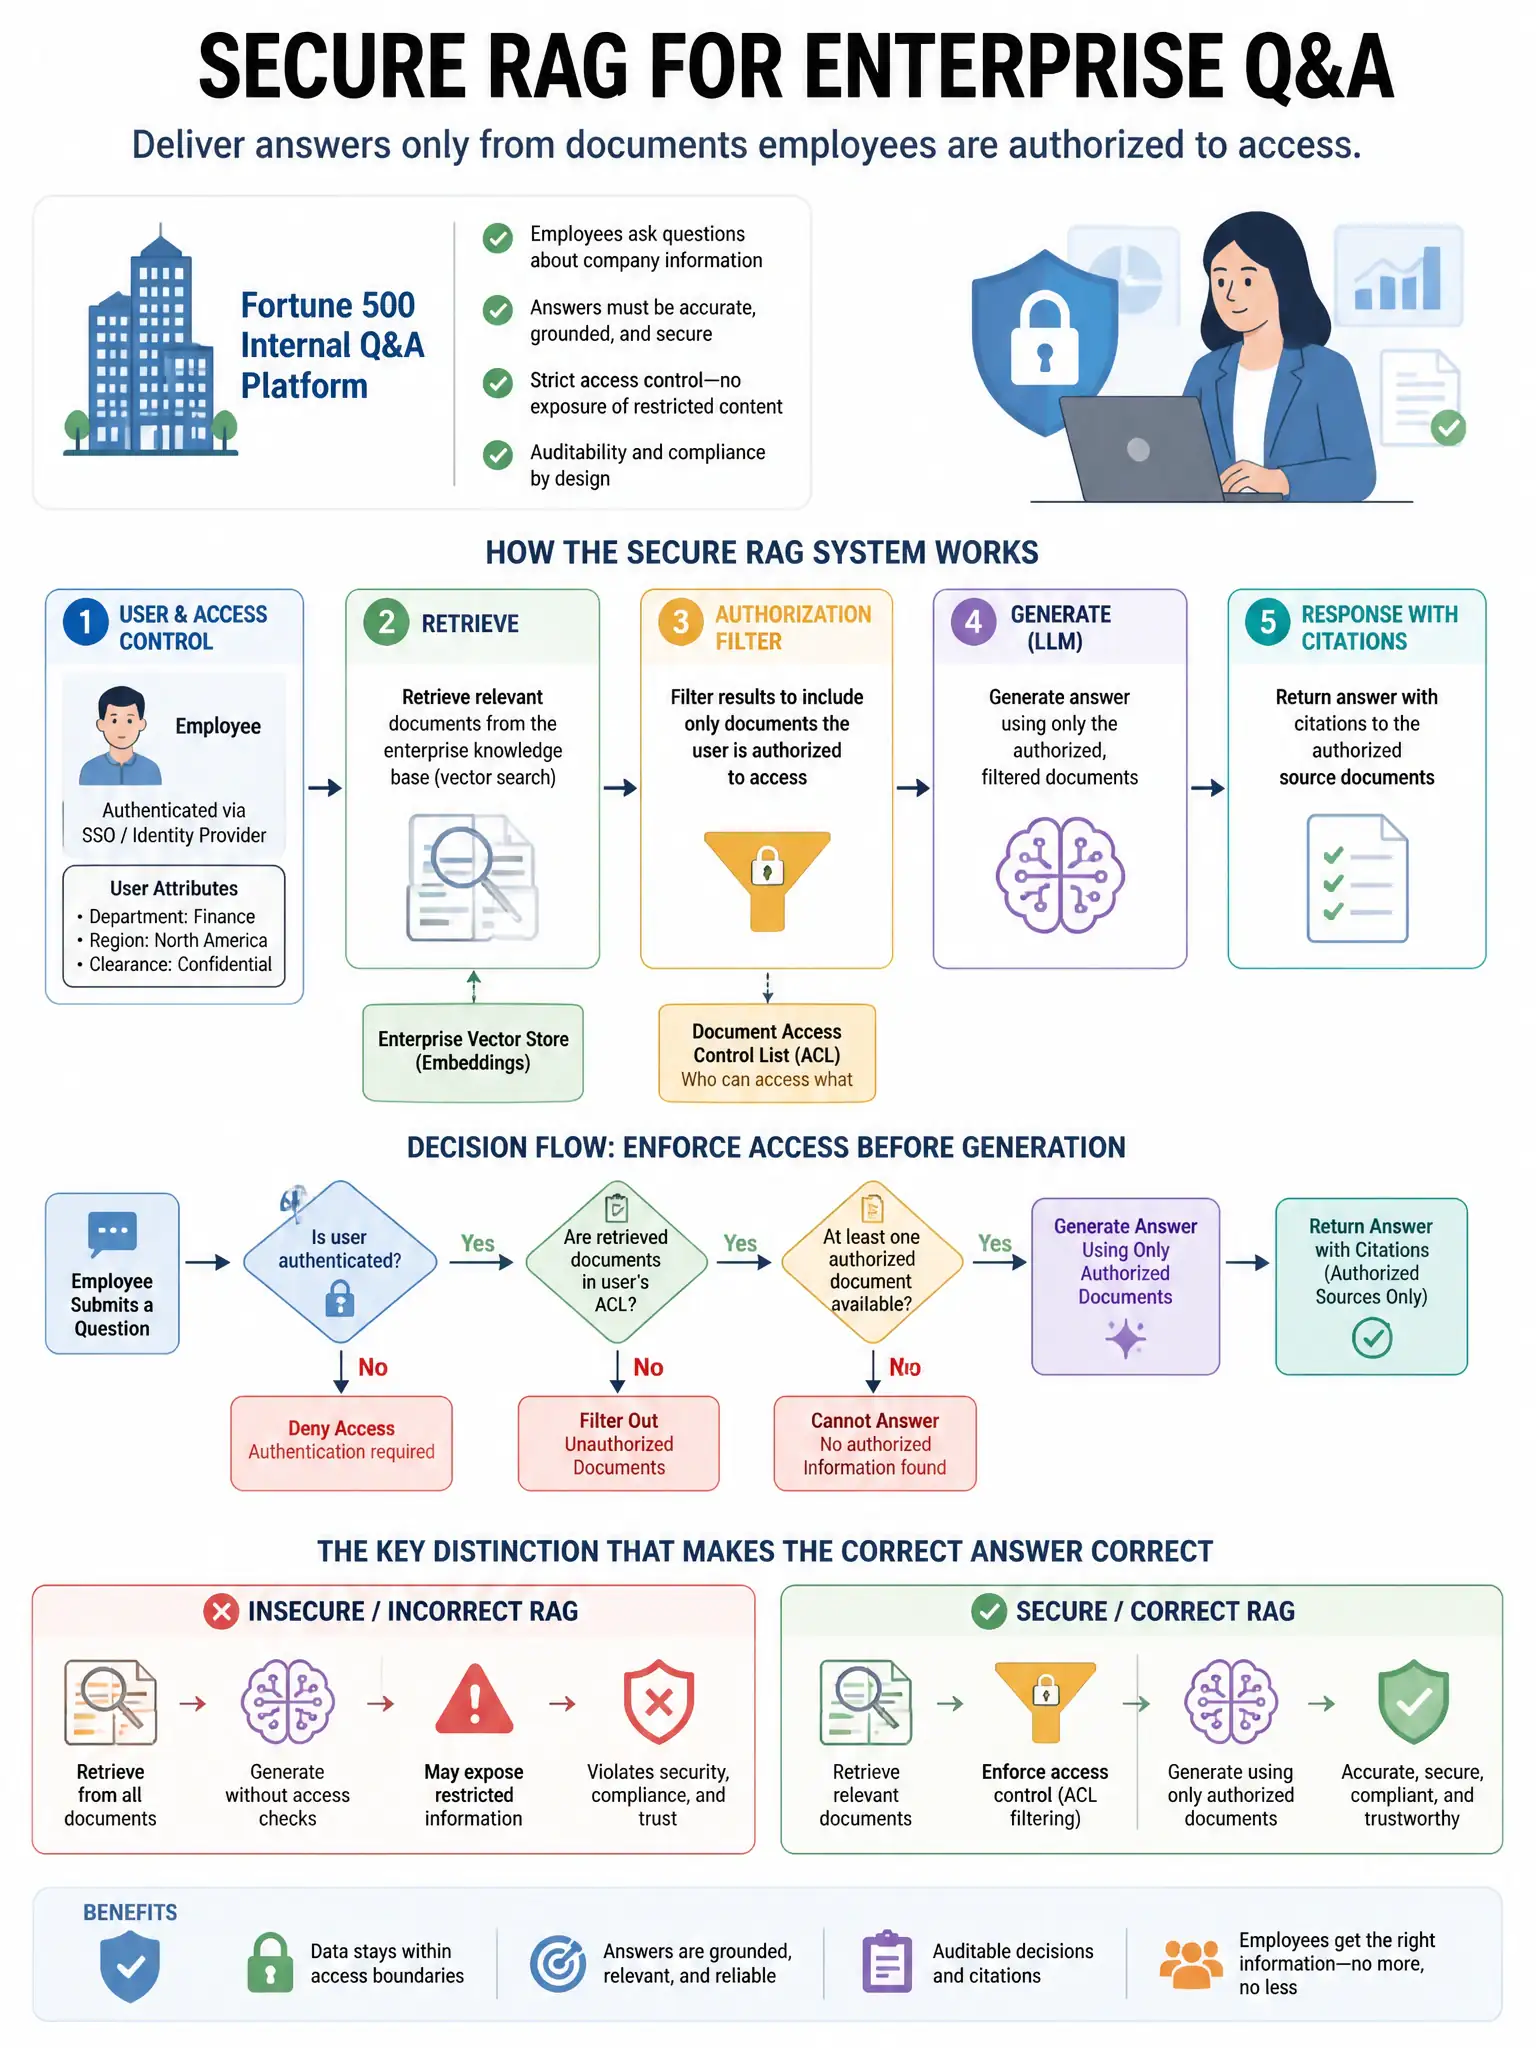
You need to stop unauthorized documents from ever entering the pipeline. Partition the vector index by access group and route queries only to indexes the user can access. That way filtered-out documents can't leak through context or earlier turns.
Full Explanation
Per-user or per-access-group vector index partitioning is the correct architectural fix for the described security vulnerability. The audit finding is that the current post-retrieval filtering approach retrieves unauthorized documents, passes them to a filtering step, and assumes they never reach Claude — but the security finding is about Claude's context from earlier sessions, not the current session's retrieval. The real vulnerability is that post-retrieval filtering doesn't prevent unauthorized documents from appearing in Claude's context if they were retrieved, even if filtered, in ways that populate context. The architectural fix is pre-retrieval access control: partition the vector index so unauthorized documents are never retrieved, never appear in any intermediate step, and cannot possibly influence Claude's output. The approach of clearing Claude's context window between sessions by using fresh API calls with no conversation history misunderstands the vulnerability — the audit finding about earlier sessions and cached context likely refers to multi-turn conversations where filtered documents appeared in context, not literal API context caching. Fresh API calls help but don't address the core issue of unauthorized documents entering the retrieval pipeline. The approach of increasing the retrieval count to 200 before filtering, on the theory that too few authorized documents survive filtering and Claude extrapolates from session memory, worsens the problem by retrieving more unauthorized documents before filtering. The approach of moving access control enforcement to the embedding layer by appending access control tokens to documents and queries is not a real access control mechanism — appending tokens to embeddings does not reliably encode access control as a geometric property.