
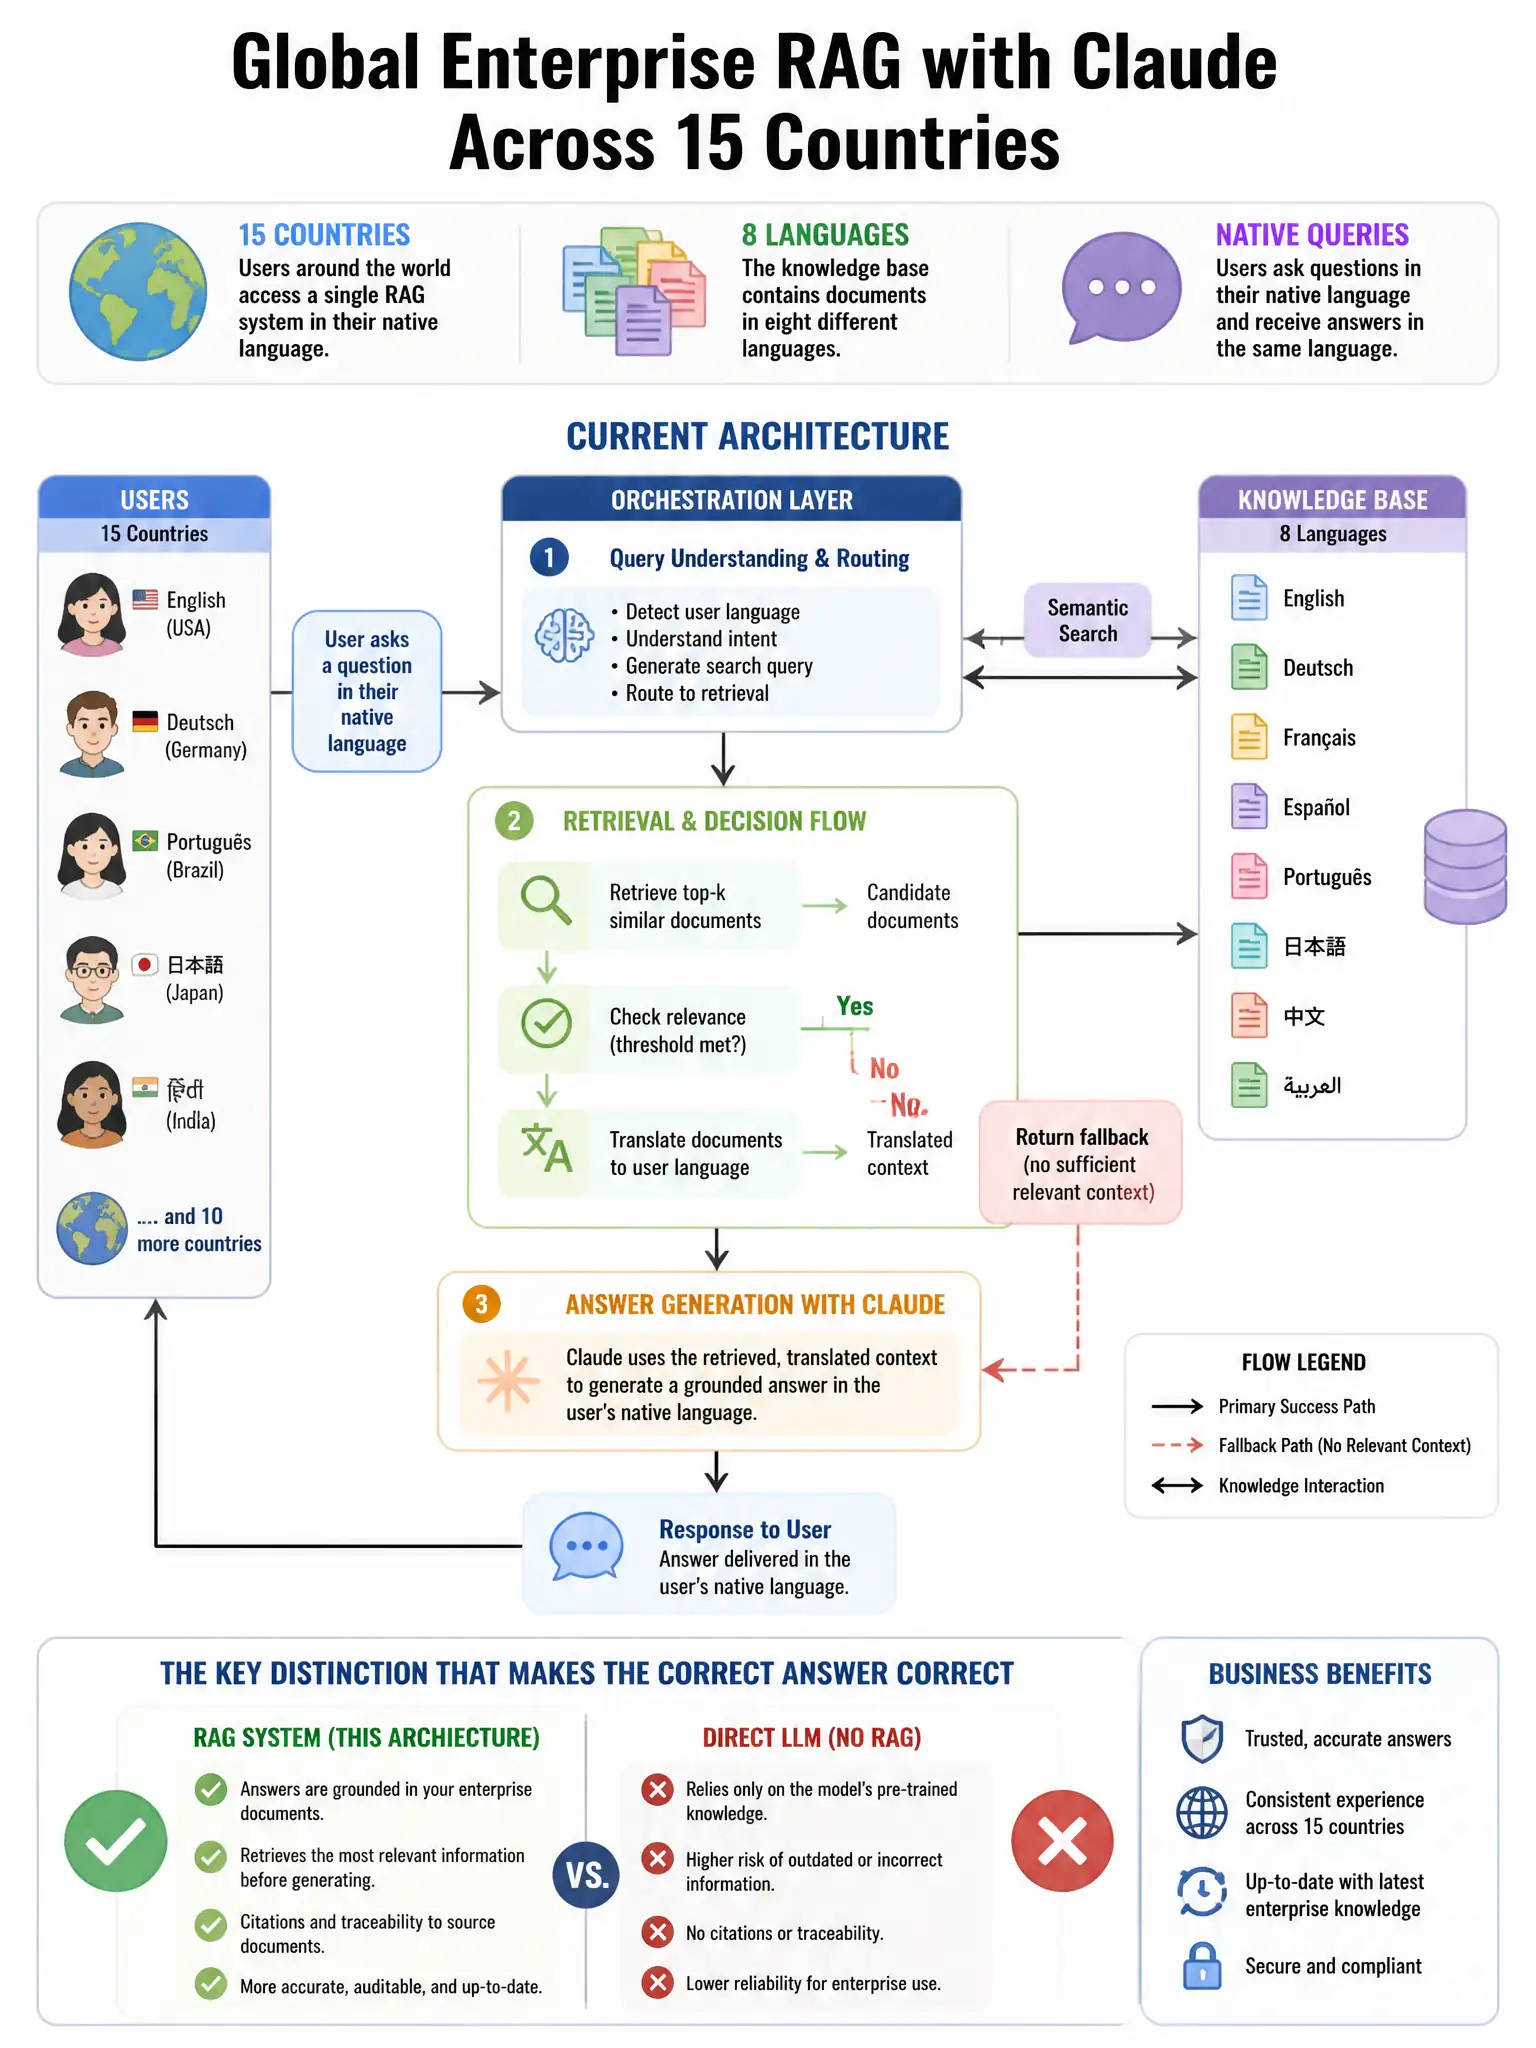
A global enterprise deploys a RAG system with Claude across 15 countries. The knowledge base contains documents in 8 languages. Users query in their native language. Current architecture: all documents are stored with their original language embeddings; queries are embedded in the query language; similarity search runs in the query's embedding space. The system performs well for English but significantly underperforms for Japanese and Arabic queries even when relevant documents exist in those languages. What is the architectural root cause and fix?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — your embedding model is treating languages as separate spaces, so Japanese and Arabic queries can't match the right docs. You need a multilingual embedding model that puts every language into one shared cross-lingual space.
Full Explanation
The architectural root cause is that the current embedding model lacks sufficient Japanese and Arabic training data, or is otherwise monolingual or weakly multilingual, so it creates separate embedding spaces per language. Because documents are stored with original-language embeddings and queries are embedded in the query language, similarity search only works well when the query and document embeddings share the same geometric space. A Japanese query embedding is not comparable to an English or Arabic document embedding when those languages occupy different embedding spaces. The fix is a multilingual embedding model that creates a single shared cross-lingual embedding space, where semantically equivalent content in different languages occupies nearby positions regardless of language. This directly enables Japanese queries to retrieve English or Arabic documents, and vice versa, if they cover the same topic. The language-specific chunking option points out that Japanese text has no spaces and Arabic is right-to-left, and that language-specific tokenization and chunking pipelines can improve tokenization quality, especially for Japanese. But it doesn't fix the cross-lingual embedding space problem; correctly tokenized Japanese documents in a separate embedding space still won't be retrieved by Japanese queries. The translate-to-English option is a valid but architecturally heavyweight workaround that introduces translation latency, translation errors, and requires translation infrastructure for eight languages. It also loses nuance in translation-sensitive domains. The cross-lingual reranking option improves precision, but it only helps if the initial retrieval already returns relevant documents; if the embedding space doesn't support cross-lingual similarity, initial retrieval won't return enough relevant non-English documents to rerank.