
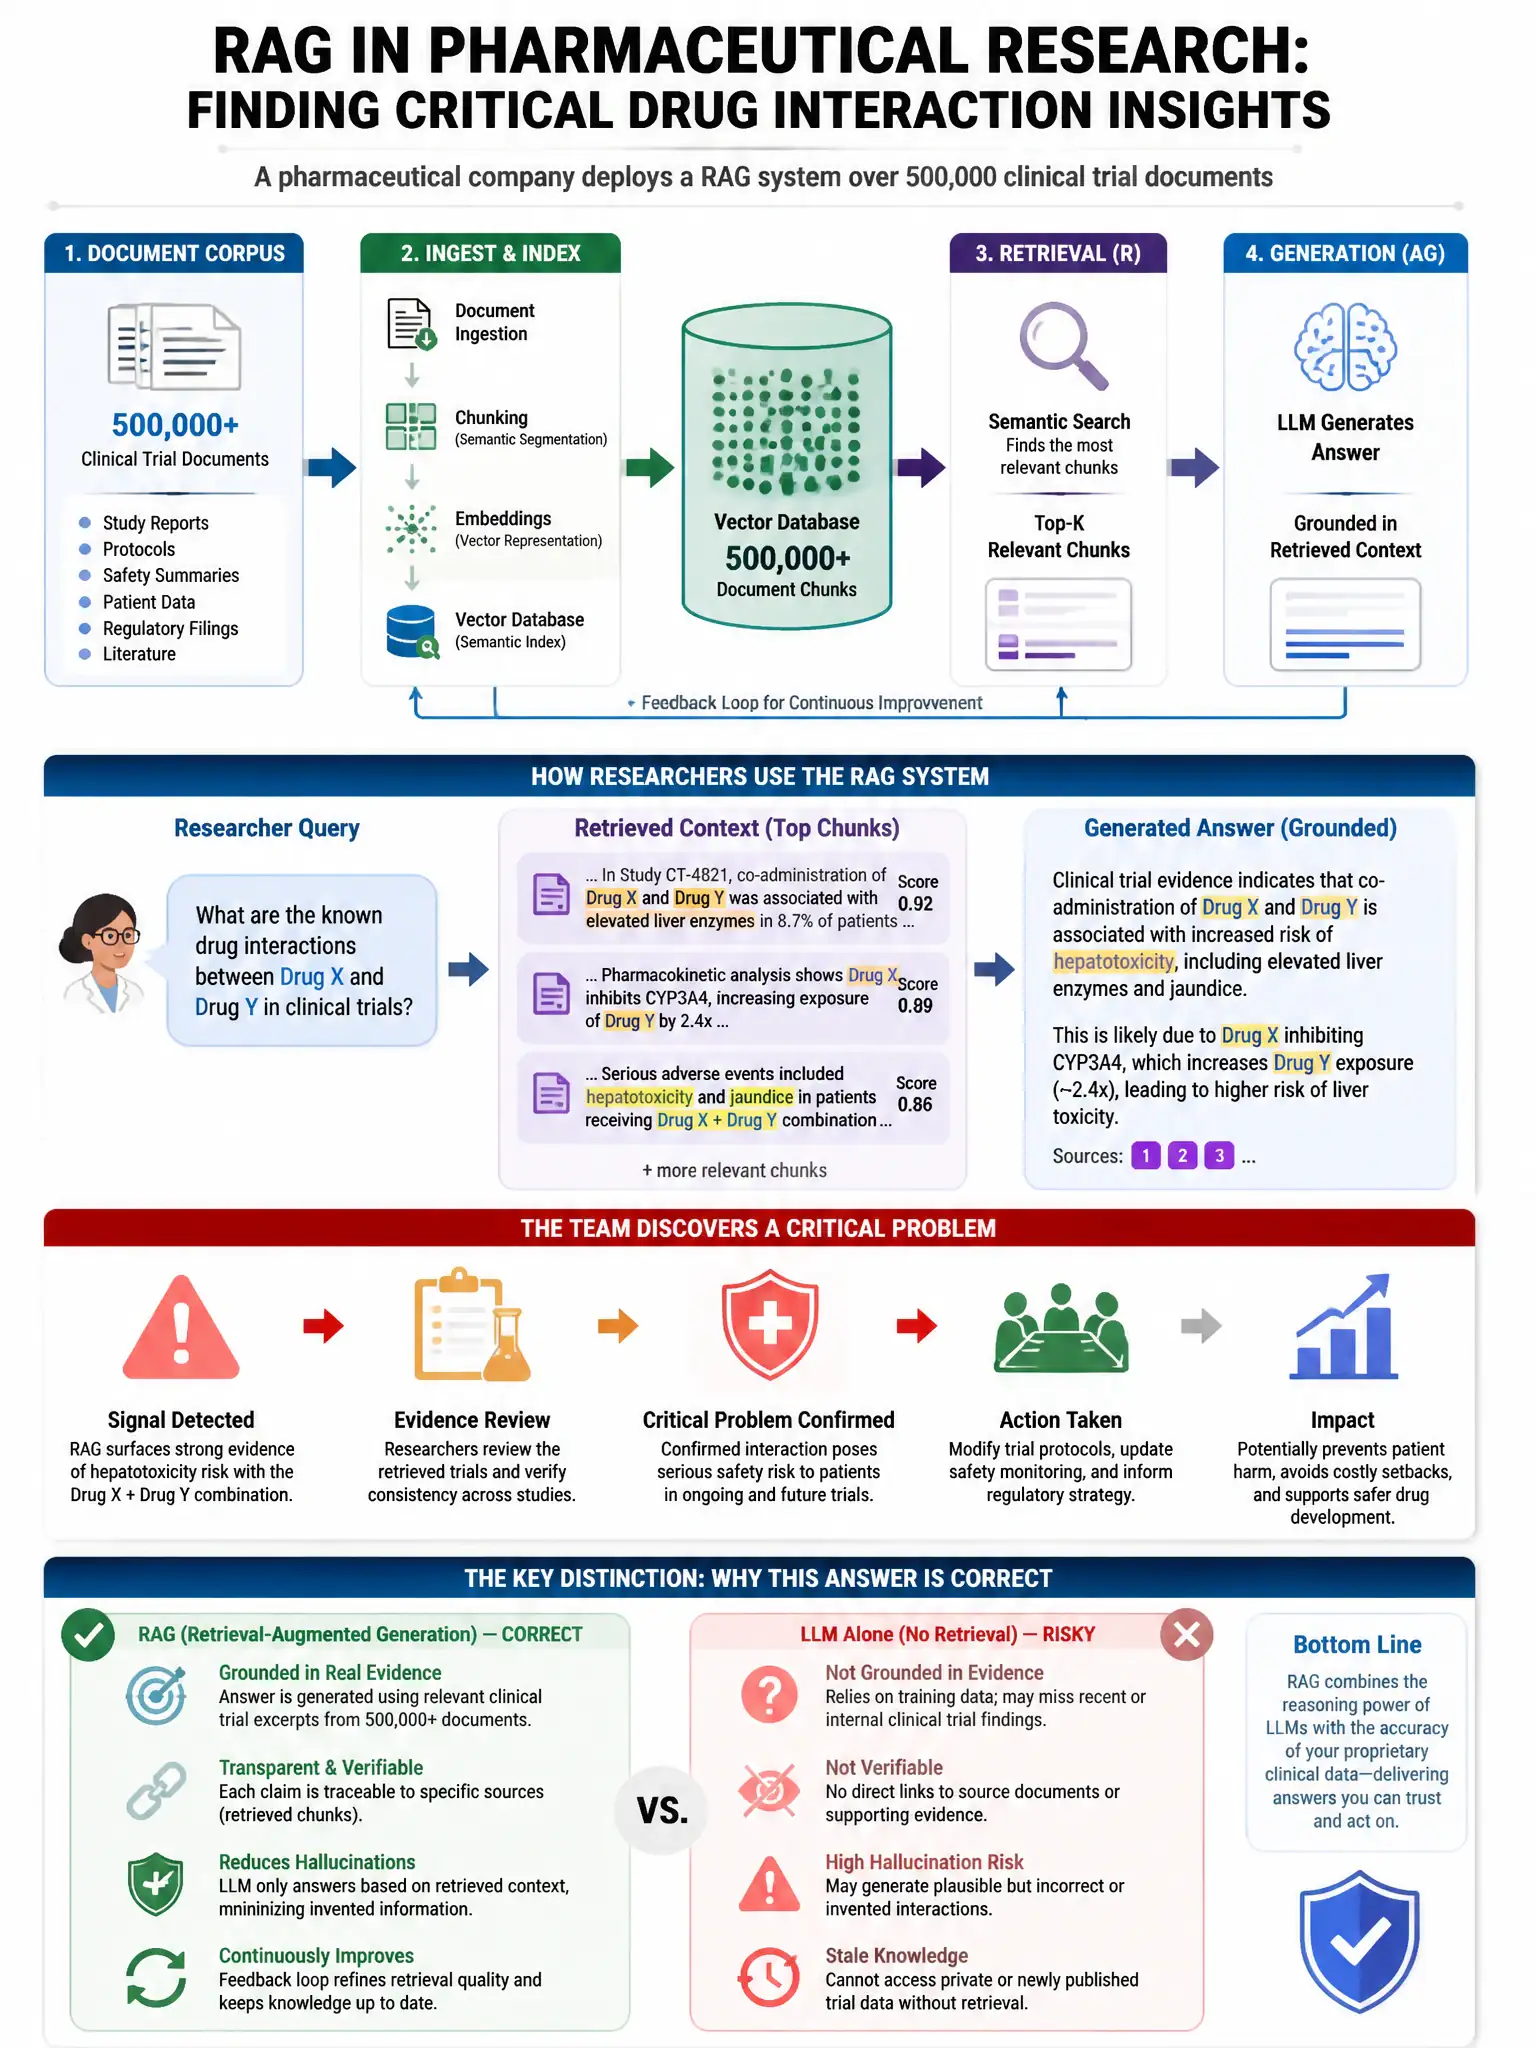
A pharmaceutical company deploys a RAG system over 500,000 clinical trial documents. Researchers query the system for drug interaction information. The team discovers a critical production issue: when a researcher asks about Drug A + Drug B interactions, the system correctly retrieves interaction documents but Claude's response occasionally incorporates information from Drug A + Drug C interactions retrieved in the same batch (documents about Drug A are semantically similar regardless of the co-drug). Precision on the Drug A + Drug B specific queries is 61%. What retrieval architecture change most directly improves precision for compound-specific queries?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need mandatory keyword pre-filtering that requires both drugs in the queried pair to appear before vector ranking. That keeps documents about the same drug paired with another co-drug out of the candidate set. It’s the direct architecture fix for compound-specific precision.
Full Explanation
Mandatory keyword pre-filtering on both drugs in the queried pair is the architecturally correct solution for compound-specific query precision. The problem is that documents about the same drug, regardless of the co-drug, are semantically similar, causing documents about that drug paired with another co-drug to rank highly for queries about the intended drug pair. Vector similarity cannot distinguish between these because interaction text for the same drug is semantically close to interaction text for the same drug paired with another co-drug. The pre-filter requiring both drug names to appear in document metadata or text eliminates documents about the same drug paired with another co-drug from consideration before semantic ranking even runs. This is the hybrid retrieval pattern applied correctly: keyword filtering for specificity, vector similarity for relevance within the filtered set. The query expansion approach, which generates multiple reformulations of the query and retrieves on all reformulations before deduplicating results, retrieves more documents about the same drug, worsening the co-drug contamination problem by increasing recall for all interactions involving that drug. The smaller-chunk approach, reducing chunk size from one thousand tokens to two hundred tokens, may help by making individual chunks more drug-pair specific, but each two-hundred-token chunk from any document about the same drug paired with another co-drug still gets retrieved if it is semantically similar to the intended drug-pair query. The post-retrieval relevance filter approach, which passes twenty retrieved documents through the secondary Claude call that scores each document's relevance to the specific drug-pair query and keeps only the top five by relevance score, uses the second model call with the same semantic understanding that produced the original retrieval errors, so it may not reliably filter documents about the same drug paired with another co-drug for intended drug-pair queries.