
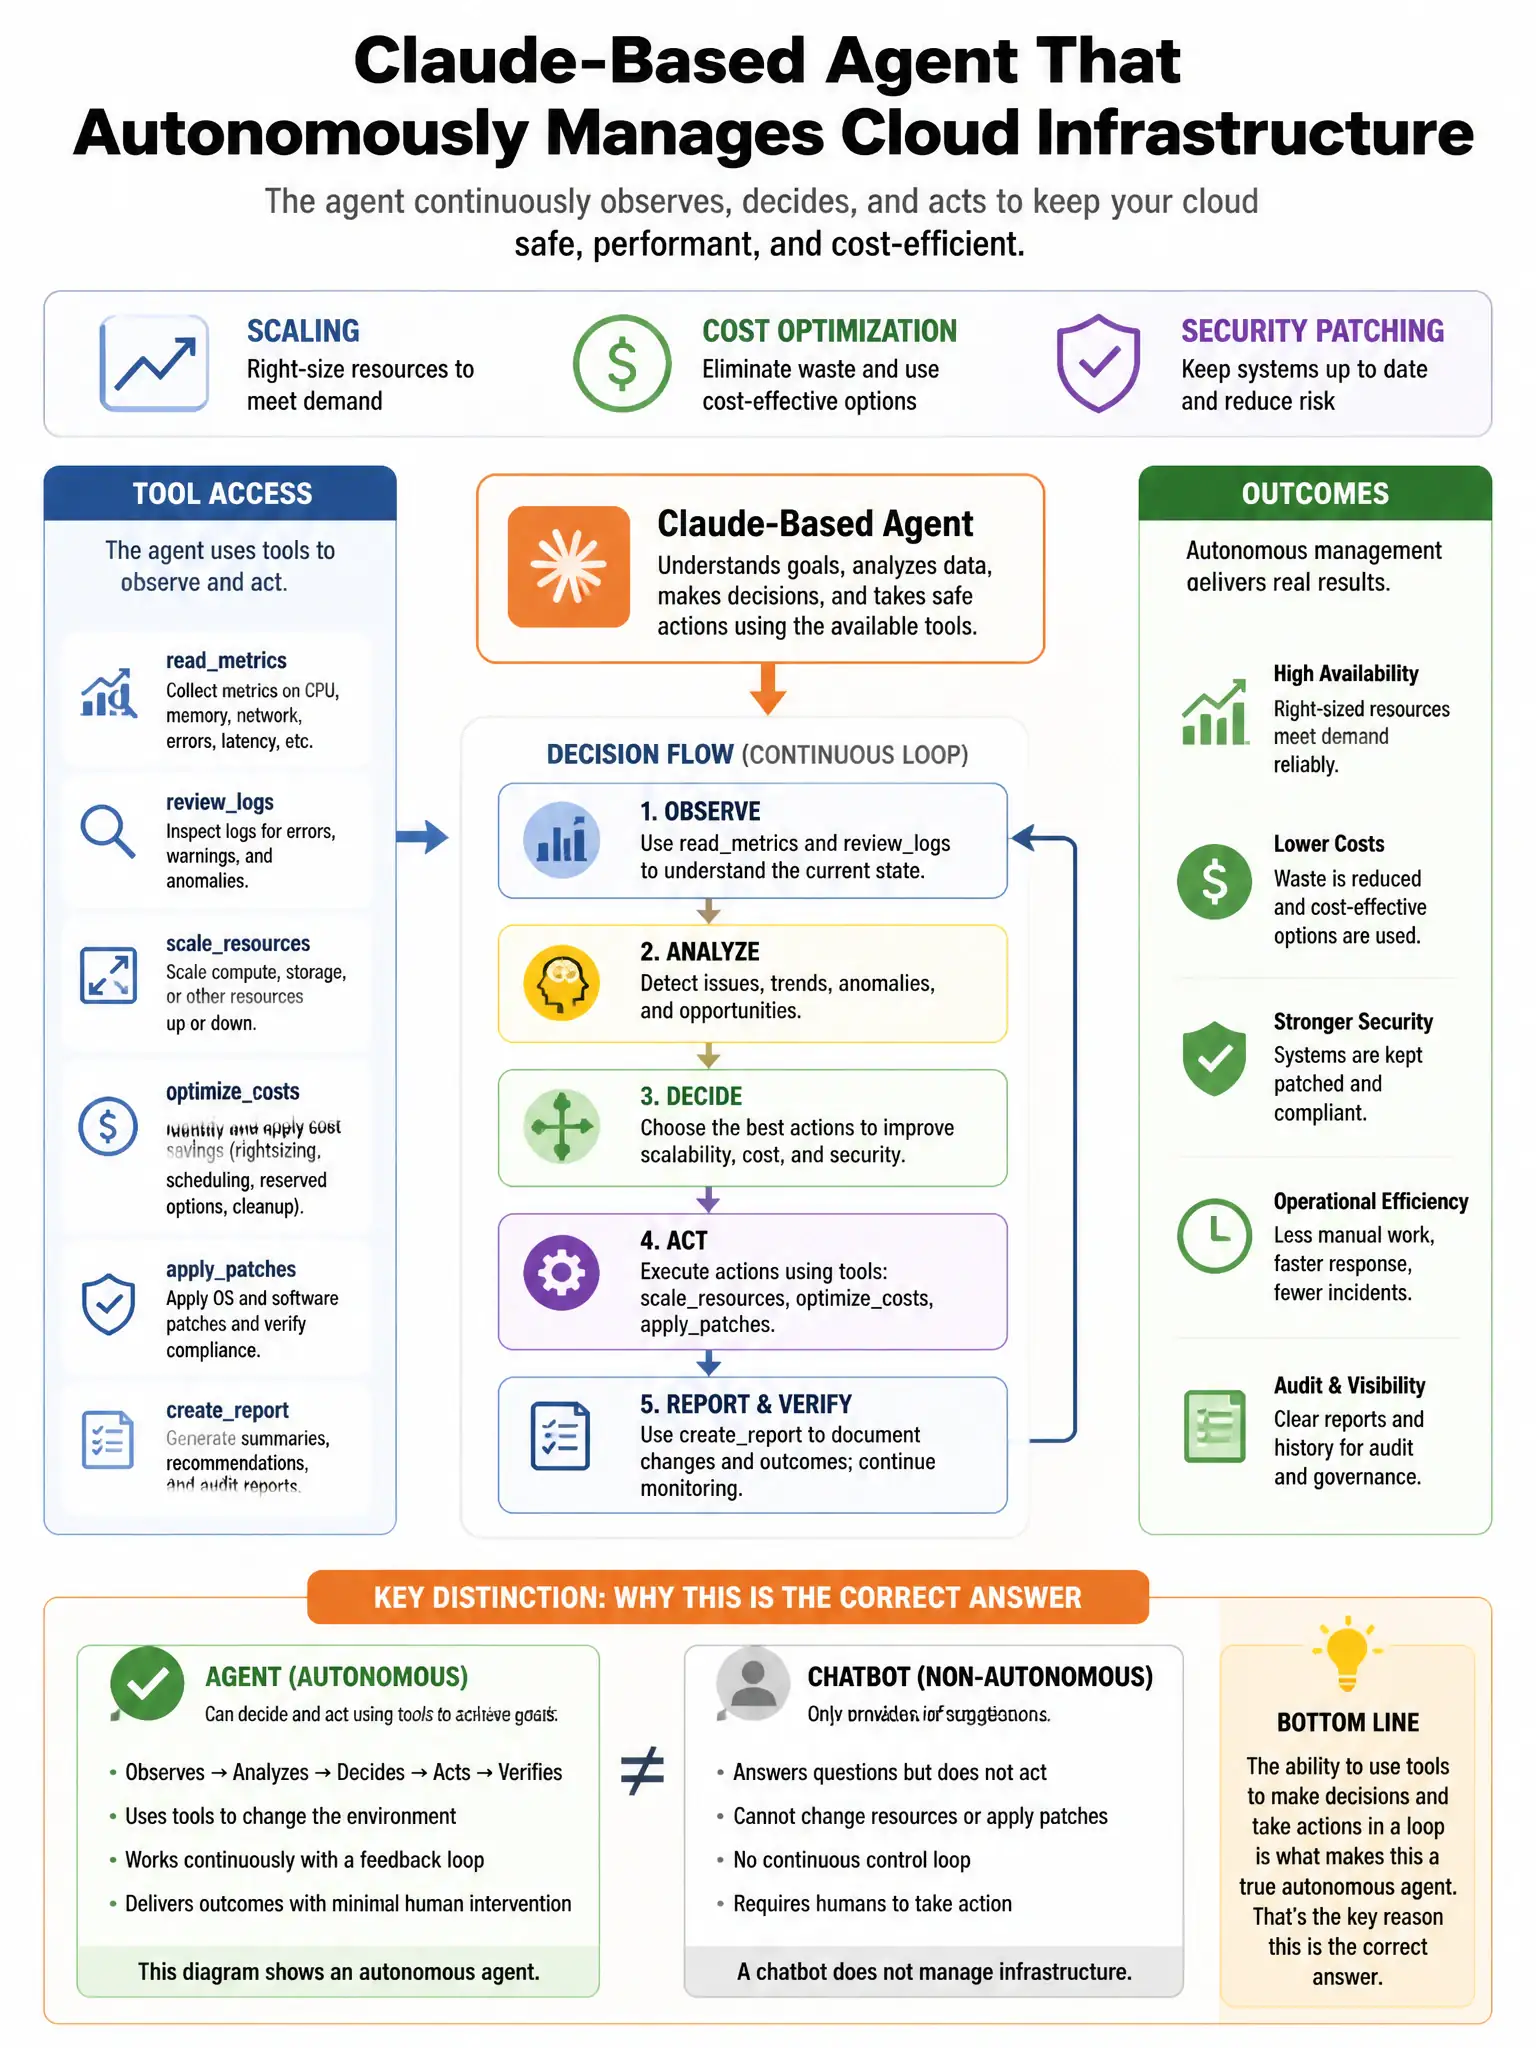
A company builds a Claude-based agent that autonomously manages cloud infrastructure (scaling, cost optimization, security patching). The agent has tool access to: read_metrics, read_config, apply_config, scale_resources, and restart_service. During testing, the agent exhibits a dangerous behavior: when asked to 'optimize costs,' it correctly identifies that terminating idle development EC2 instances would save $3,000/month — and then autonomously terminates them without human confirmation. What is the correct architectural constraint to prevent high-impact autonomous actions?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need action consequence classification in the tool schema, with approval queuing for irreversible or high-impact actions. It keeps the agent useful for low-risk work but puts hard gates on dangerous moves.
Full Explanation
Action consequence classification in the tool schema with approval queuing is the correct architectural solution. It implements the principle of minimal footprint: the agent retains its action tools, which are needed for the use case, but classifies actions by reversibility and impact. read_metrics and read_config are [REVERSIBLE, LOW_IMPACT] and can execute immediately. scale_resources, when adding instances, might be [REVERSIBLE, MEDIUM_IMPACT] and can execute with logging. restart_service is [REVERSIBLE, HIGH_IMPACT] and should queue for approval. apply_config that terminates instances is [IRREVERSIBLE, HIGH_IMPACT] and requires mandatory human approval. This preserves the agent's autonomy for low-risk actions while creating hard gates for high-consequence actions. The system-prompt-only approach, which tells the agent to explain intent and ask for explicit human confirmation before taking hard-to-reverse actions, relies on Claude correctly classifying action consequence; the agent that autonomously terminated instances already failed this judgment, and prompt instructions have not solved it. The read-only recommendation approach, which removes apply_config, scale_resources, and restart_service and returns structured reports for human execution, prevents all autonomous action and defeats the purpose of an infrastructure automation agent. The two-agent approval architecture, where a primary agent proposes actions and a separate approval agent evaluates safety and business impact before execution with human escalation for high-impact decisions, adds another AI to evaluate AI proposals; the approval agent has the same limitations as the primary agent in assessing business context, such as which development instances are actually idle versus temporarily idle during a sprint.