
A research platform needs Claude to analyze 200-page academic papers and produce structured summaries. The team notices that summary quality degrades for papers in specialized domains (quantum computing, synthetic biology) where Claude occasionally conflates established findings with speculative claims. The team's current prompt instructs: 'Accurately summarize this paper, clearly distinguishing between established findings and speculative claims.' Success rate is 74%. Which prompt engineering change produces the most significant improvement? Reviewers must be able to check each classification against the paper.
Select an answer to reveal the explanation.
Short Explanation
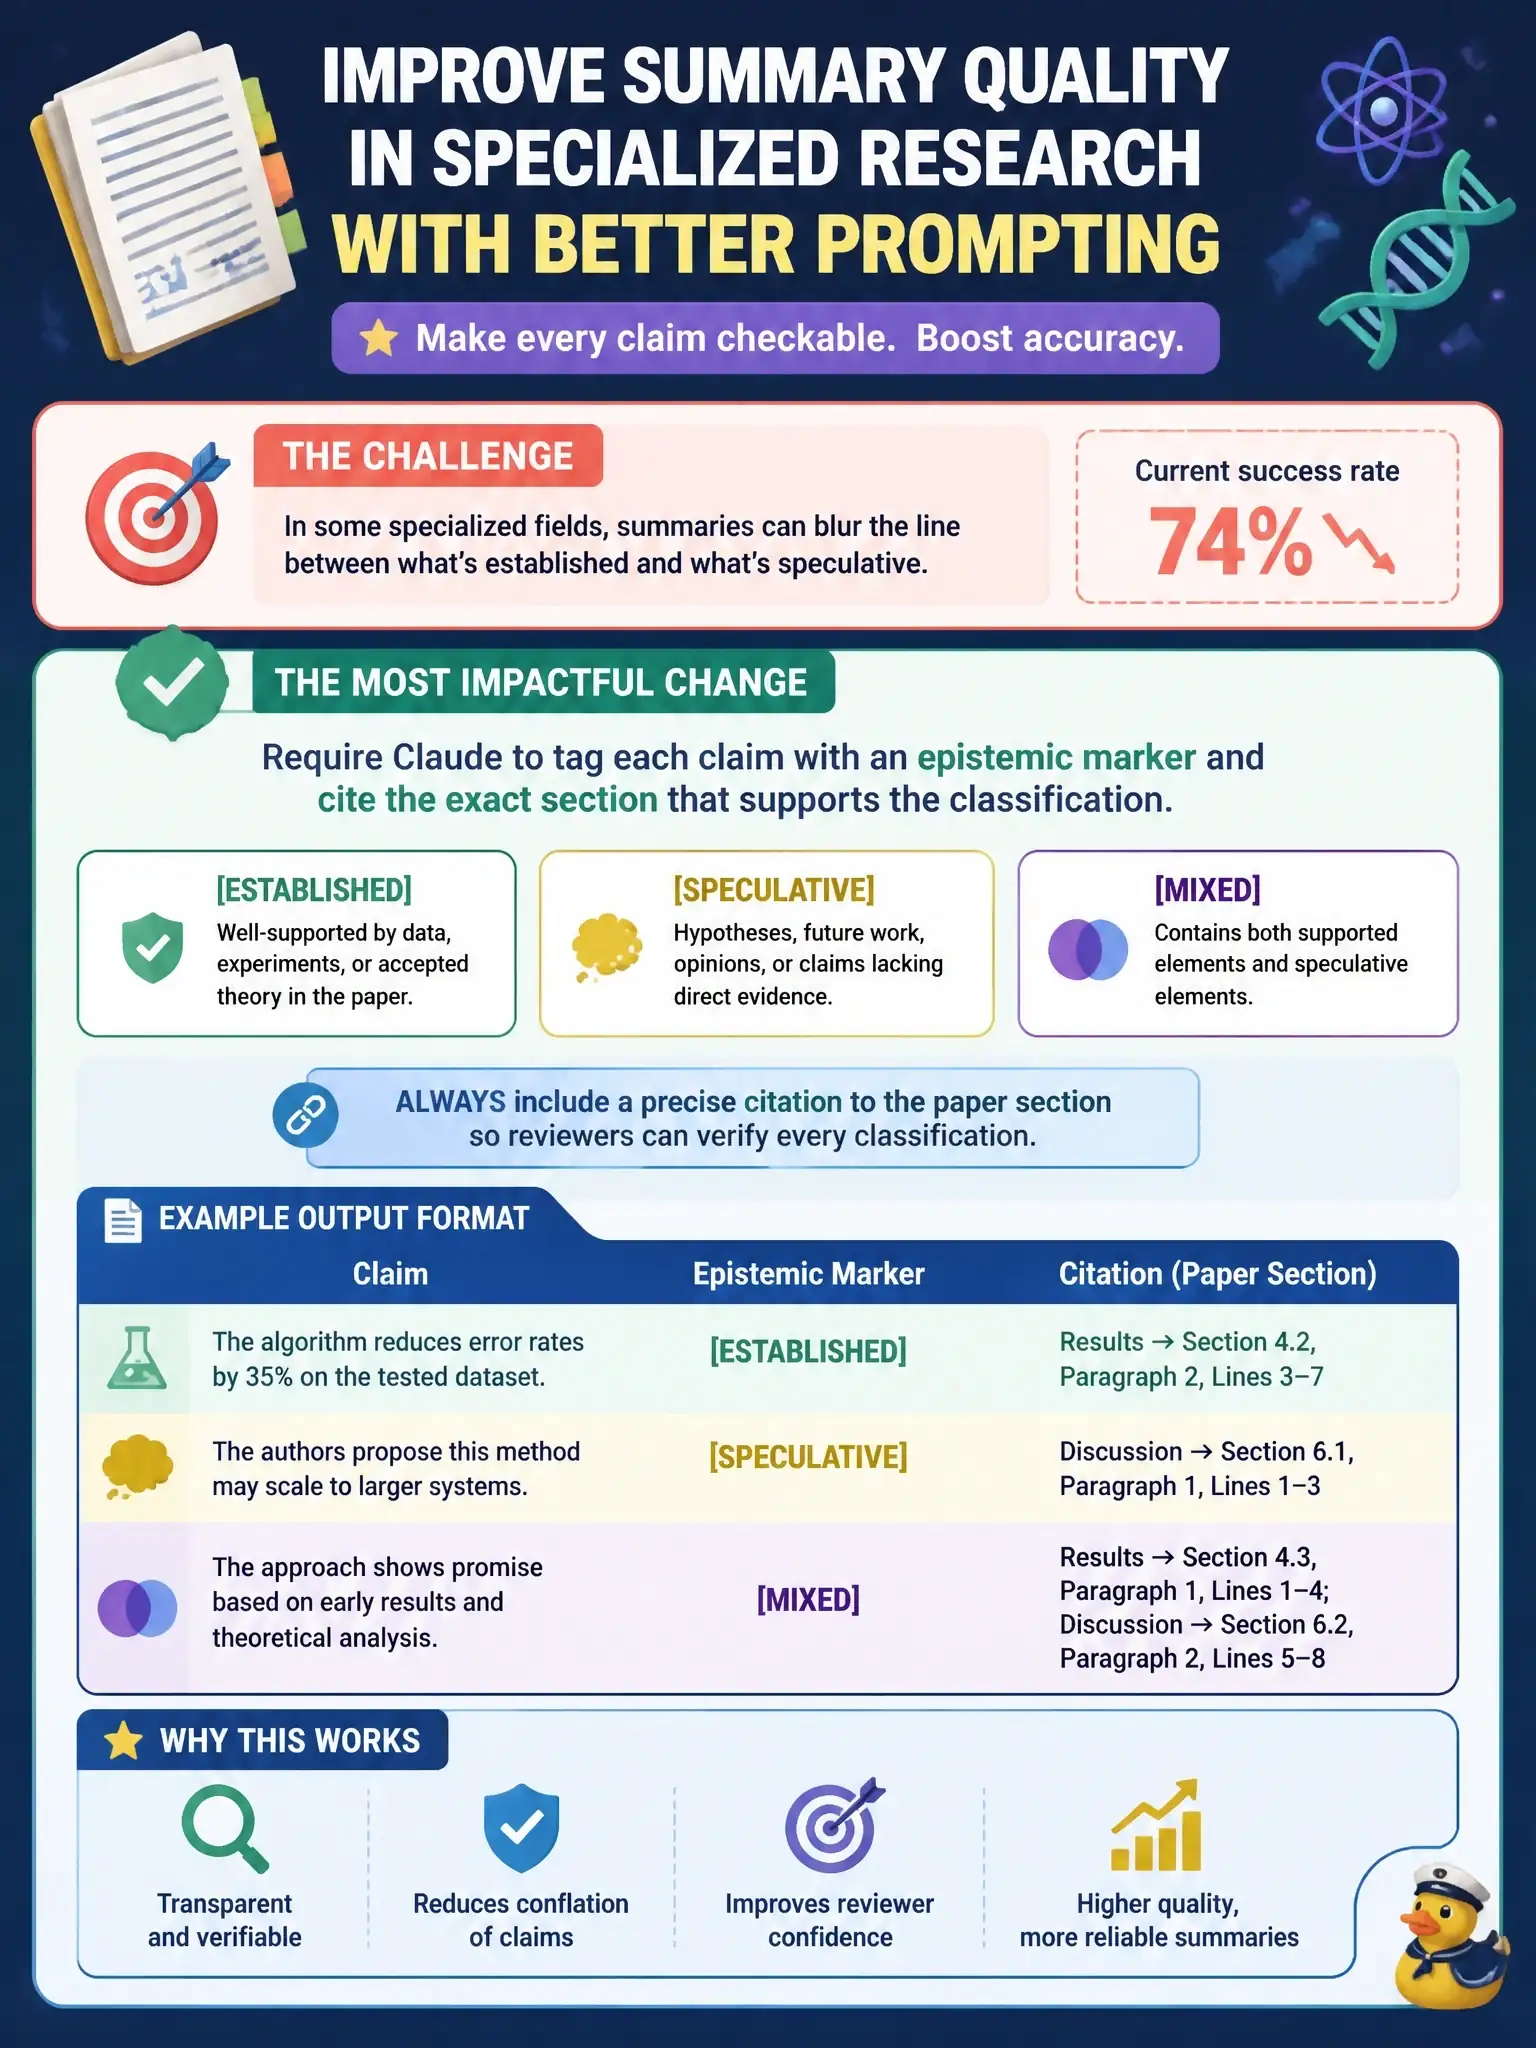
It's like asking a grader to show their work. Tagging every claim as established or speculative and pointing to the section that backs it forces a per-claim decision, and it gives your reviewers something they can actually check.
Full Explanation
Adding epistemic markers and section citations to the output schema is the change that targets the failure and meets the review requirement. The current prompt asks Claude to distinguish established from speculative claims but never says what that distinction must look like in the output, so the judgment stays implicit and easy to blur. Requiring an [ESTABLISHED], [SPECULATIVE], or [MIXED] tag on every claim forces an explicit decision per claim, and requiring a citation to the supporting paper section grounds each decision in the source, echoing the documented practice of asking Claude to quote relevant parts of long documents. The citation also lets reviewers verify each classification, which the stem makes mandatory. Few-shot examples taken from general-science papers teach summary format and length, not the established-versus-speculative judgment in specialized fields, and Anthropic's guidance says examples should mirror the actual use case. A two-step extract-then-classify pipeline adds a call and can strip the surrounding context that often decides whether a claim is speculative, and it does not by itself produce checkable citations. A definitions section restates criteria that Claude still has to apply without any traceable evidence. On the exam, match the fix to both the failure and the stated verification need. Operationally, sample tagged claims and have reviewers audit the cited sections.