
A scientific publishing platform needs to summarize research papers that frequently contain complex mathematical notation, chemical formulas, and domain-specific technical figures. The team debates whether to extract text from PDFs and send it to Claude, or to render PDF pages as images and send them to Claude's vision API. Papers average 15 pages with 8 technical figures. Which approach produces higher-quality summaries and why?
Select an answer to reveal the explanation.
Short Explanation
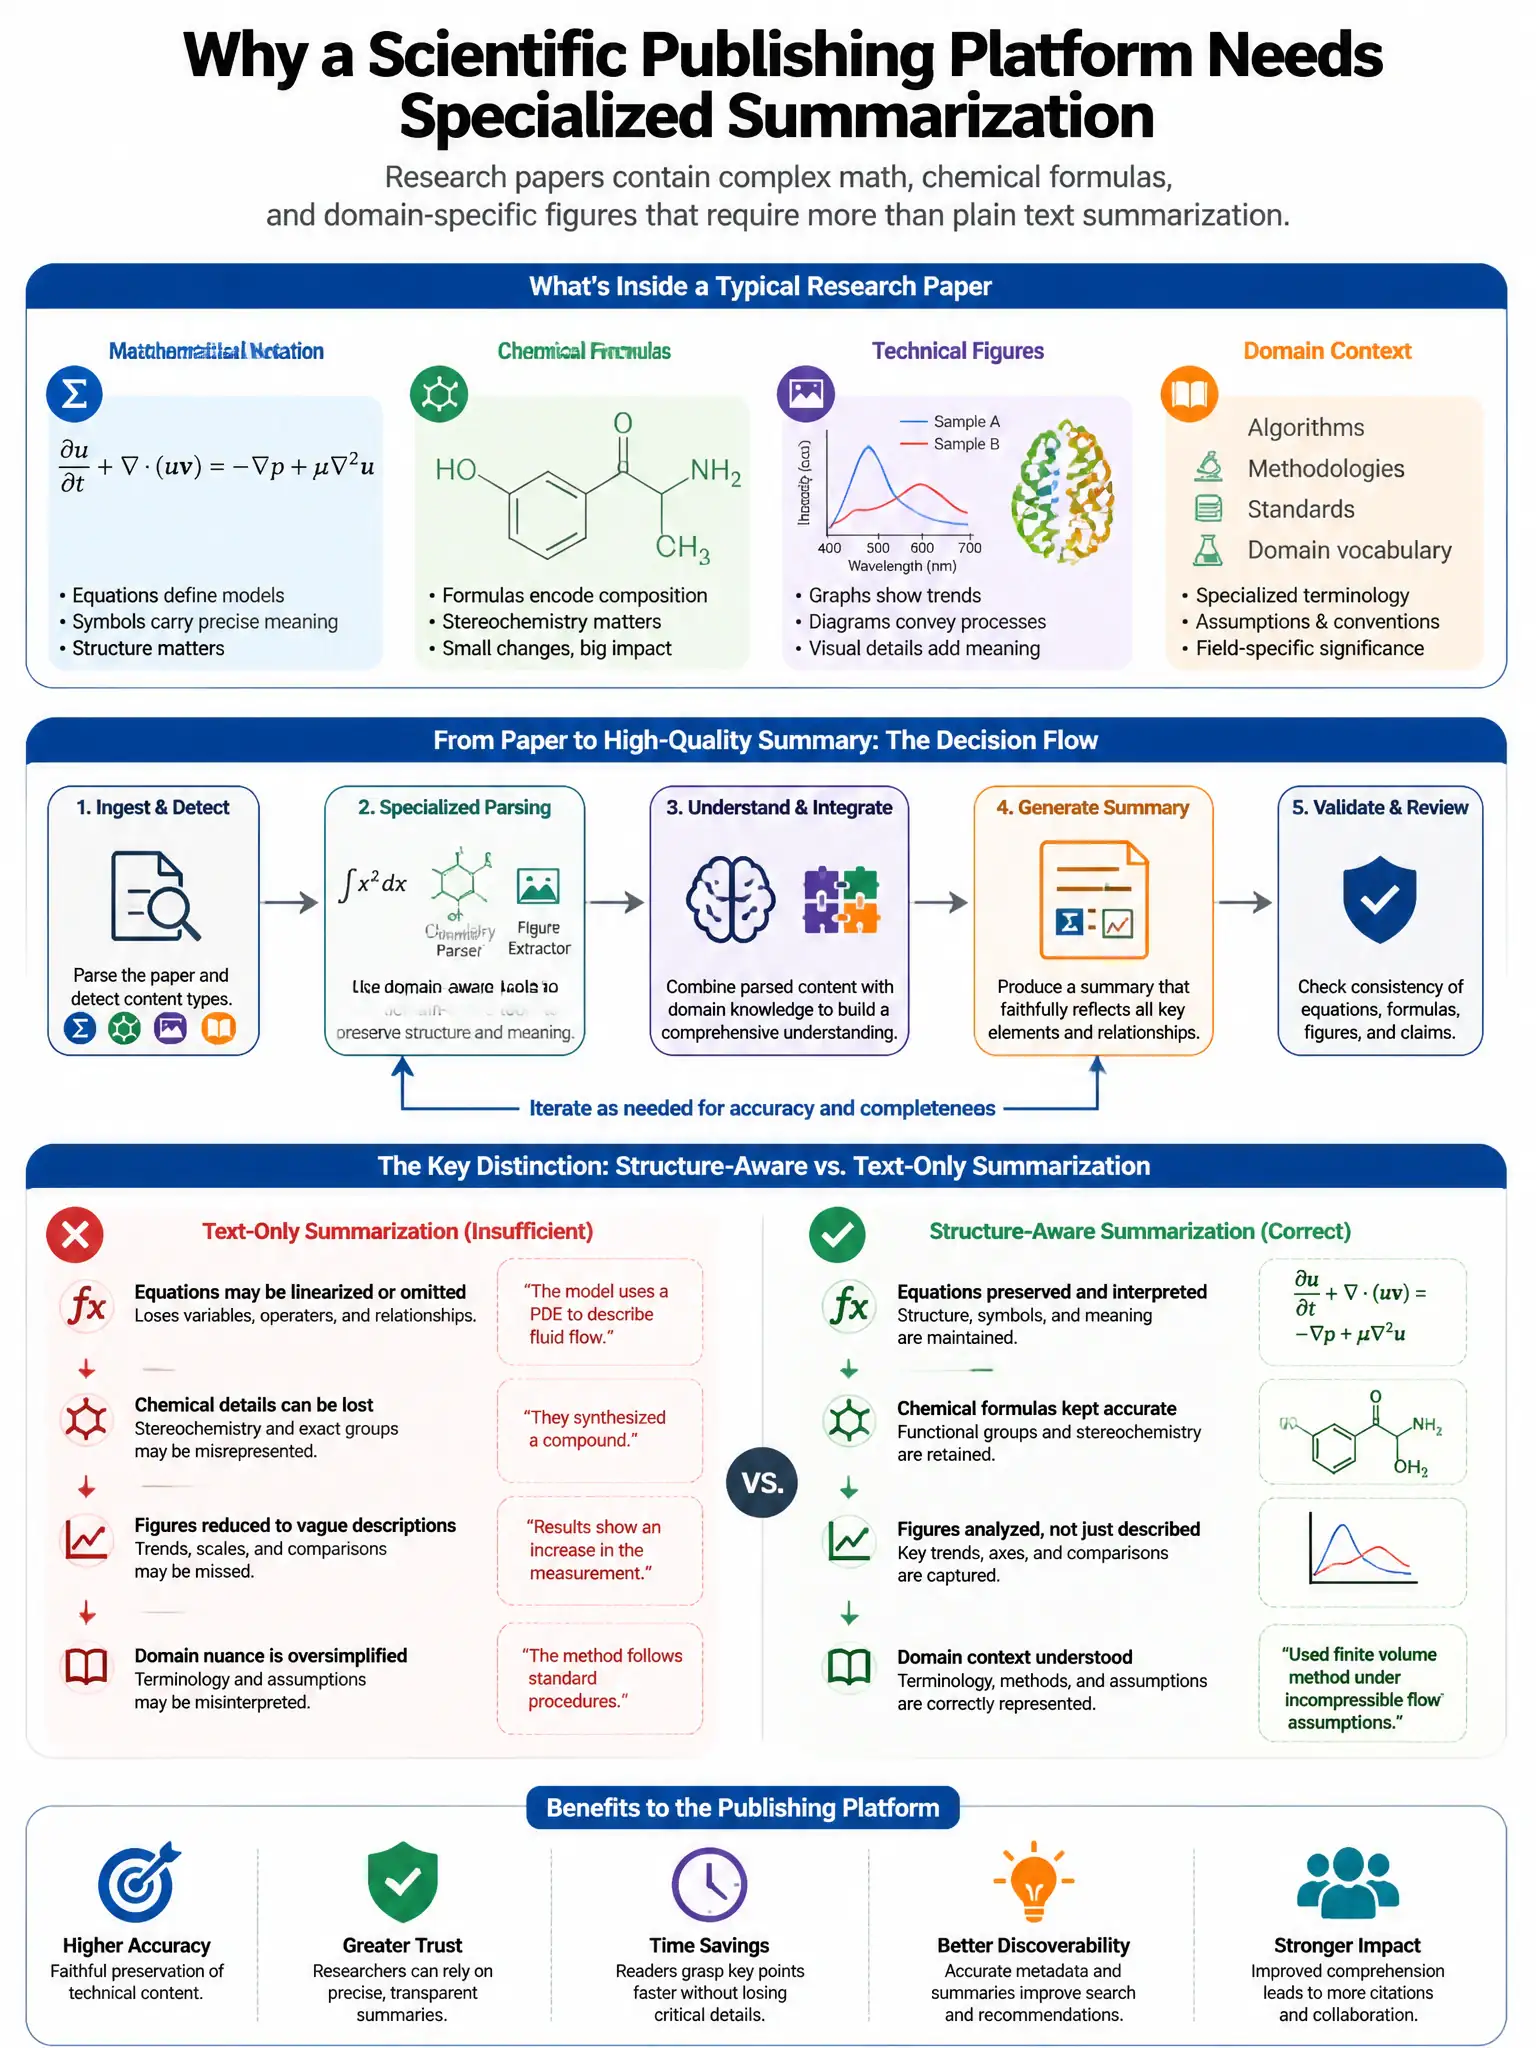
Here's the deal — for scientific papers, you should render pages as images and use vision because PDF text extraction often mangles equations, chemical structures, tables, and figure-caption links. Claude can read the rendered page and interpret figures in context, so your summaries come out better.
Full Explanation
For scientific papers, PDF text extraction is notoriously lossy on precisely the content that matters most: mathematical equations often become garbled or missing, chemical structures lose spatial relationships, table alignment breaks, and figure-caption linkages are severed. Claude's vision capability can read rendered page images and understand figures in context — seeing that a figure illustrates the mechanism described in the surrounding paragraph, or correctly interpreting a reaction scheme. This produces materially higher-quality summaries for scientific content. The claim that both approaches are equivalent for this use case underestimates how poorly standard PDF text extraction handles equations and specialized notation — this is a well-documented failure mode in scientific document processing. The claim that text extraction combined with separately extracted figure captions produces equivalent results to vision at lower cost is incorrect because captions without the actual figures lose the visual information that captions describe. The claim that text extraction is superior because LaTeX and chemical formulas parse into readable strings is also wrong; standard extraction often garbles or omits equations and loses spatial relationships in chemical structures, while vision adds value rather than unnecessary cost and latency for this content.